Command Palette
Search for a command to run...
Improving Context-Aware Preference Modeling for Language Models
Improving Context-Aware Preference Modeling for Language Models
Silviu Pitis Ziang Xiao Nicolas Le Roux Alessandro Sordoni
RPR Reasonable Preference Reversal
Abstract
While finetuning language models (LMs) from pairwise preferences has proven remarkably effective, the underspecified nature of natural language presents critical challenges. Direct preference feedback is uninterpretable, difficult to provide where multidimensional criteria may apply, and often inconsistent, either because it is based on incomplete instructions or provided by diverse principals. To address these challenges, we consider the two-step preference modeling procedure that first resolves the under-specification by selecting a context, and then evaluates preference with respect to the chosen context. We decompose reward modeling error according to these two steps, which suggests that supervising context in addition to context-specific preference may be a viable approach to aligning models with diverse human preferences. For this to work, the ability of models to evaluate context-specific preference is critical. To this end, we contribute contextconditioned preference datasets and accompanying experiments that investigate the ability of language models to evaluate context-specific preference. We use our datasets to (1) show that existing preference models benefit from, but fail to fully consider, added context, (2) finetune a context-aware reward model with context-specific performance exceeding that of GPT-4 and Llama 3 70B on tested datasets, and (3) investigate the value of context-aware preference modeling.
One-sentence Summary
Researchers from the University of Toronto, Microsoft Research, Johns Hopkins University, and MILA propose a two-step context-aware preference modeling approach that first selects a context to resolve under-specification and then evaluates preference relative to that context, decompose reward modeling error according to these two steps to justify supervising context alongside preference, release context-conditioned preference datasets showing that existing models benefit from but fail to fully consider added context, and demonstrate that their finetuned context-aware reward model achieves context-specific performance exceeding GPT-4 and Llama 3 70B on the tested datasets.
Key Contributions
- The paper introduces the RPR datasets, the first open-source context-conditioned preference datasets in which preferences are strongly determined by context, addressing the underspecification of direct preference feedback in language model alignment.
- Experiments show that existing preference models benefit from added context but frequently fail to fully consider it, sometimes ignoring context entirely, revealing a critical gap in context-specific preference evaluation.
- Finetuning a context-aware reward model achieves context-specific performance exceeding that of GPT-4 and Llama 3 70B on the tested datasets, and a single persistent context, potentially inferred from data, may be sufficient to substantially improve preference prediction.
Introduction
As language models and foundation models expand into real-world applications that require following diverse instructions and executing long-range tasks, ensuring their behavior matches human expectations becomes critical. The standard approach aligns LMs to human preferences by finetuning on pairwise preference comparisons between outputs. This method struggles with ambiguous preference queries, since user identity, goals, and other contextual factors are often unspecified. Human annotators agree only about 65 percent of the time on binary preference judgments, and when models are trained on such non-basic preferences, implicit contextual biases get embedded into the model. Prior work using the Bradley-Terry model implicitly aggregates preferences across hidden contexts with the Borda rule, which can under-serve certain subgroups.
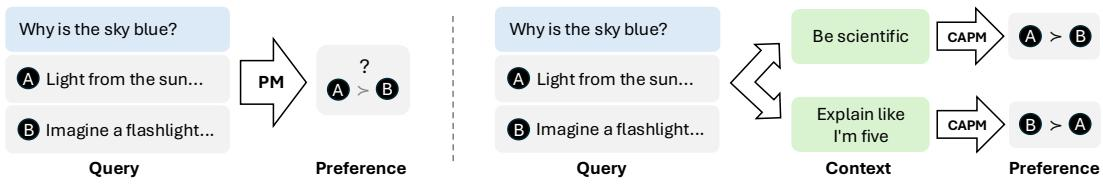
The authors propose a two-step, context-aware preference modeling framework. The first step resolves underspecification by selecting a context, and the second step evaluates preference relative to that chosen context. This decomposition explicitly surfaces the contextual assumptions underlying preference, shifts alignment from pure preference modeling to a hybrid of preference modeling and context supervision, and enables pluralistic adaptation to diverse users. The authors prove an upper bound on reward modeling error as the sum of context inference error and context-specific reward modeling error, which justifies supervising context as a viable alignment path. To support this, they introduce open-source context-conditioned preference reversal (RPR) datasets where preference for a given prompt flips under an alternative context. Their experiments show that current models benefit from added context but sometimes fail to fully weigh it, and that finetuning on RPR data substantially improves context-specific preference prediction. They also demonstrate that a single persistent context, such as a user profile or system prompt, can be inferred from as few as 16 to 32 expressed preference samples and applied across many queries.
Dataset
The authors introduce the Reasonable Preference Reversal (RPR) datasets, a set of synthetic preference datasets designed to measure whether preference prediction is sensitive to context. The datasets include over 20,000 paired tuples of prompt, context, and preference judgments, formatted as (x,z,y1≻y2). The samples are constructed so that preference between two completions for the same prompt is entirely ambiguous without context; for every context, there is an alternative context for which the preference reverses. This design ensures that performance on the dataset is determined solely by the model's ability to interpret the context.
The dataset comes in two base versions:
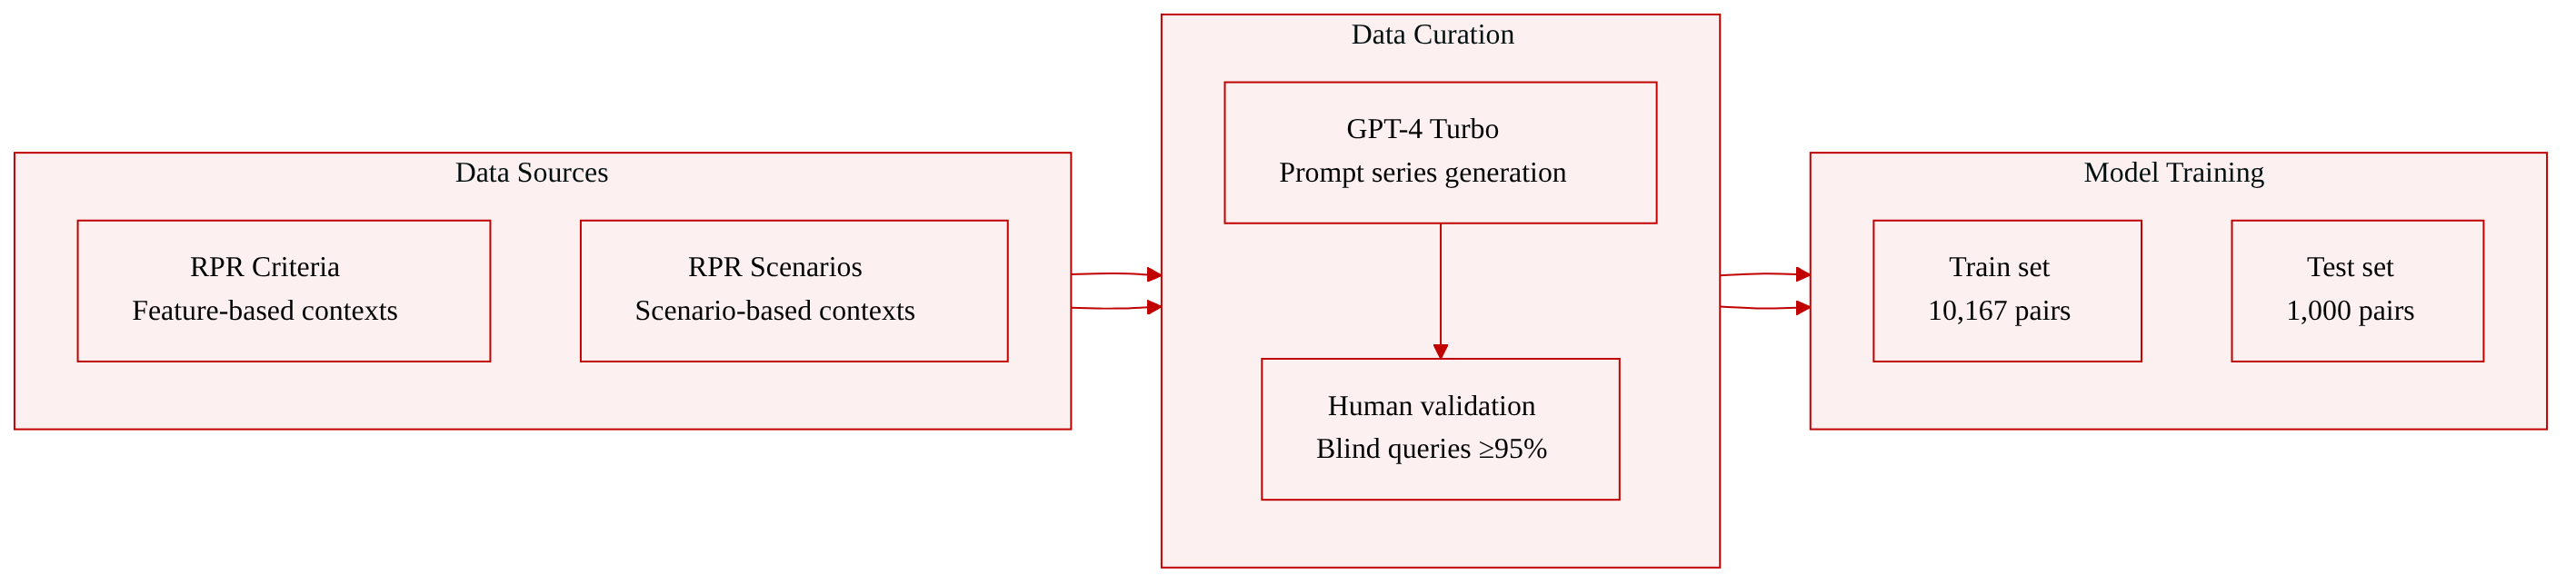
- RPR Criteria: Context is a short sentence describing which features are important, such as "Uses a formal and professional tone that emphasizes the technical aspects of C++".
- RPR Scenarios: Context describes the scenario that led to the underspecified prompt, such as a marketing manager preparing for a product launch.
The data was generated by GPT-4 Turbo using a series of prompts designed to maximize validity and avoid invalid or ambiguous samples. Small-scale human validation through blind preference queries found agreement rates of at least 95% on both splits.
The dataset is divided into a training set of 10,167 paired samples and a test set of 1,000 paired samples, with no overlap between train and test prompts. The paper also extends the dataset with user profiles in a separate section. The datasets are publicly available at https://huggingface.co/datasets/microsoft/rpr.
Method
The authors introduce an intent-utility formalism to model user-LM interactions, defined by the tuple (T,X,Y,u), where T denotes the space of intents, X is the space of prompts, Y is the space of completions, and u:T×Y→R is a scalar utility function. Following the standard Bradley-Terry model, the probability of preferring completion y1 over y2 given a specific intent i is expressed as:
p(y1≻y2∣i)=σ(u(i,y1)−u(i,y2)),where σ is the logistic function. A critical distinction in this formalism is that preference and utility are defined with respect to intents rather than prompts. A user with intent i selects a prompt x∈X to query the model, and an annotator presented with a preference query (x,y1,y2) implicitly infers intent i from x, then samples a preference from the Bernoulli distribution B[p(y1≻y2∣i)].
Both users and annotators may hold a distribution over intents rather than a single fixed intent. The authors assume a base distribution pˉ(i) over possible intents, along with a conditional distribution p(x∣i) over prompts given intents, which induces a natural inference distribution p(i∣x) for any prompt. Under this view, the prompt is a partial specification of intent; additional context z∈Z, where Z forms a discrete partition of the intent space, can be appended to obtain an extended prompt (x,z). To measure utility under a distribution p of intents, the authors adopt an expected utility model:
u(p,y)=Ei∼p[u(i,y)].Although standard RLHF does not align with this model, it satisfies desirable axioms for "ideal" preference annotation. Defining u(x,y):=u(p(⋅∣x),y), linearity of expectation yields the decomposition u(x,y)=∑z∈Zp(z∣x)u((x,z),y). For convenience, the utility difference Δ(⋅,y1,y2):=u(⋅,y1)−u(⋅,y2) also decomposes linearly:
Δ(x,y1,y2)=z∑p(z∣x)Δ((x,z),y1,y2).In standard RLHF, a dataset of prompt-preference tuples D={(x,y1≻y2)} is used to learn a utility estimator u^:X×Y→R, conventionally referred to as the reward model. The authors posit the existence of a context inference model p^(z∣x) that satisfies the analogous relation:
u^(x,y)=z∑p^(z∣x)u^((x,z),y).While standard RLHF never learns such an estimator, the analysis assumes it exists either implicitly or explicitly, and that u^(x,y) is computed via the decomposition rather than by direct evaluation. Since u^ is only unique up to constant shifts, accuracy is measured via the utility difference estimator Δ^(x,y1,y2):=u^(x,y1)−u^(x,y2).
The absolute error for a particular preference query can be bounded as follows. Letting Δz denote Δ((x,z),y1,y2), the authors derive:
Δ(x,y1,y2)−Δ^(x,y1,y2)≤Context-weighted prediction errorz∑p(z∣x)Δz−Δ^z+Preference-weighted inference errorz∑Δ^z∣p(z∣x)−p^(z∣x)∣.The equality follows from adding and subtracting ∑zp(z∣x)Δ^z and rearranging, and the final inequality applies the triangle inequality multiple times. In the case where a single context is assumed (i.e., p(z=c):=1) and a single prediction is made (p^(c^)=1), the bound simplifies to:
Δ(x,y1,y2)−Δ^(x,y1,y2)≤True context prediction errorΔc−Δ^c+Subjective difference: true vs predicted contextΔ^c−Δ^c^.Both the general and specific bounds formalize a central claim: if predictions can be made accurately given the true context (or context distribution), then the preference modeling problem reduces to a context inference problem.
The upper bound decomposes total error into a context-weighted prediction error and a preference-weighted inference error. At one extreme, setting Z=∅ recovers standard preference modeling, where context inference error is zero and all error stems from preference prediction given the prompt alone. At the other extreme, letting Z be degenerate such that z directly encodes the preferred response (e.g., "the preferred response is y") makes the prediction error vanish, but the context inference problem becomes equivalent to generation. Between these extremes, the authors conjecture a smooth trade-off between prediction error and inference error, which would hold if a single context can disambiguate a range of different preference queries. Their experiments support this conjecture: conditioning on specific criteria outperforms conditioning on more abstract scenarios, which in turn outperforms conditioning on a single user profile applied to all queries at once.
When the utility estimator u^ is sufficiently accurate given additional context, the preference modeling problem is largely reducible to context specification. In this regime, the authors suggest allocating annotation resources toward specifying additional context rather than having annotators rank completions for ambiguous prompts. These annotations can then train a context inference model that disambiguates prompts. The authors hypothesize that the cardinality of the context space is smaller than that of the completion space given a prompt, making joint context-preference annotation more data-efficient than preference annotation alone. The effectiveness of this approach hinges on whether language models are genuinely sensitive to added context, a question the authors evaluate on real data and address by training context-conditioned reward models.
Experiment
The experiments evaluated context-aware preference modeling across multiple datasets and models, including reward models, generative judges, and a finetuned Mistral CARM, using agreement metrics with context-conditioned preferences. Results showed that access to context generally improves performance, though models sometimes ignore adversarial contexts, revealing room for improvement. Finetuning on the RPR datasets markedly enhanced context-specific performance, matching or exceeding larger models like GPT-4 Turbo, and the models generalized to augmented real-world preference datasets. Finally, a single inferred user profile could recover about 80% of preference agreement, with only 2-4 samples resolving default biases and 16-32 samples recovering most of the benefit of ground truth context.
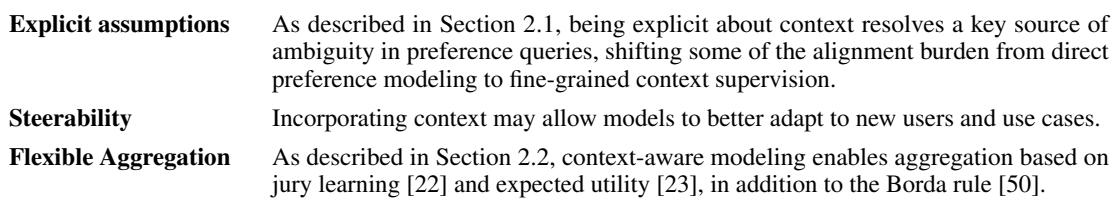
Context-aware preference modeling addresses ambiguity by making implicit assumptions explicit, improves adaptability to new users and use cases, and enables flexible aggregation via methods like jury learning and expected utility. Finetuning a context-aware model also yields marked improvements in context-specific performance, often matching or exceeding larger baseline models. Making context explicit resolves a key source of ambiguity in preference queries, shifting alignment burden to fine-grained context supervision. Incorporating context allows models to better steer toward new users and use cases. Aggregation flexibility expands beyond the Borda rule to include jury learning and expected utility. A finetuned context-aware model shows better context-specific performance than its base model, rivaling or surpassing larger models like GPT-4 Turbo and Llama 3.
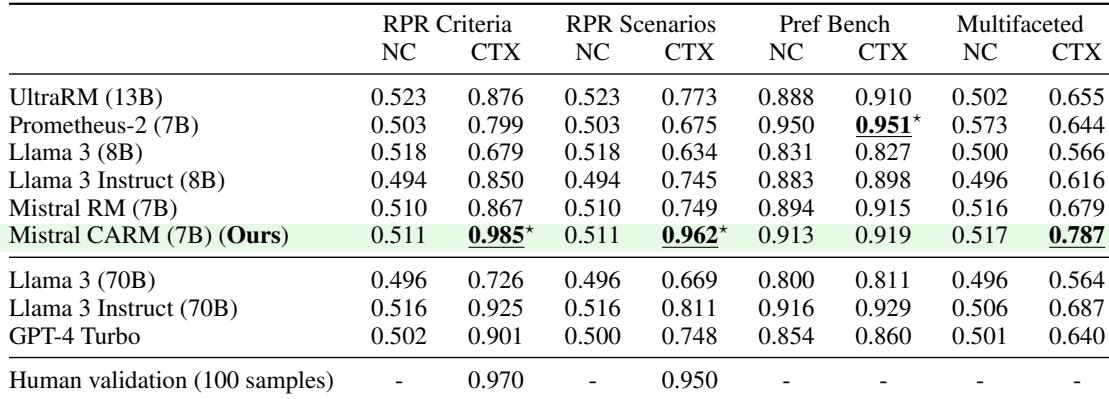
Adding context generally improves preference evaluation across datasets, but the benefit is most pronounced when preferences are ambiguous without context. A model finetuned on the RPR training sets substantially outperforms its unfinetuned counterpart on test sets. Larger and instruction-tuned models tend to gain more from added context. Access to context improves performance across all tested datasets, with the greatest gains on datasets where preferences are ambiguous without context. Finetuning on RPR training sets yields substantially better test performance compared to the unfinetuned model. Larger and instruction-tuned models benefit more from added context.
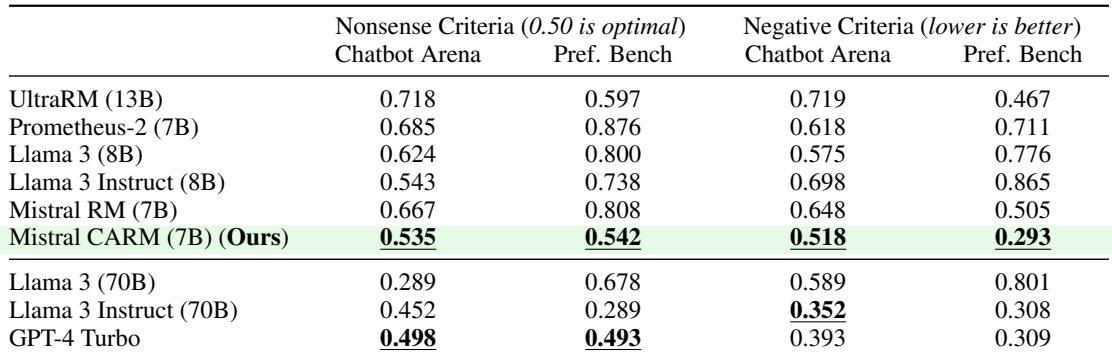
Current models are largely insensitive to strongly phrased adversarial context, often failing to adjust their predictions even when it should reverse or randomize them. The finetuned CARM model outperforms other small models on both adversarial criteria, yet still falls short of optimal behavior, indicating substantial room for improvement. Even with strongly adversarial context, many models retain near-baseline scores, showing they often ignore added instructions. The finetuned CARM achieves the best performance among small models on both nonsense and negative criteria. Performance across all models remains far from optimal, especially on the nonsense criterion where random scoring would yield 0.50.
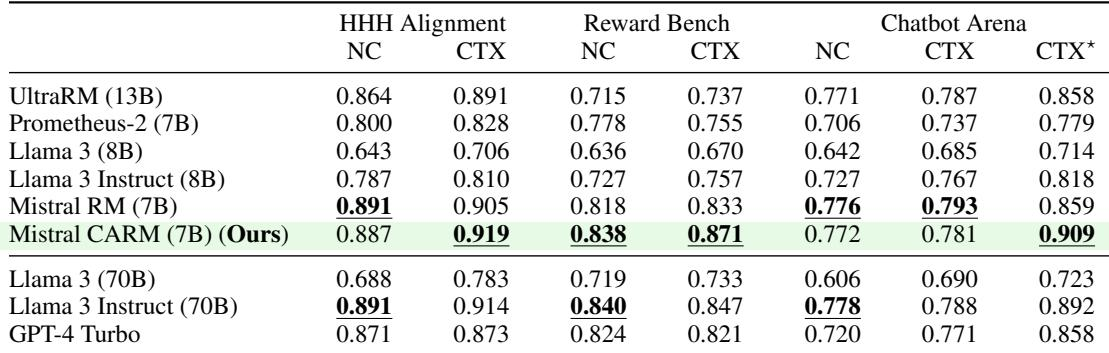
Adding context to preference datasets generally improves model performance across all tested models, but the finetuned context-aware reward model (CARM) stands out among small models when given high-quality or privileged context. CARM also shows consistent gains over its base model in most context-augmented settings, matching or exceeding the performance of larger models. The finetuned CARM outperforms other small models on context-augmented preference tasks, especially when the context includes privileged preference information. Context generally boosts performance for most models, but CARM's improvements are more pronounced, particularly on the HHH and Reward Bench datasets with context. CARM's context-specific gains over its base model are largest when the context is inferred from both the prompt and the expressed preference, indicating its strength in leveraging rich contextual signals.
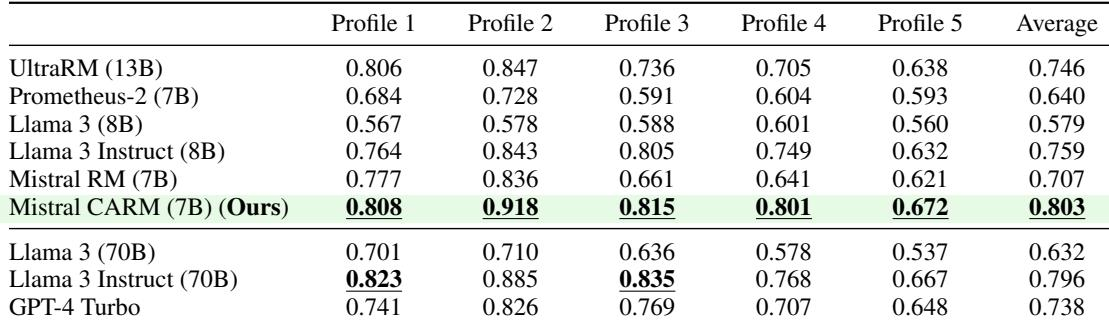
Experiments with five synthetic user profiles show that a single context can effectively disambiguate preferences across many prompts. The finetuned CARM model and Llama 3 Instruct achieved the highest agreement with GPT-4's profile-conditioned labels, surpassing GPT-4 itself. This suggests that context-aware finetuning can improve preference modeling even when the context is a broad user profile. Finetuned CARM and Llama 3 Instruct outperformed GPT-4 in recovering profile-conditioned preferences. Profile-conditioned performance varied strongly across profiles, with the best models reaching about 80% agreement. Smaller finetuned models matched or exceeded larger models, indicating that targeted finetuning can offset model size advantages.
Across experiments, incorporating explicit context into preference modeling consistently improves evaluation accuracy, particularly for ambiguous preferences, with finetuned context-aware reward models (CARM) often matching or exceeding larger baselines like GPT-4 and Llama 3. However, models remain largely insensitive to strongly adversarial context, and performance still falls short of optimal behavior, indicating room for improvement. In synthetic user profile tests, a single context effectively disambiguates preferences, with finetuned CARM and Llama 3 Instruct outperforming GPT-4 in recovering profile-conditioned preferences, showing that targeted finetuning can offset model size advantages.