HyperAI
Command Palette
Search for a command to run...
Papers
Daily updated cutting-edge AI research papers to help you keep up with the latest AI trends
papers
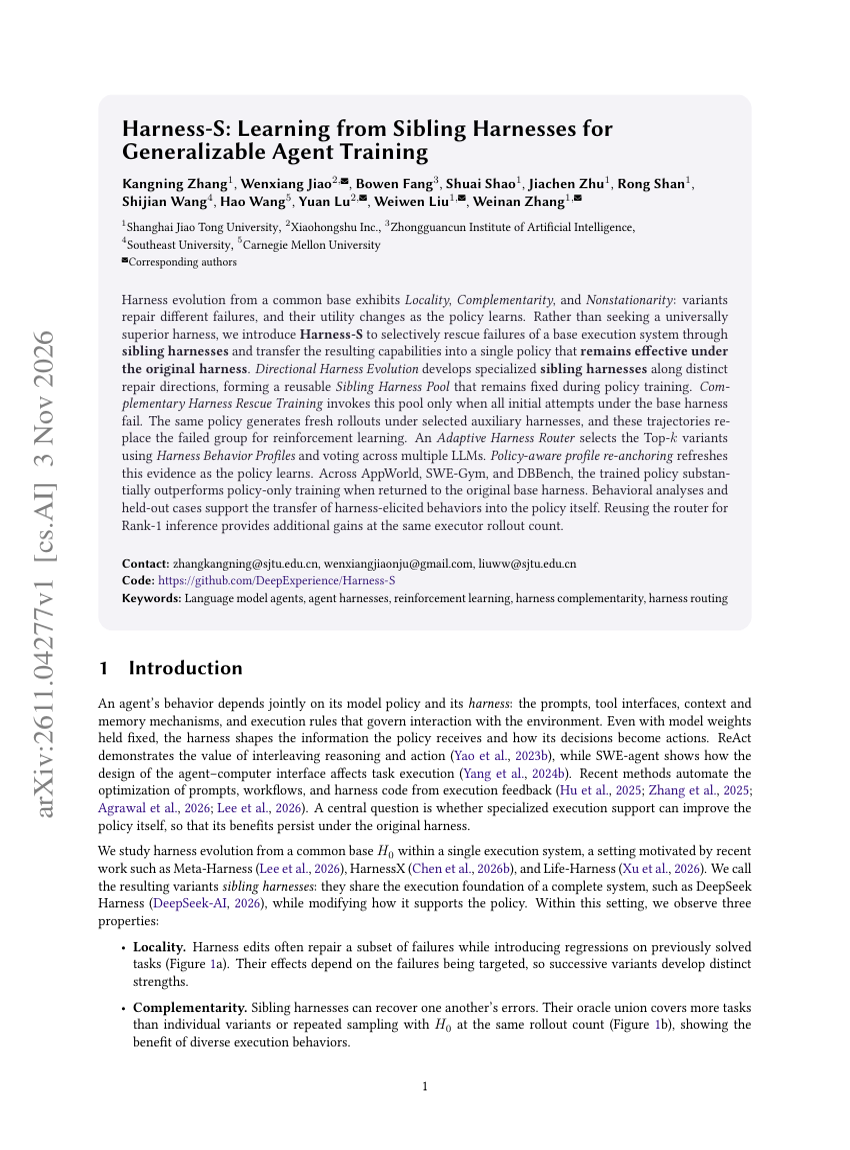
Harness-S: Learning from Sibling Harnesses for Generalizable Agent Training
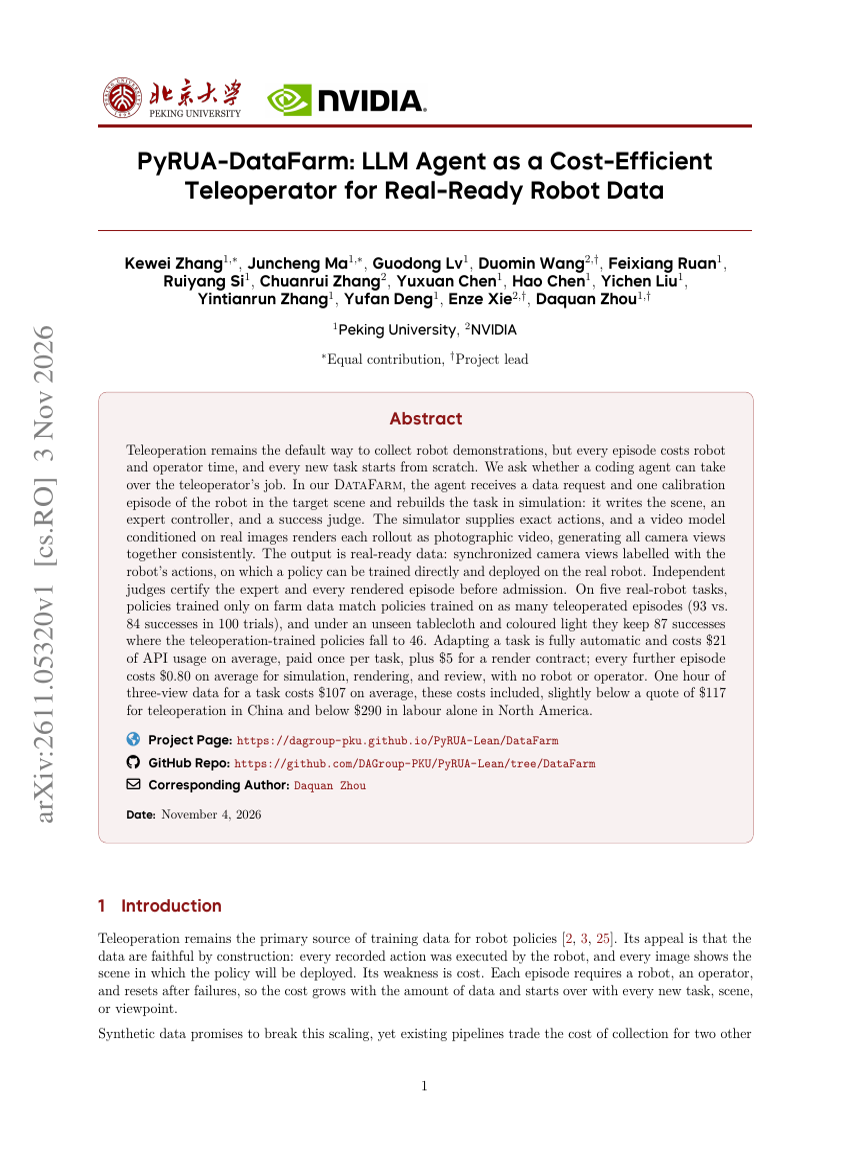
PyRUA-DataFarm: LLM Agent as a Cost-Efficient Teleoperator for Real-Ready Robot Data
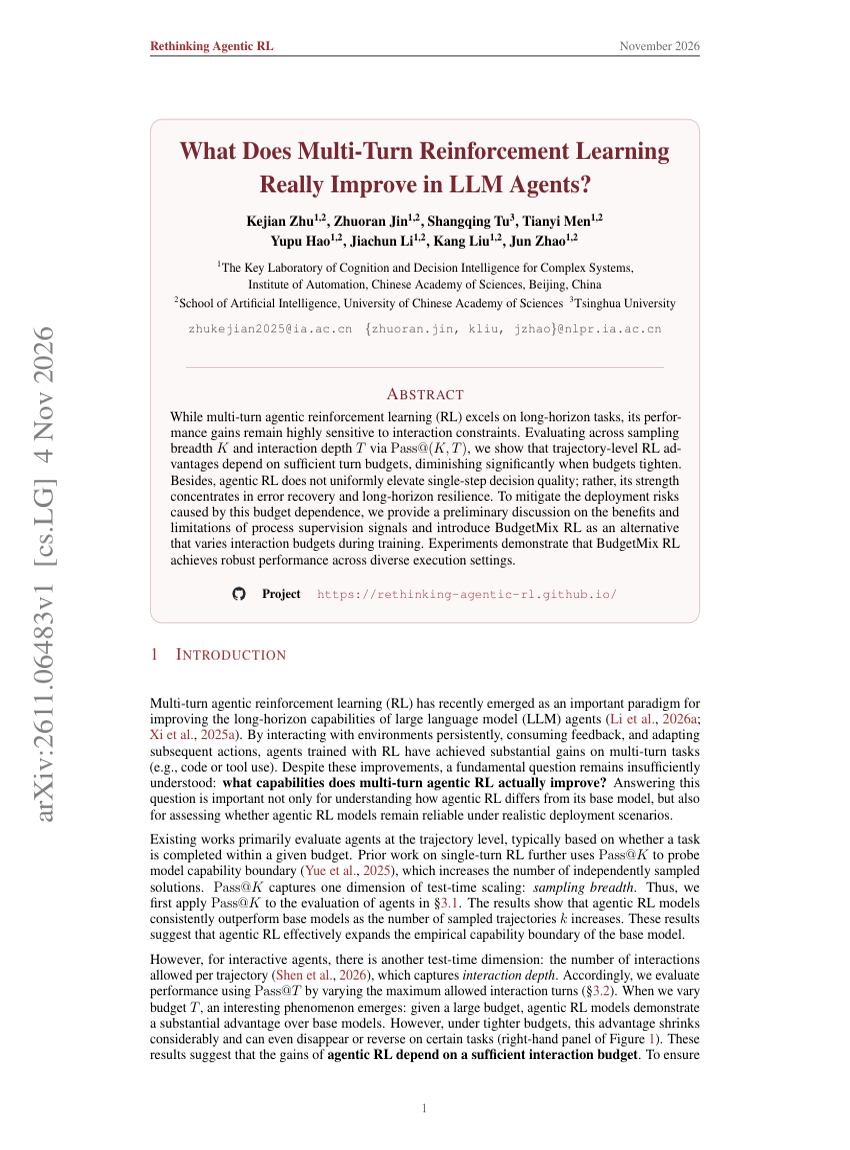
What Does Multi-Turn Reinforcement Learning Really Improve in LLM Agents?
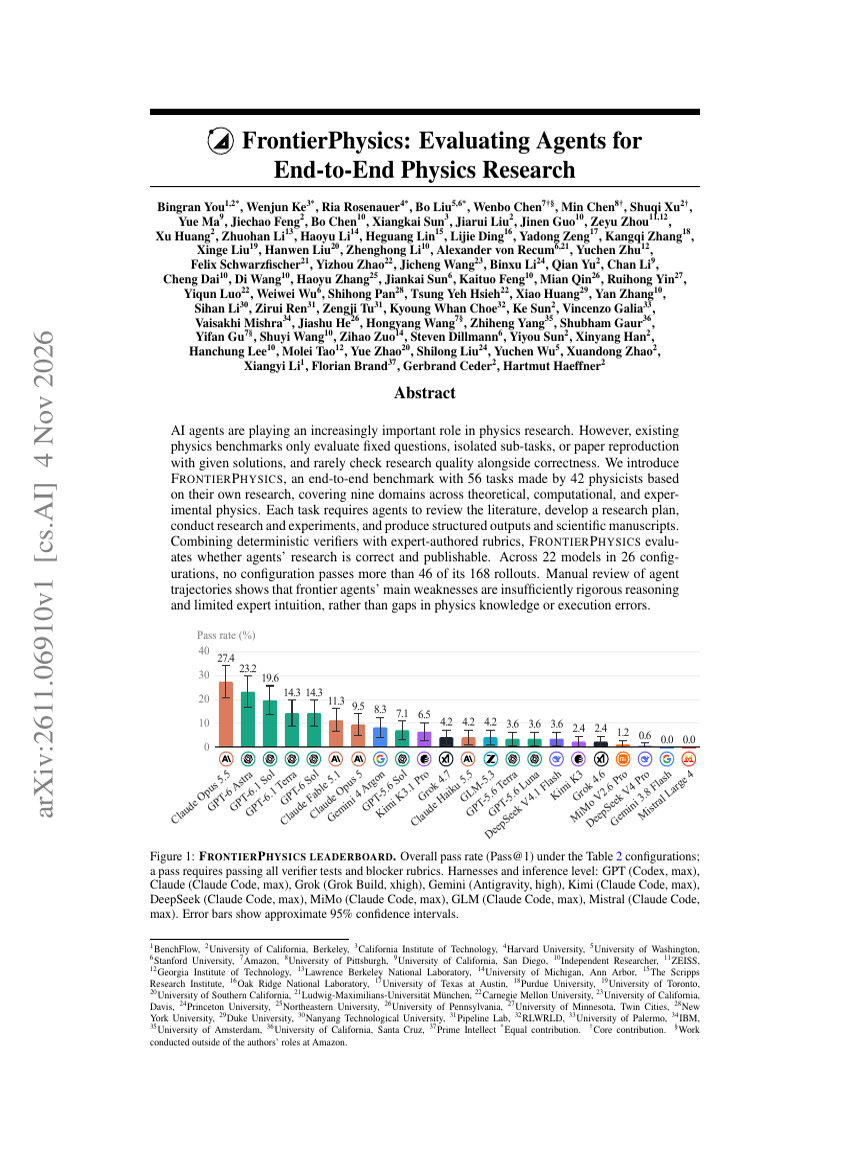
FrontierPhysics: Evaluating Agents for End-to-End Physics Research
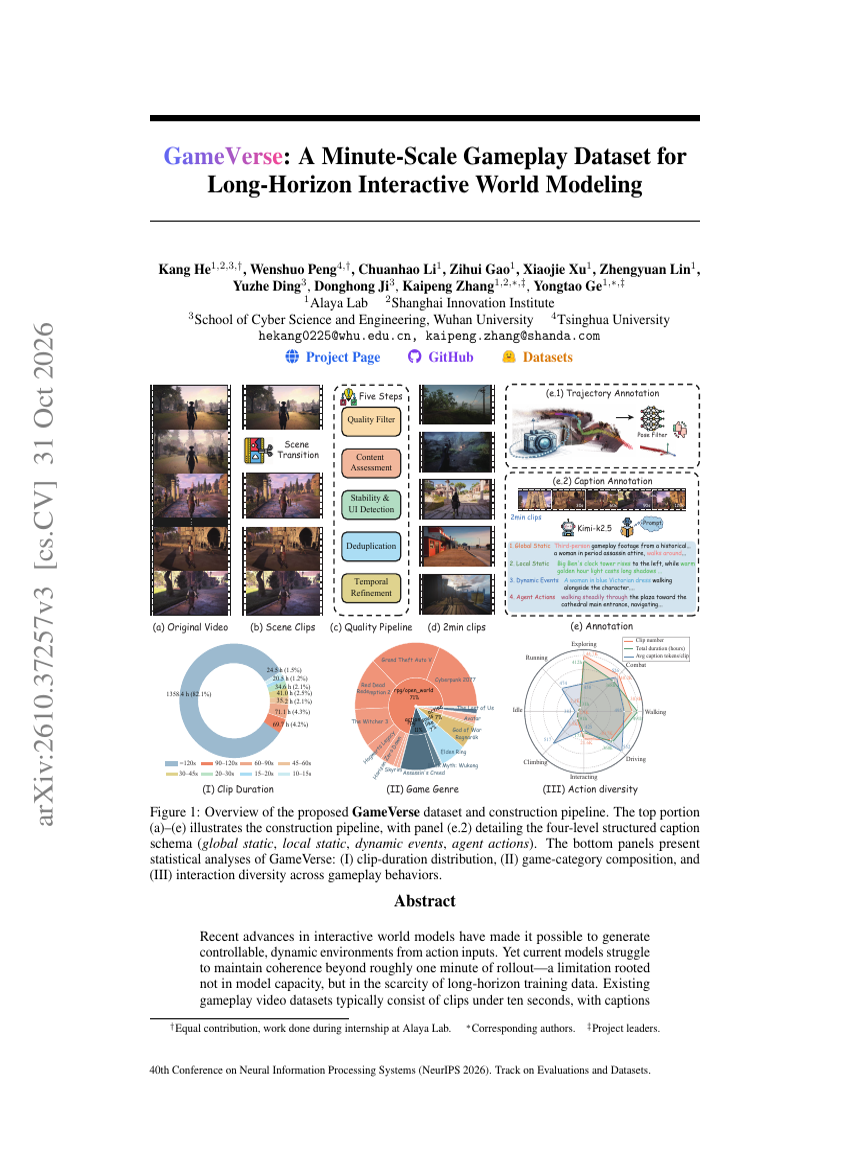
GameVerse: A Minute-Scale Gameplay Dataset for Long-Horizon Interactive World Modeling
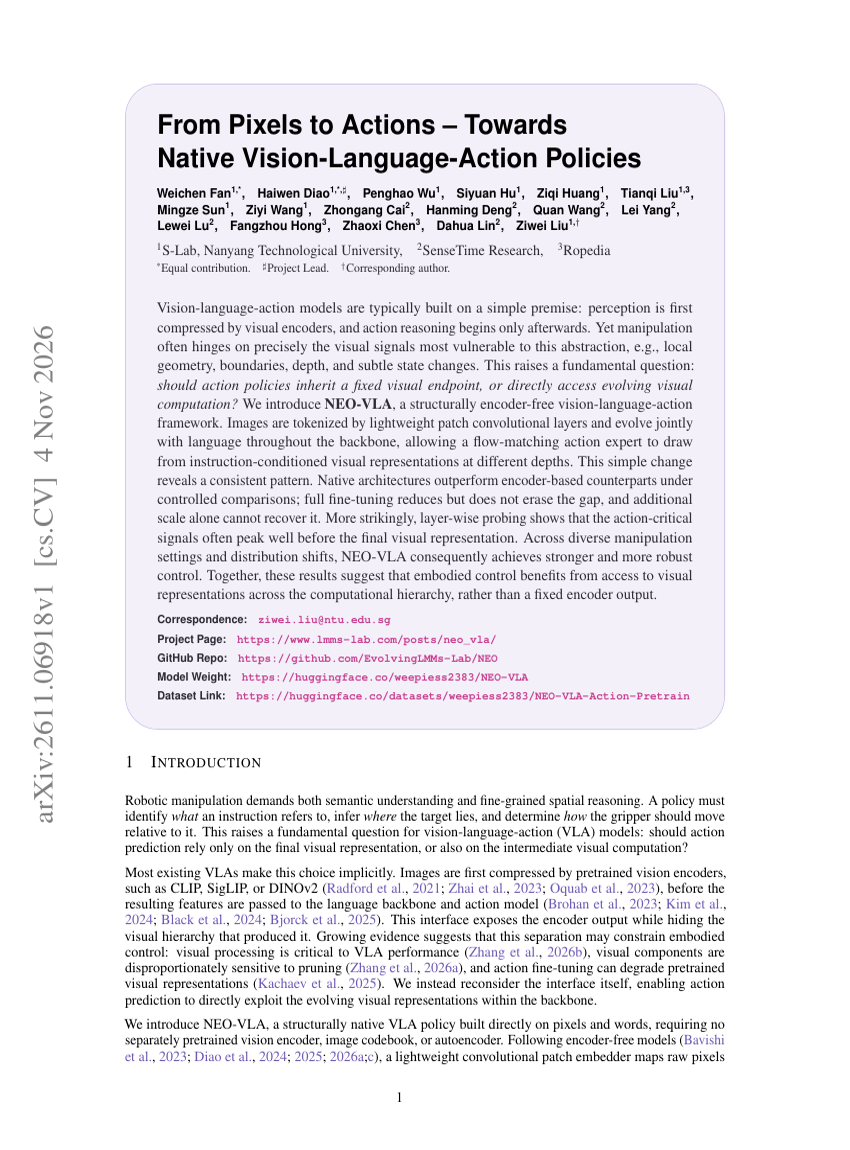
From Pixels to Actions – Towards Native Vision-Language-Action Policies
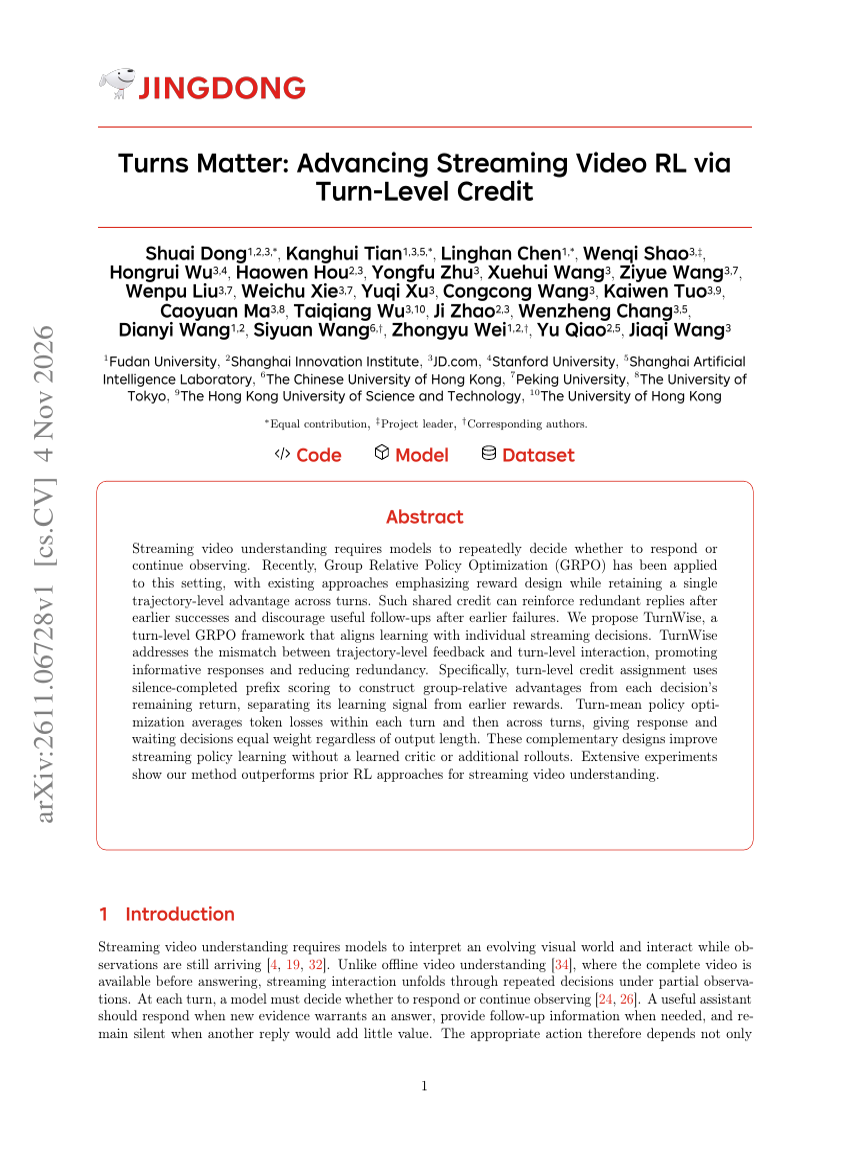
Turns Matter: Advancing Streaming Video RL via Turn-Level Credit
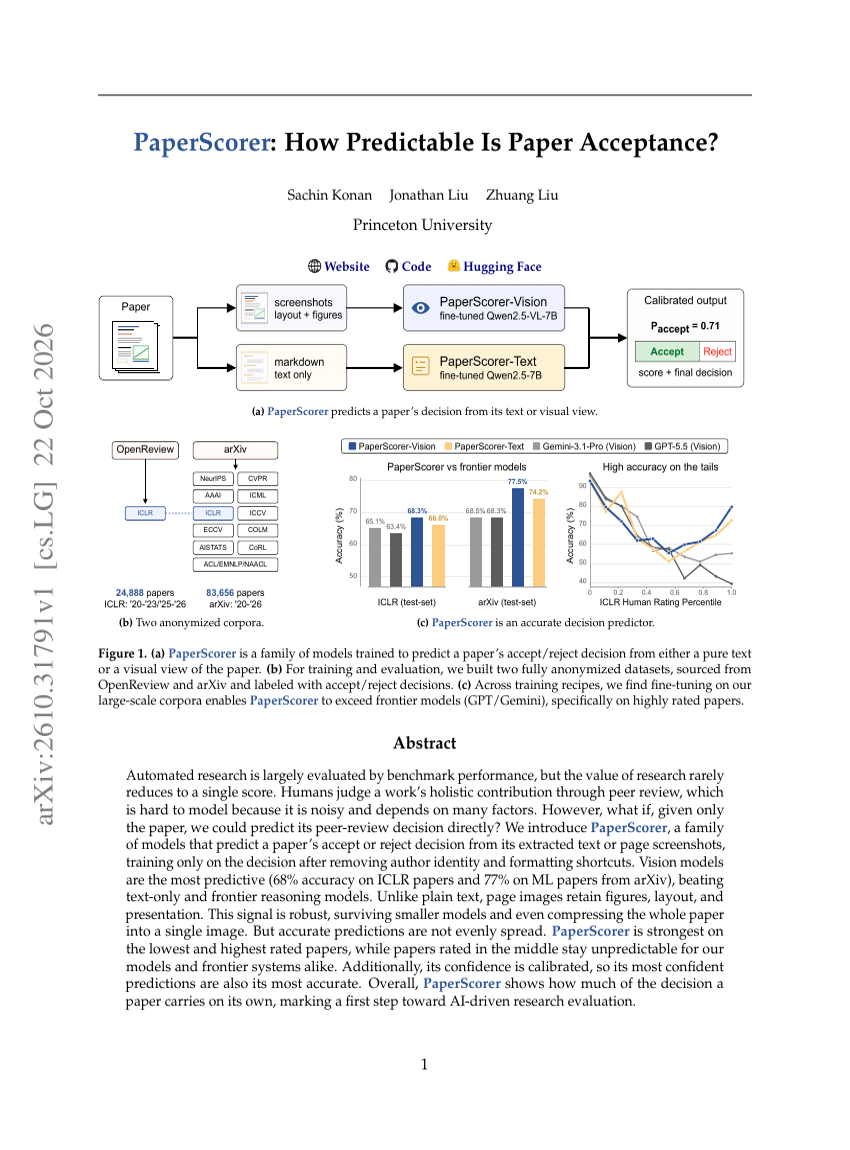
PaperScorer: How Predictable Is Paper Acceptance?
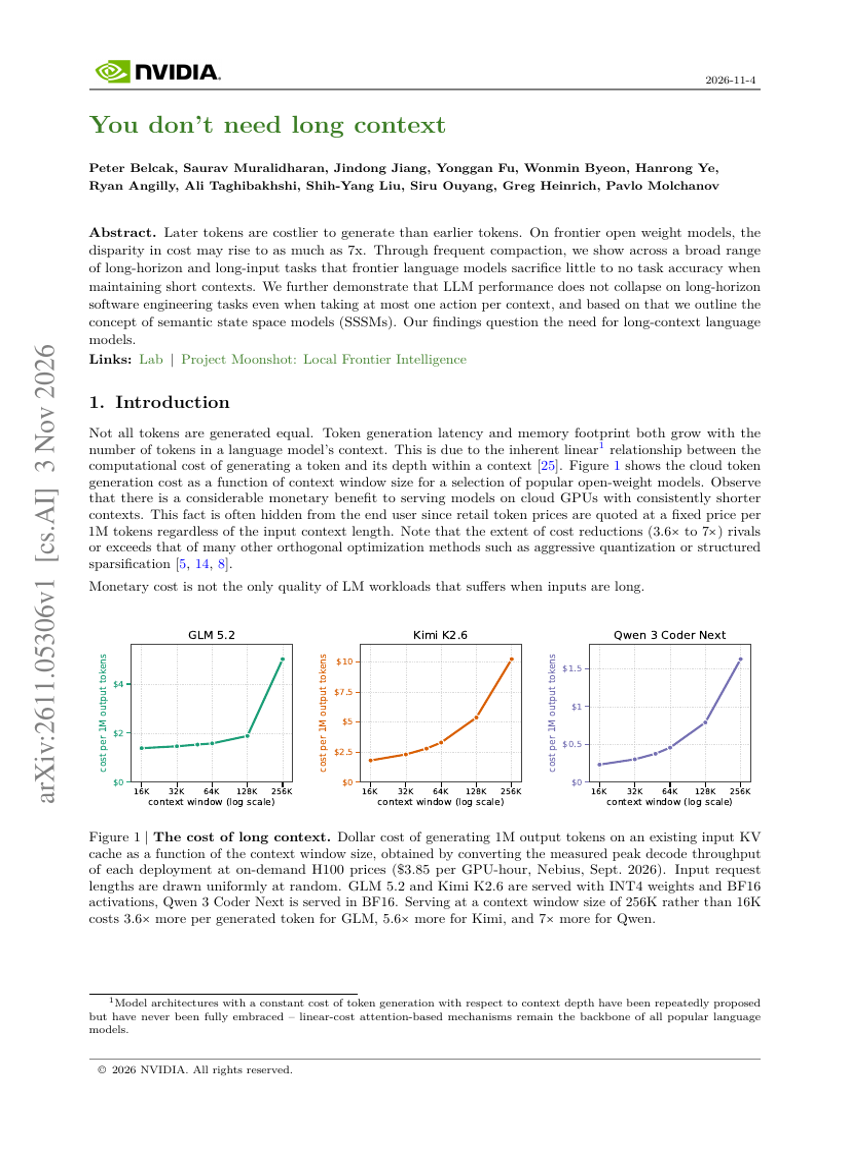
You don’t need long context
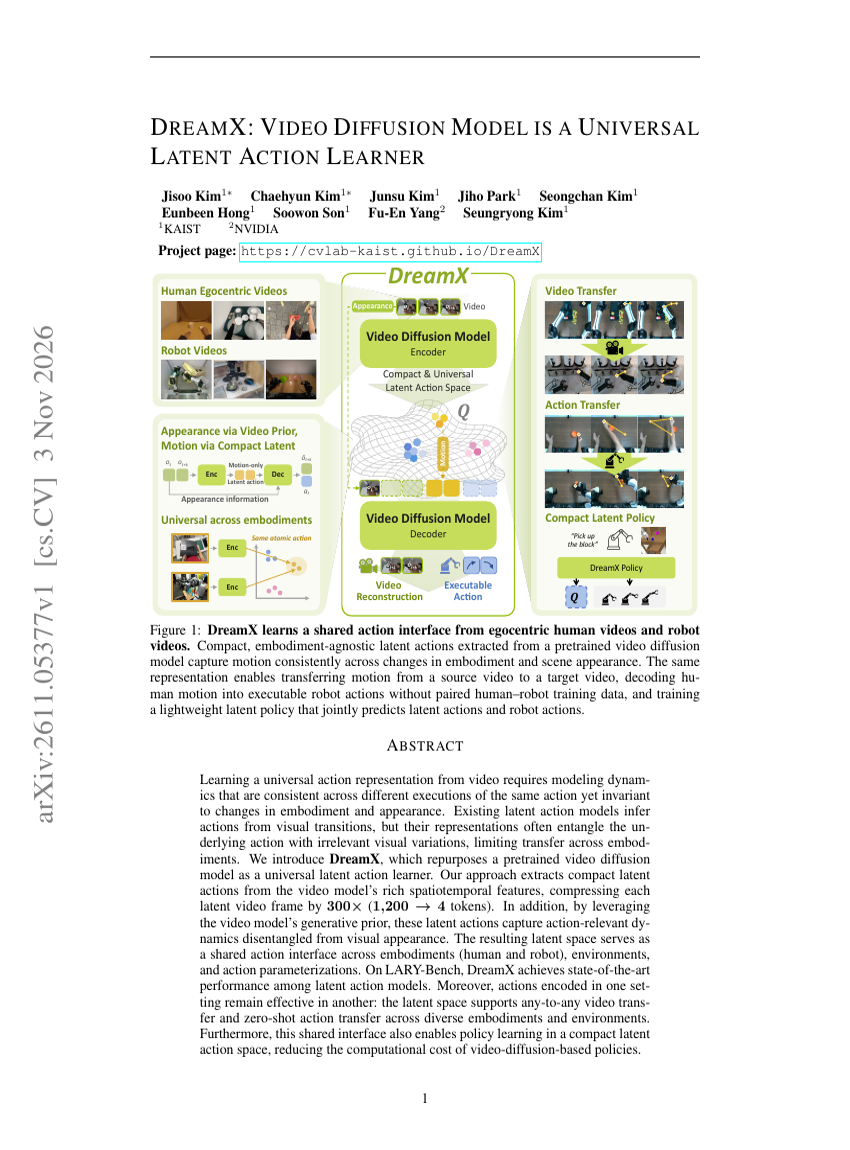
DREAMX: VIDEO DIFFUSION MODEL IS A UNIVERSAL LATENT ACTION LEARNER
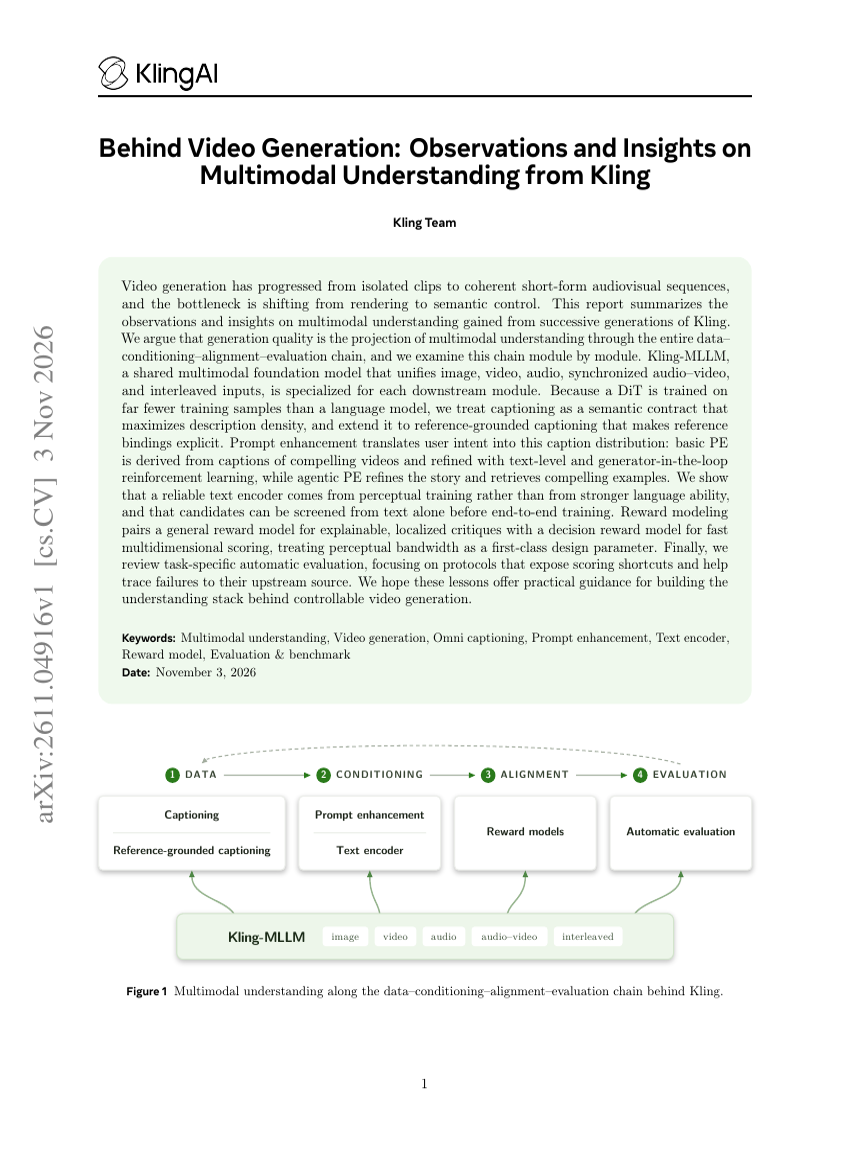
Behind Video Generation: Observations and Insights on Multimodal Understanding from Kling
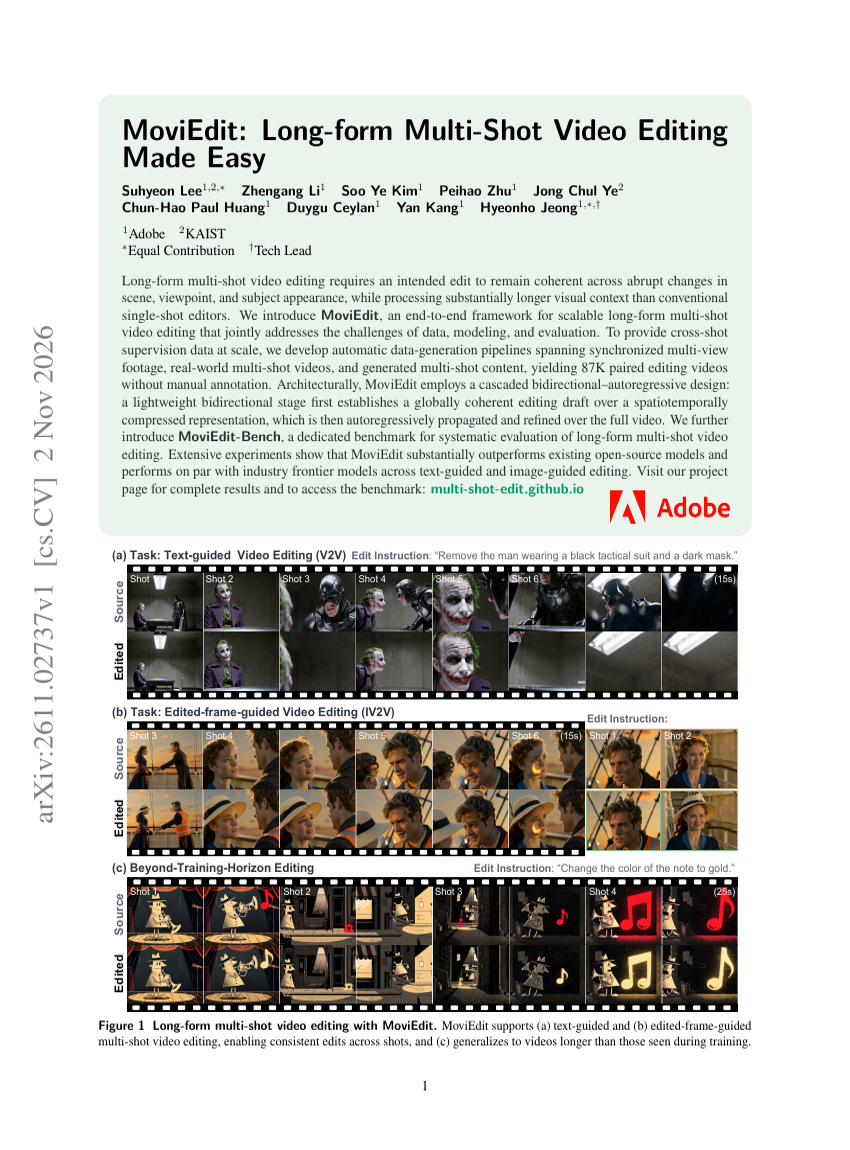
MoviEdit: Long-form Multi-Shot Video Editing Made Easy
Words Caught in the Heart: Simulating Person-Specific Expression for Self-Opaque Clients in Psychotherapy
THINK LESS, LOCALLY: LOCAL PREFERENCE LEARNING FOR REASONING COMPRESSION
Route Anything: A Study of Model and Policy Routing for General-Purpose AI Systems
EmbeddingGemma 2: Unified and Eficient Multimodal Representations
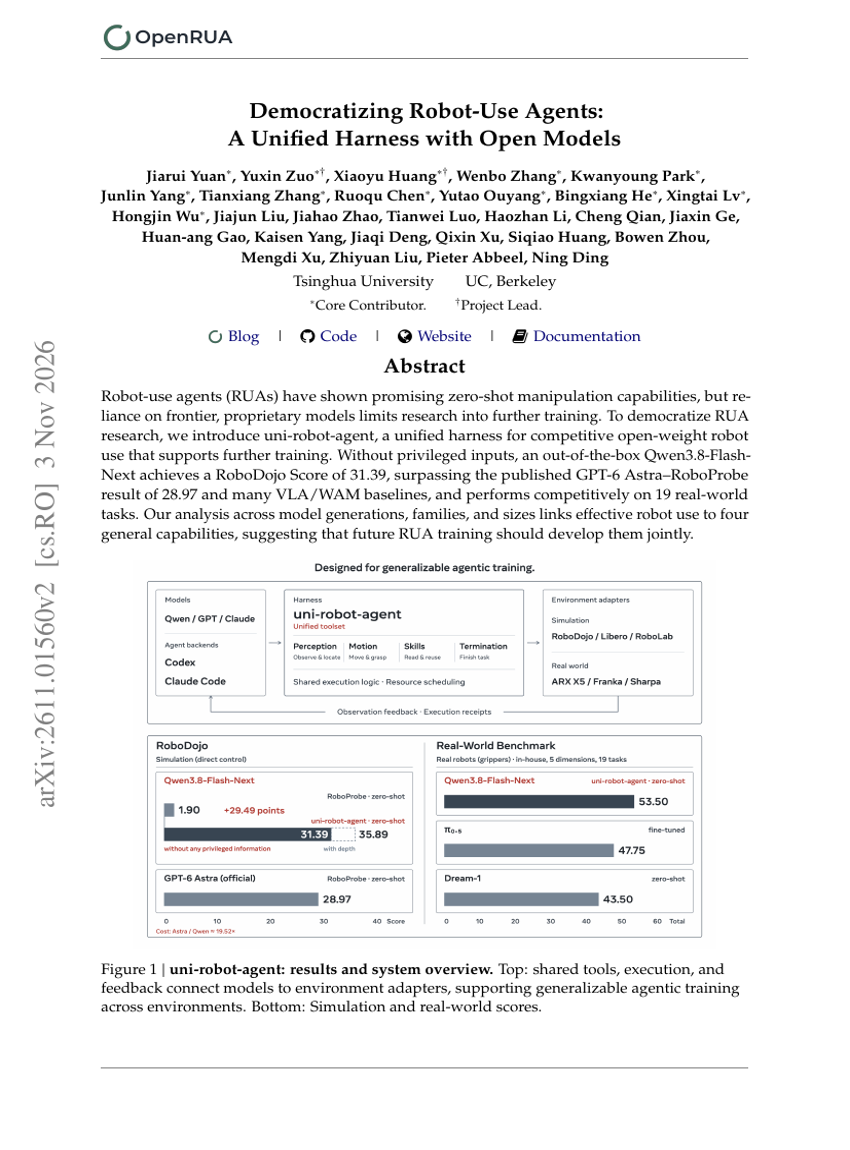
Democratizing Robot-Use Agents: A Unified Harness with Open Models
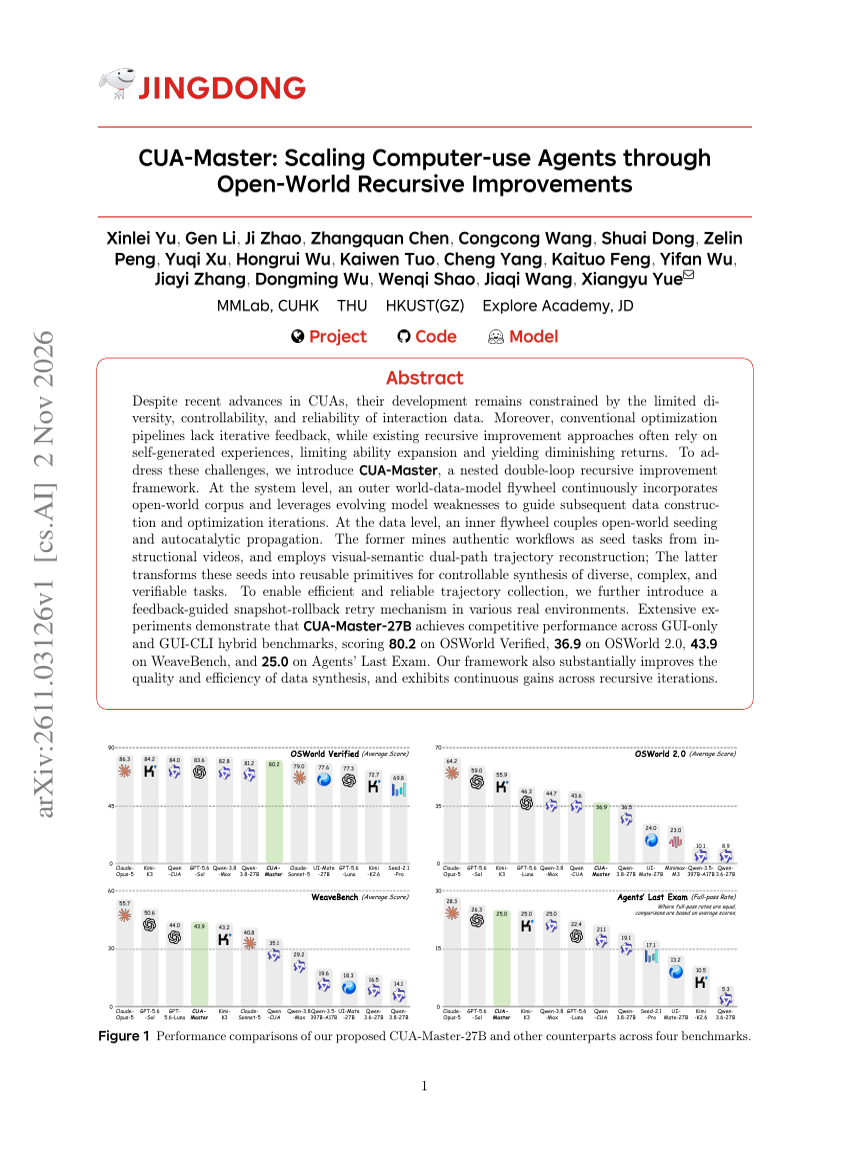
CUA-Master: Scaling Computer-use Agents through Open-World Recursive Improvements
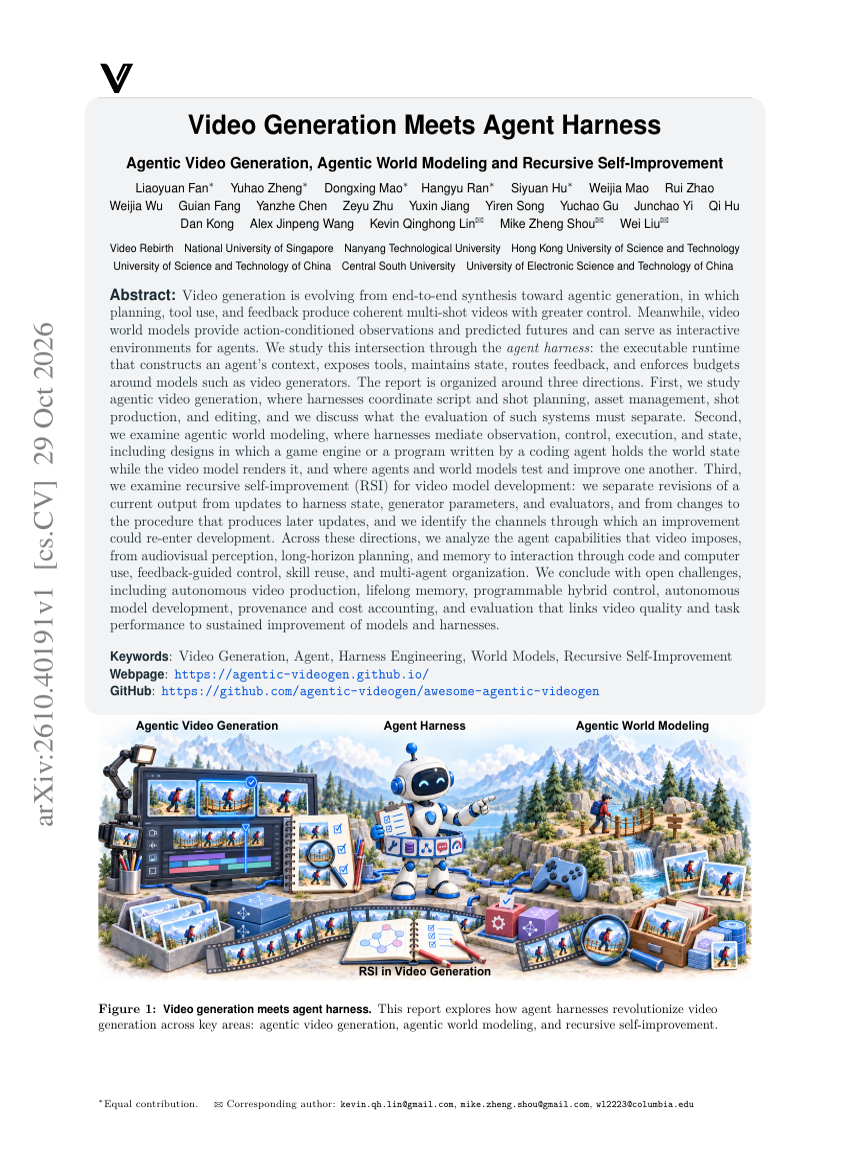
Video Generation Meets Agent Harness: Agentic Video Generation, Agentic World Modeling and Recursive Self-Improvement
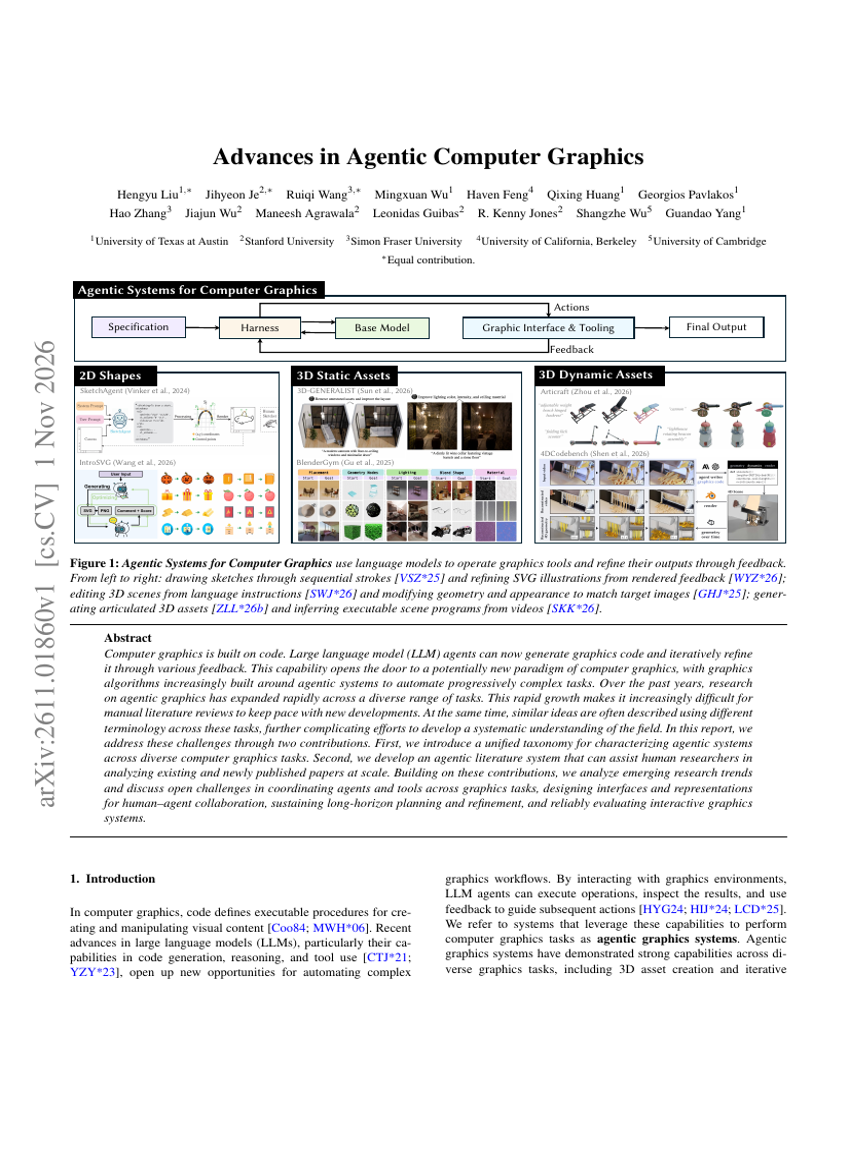
Advances in Agentic Computer Graphics
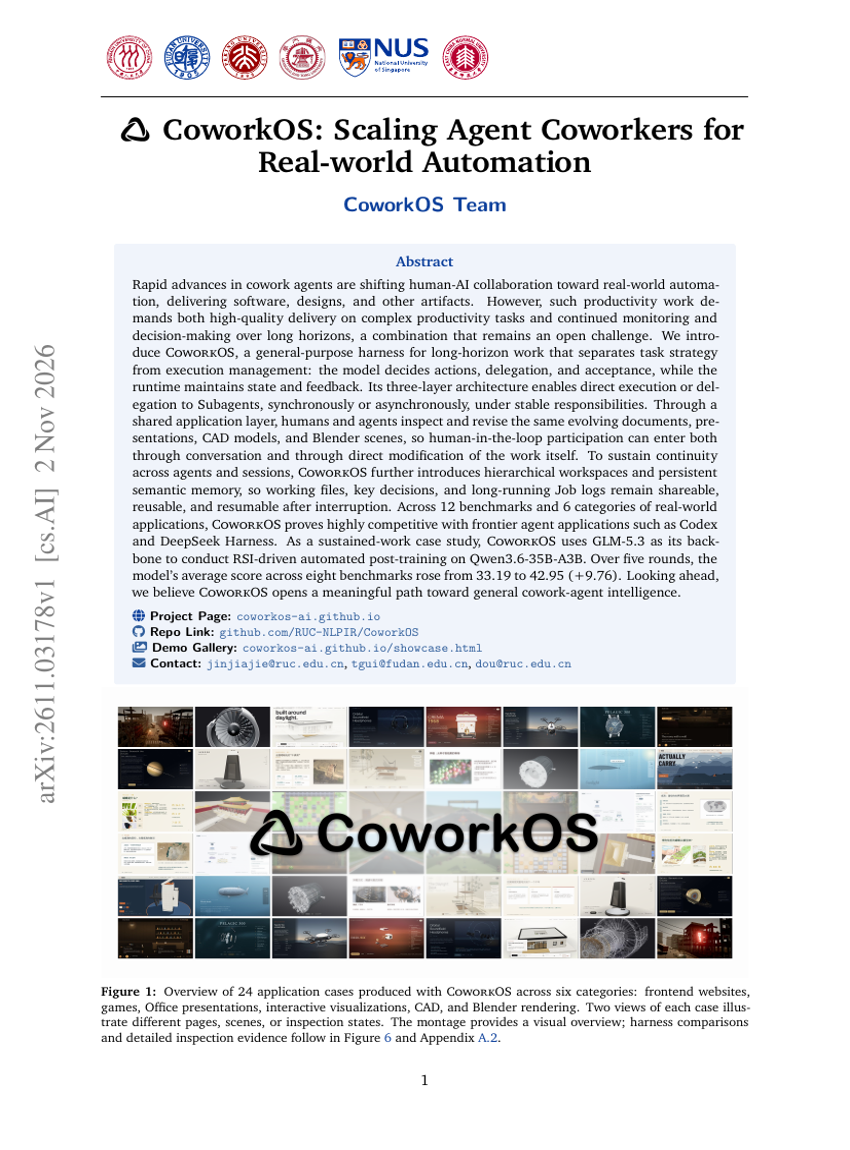
CoworkOS: Scaling Agent Coworkers for Real-world Automation
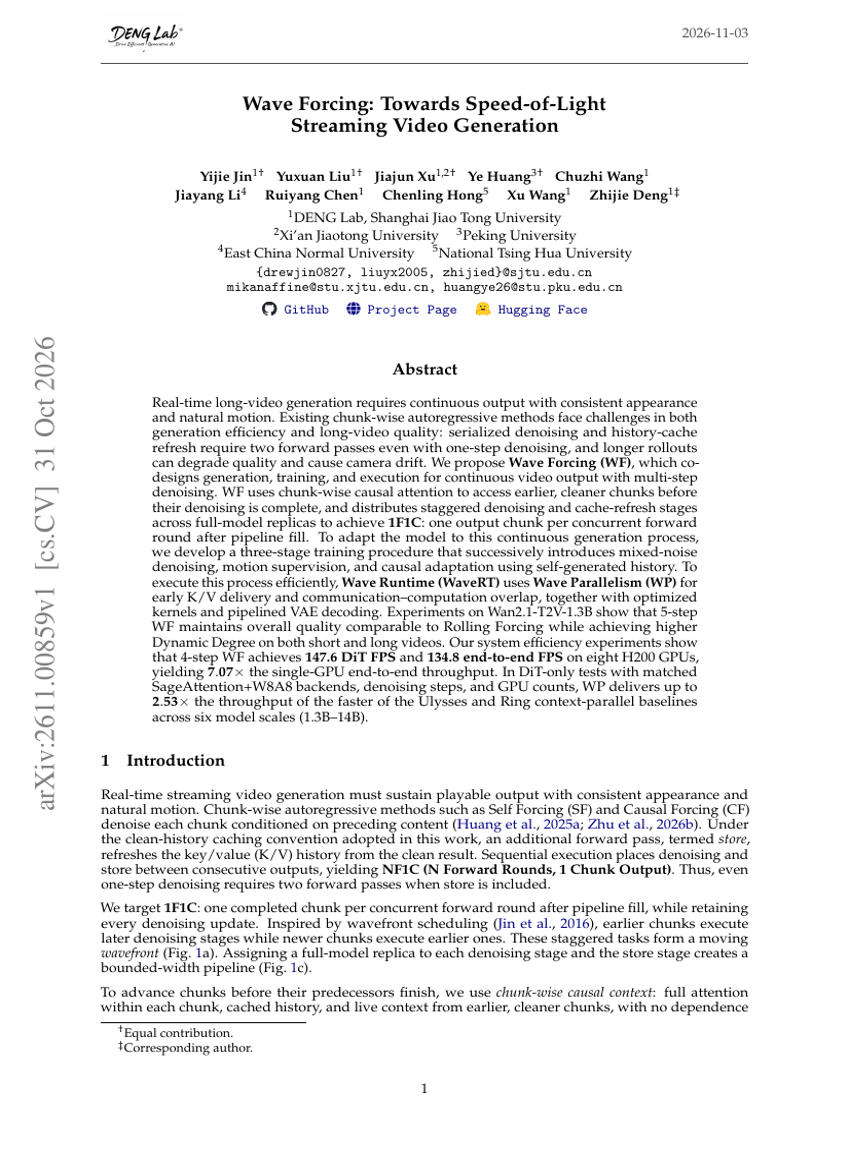
Wave Forcing: Towards Speed-of-Light Streaming Video Generation
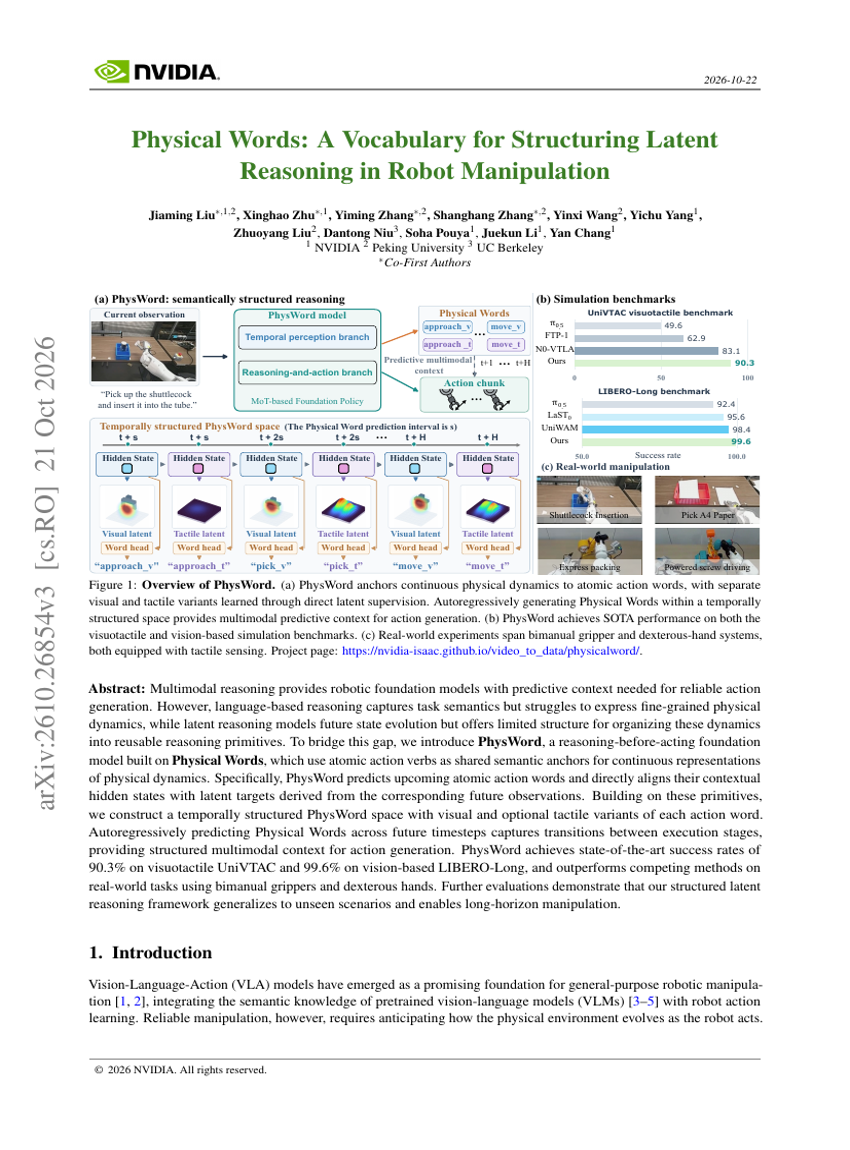
Physical Words: A Vocabulary for Structuring Latent Reasoning in Robot Manipulation
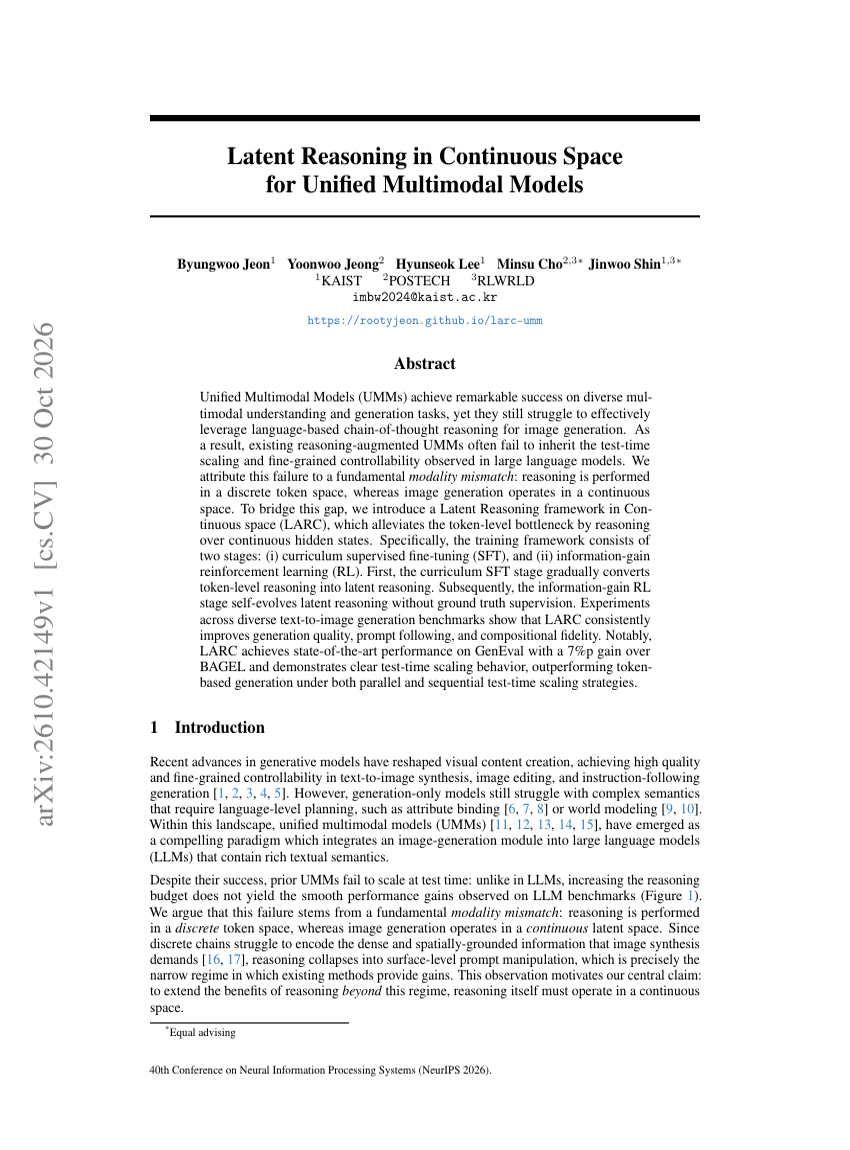
Latent Reasoning in Continuous Space for Unified Multimodal Models
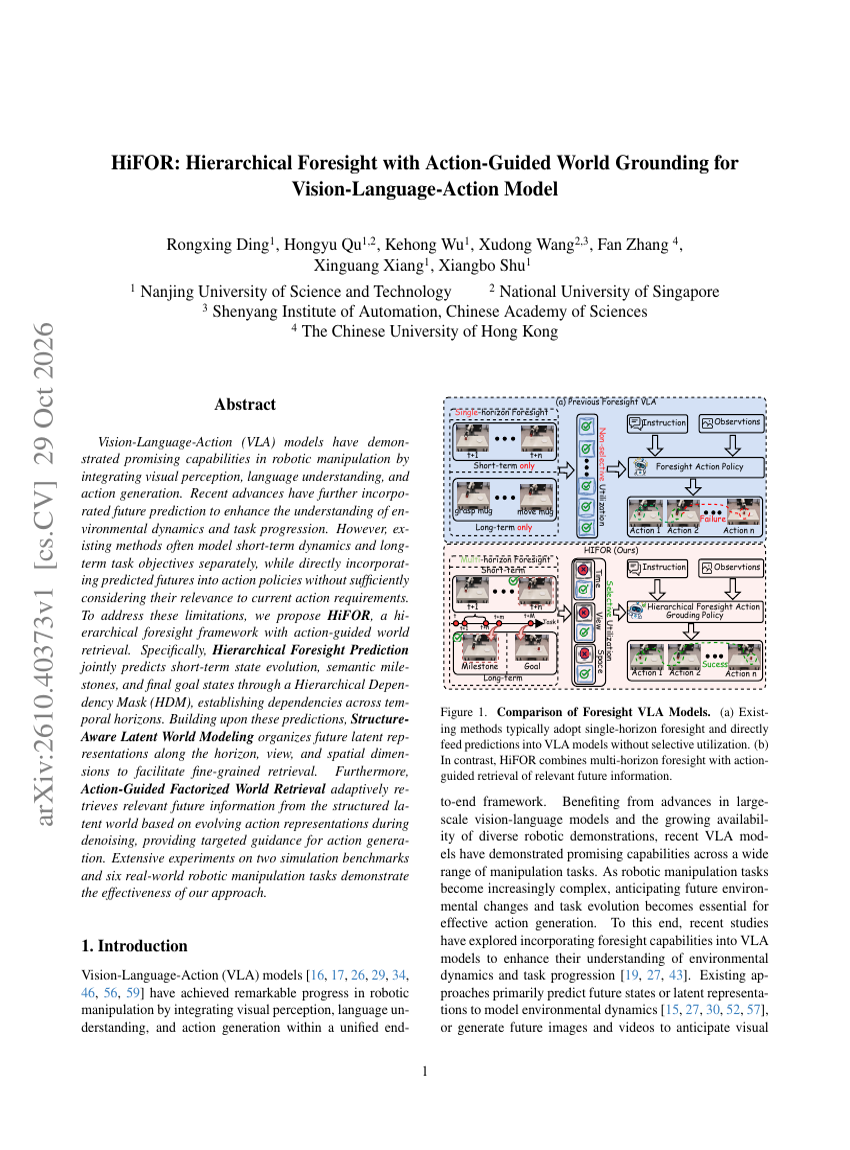
HiFOR: Hierarchical Foresight with Action-Guided World Grounding for Vision-Language-Action Model
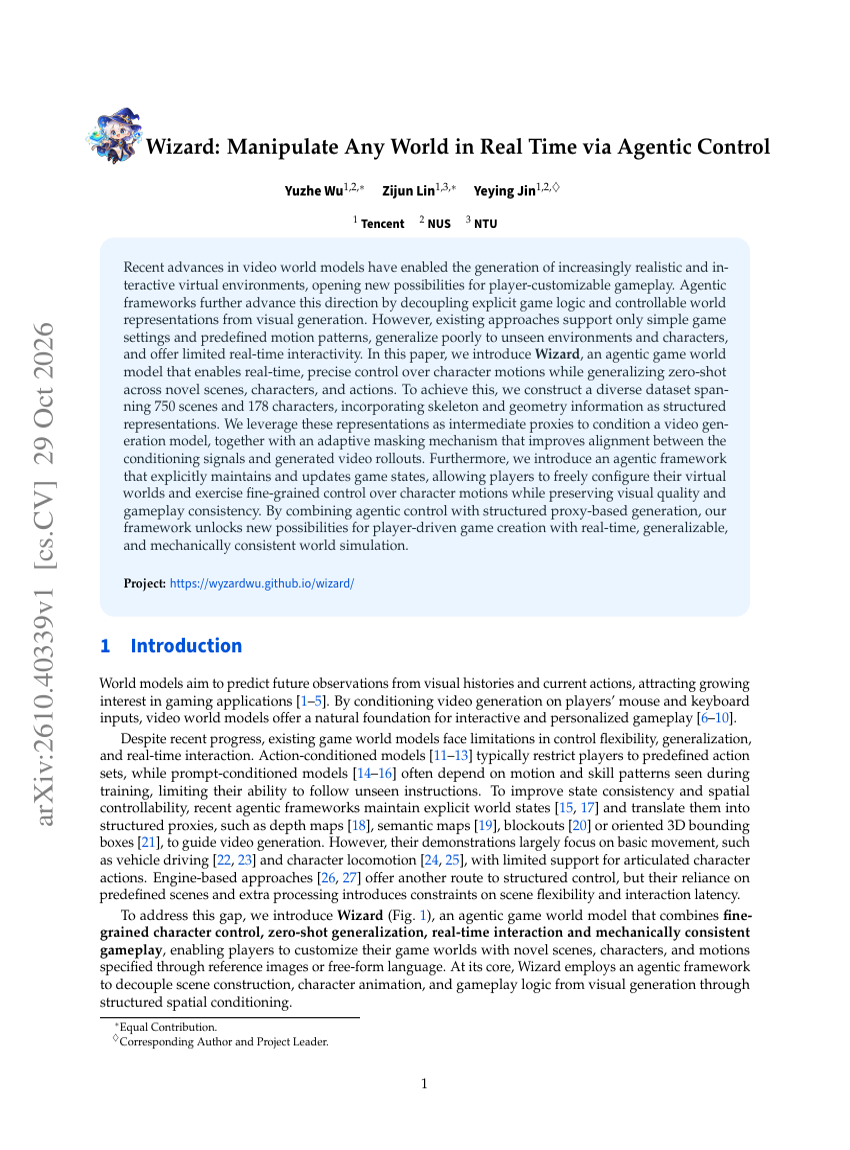
Wizard: An Agentic Game World Model
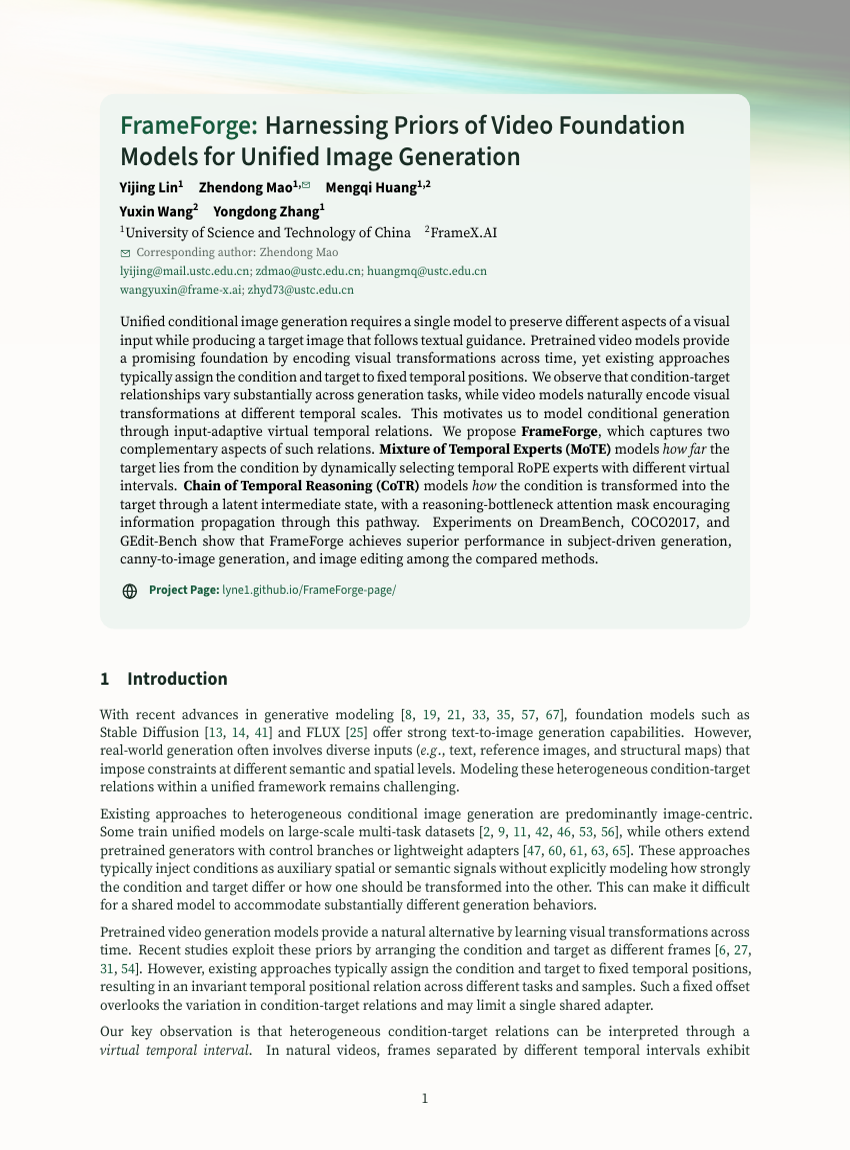
FrameForge: Harnessing Priors of Video Foundation Models for Unified Image Generation
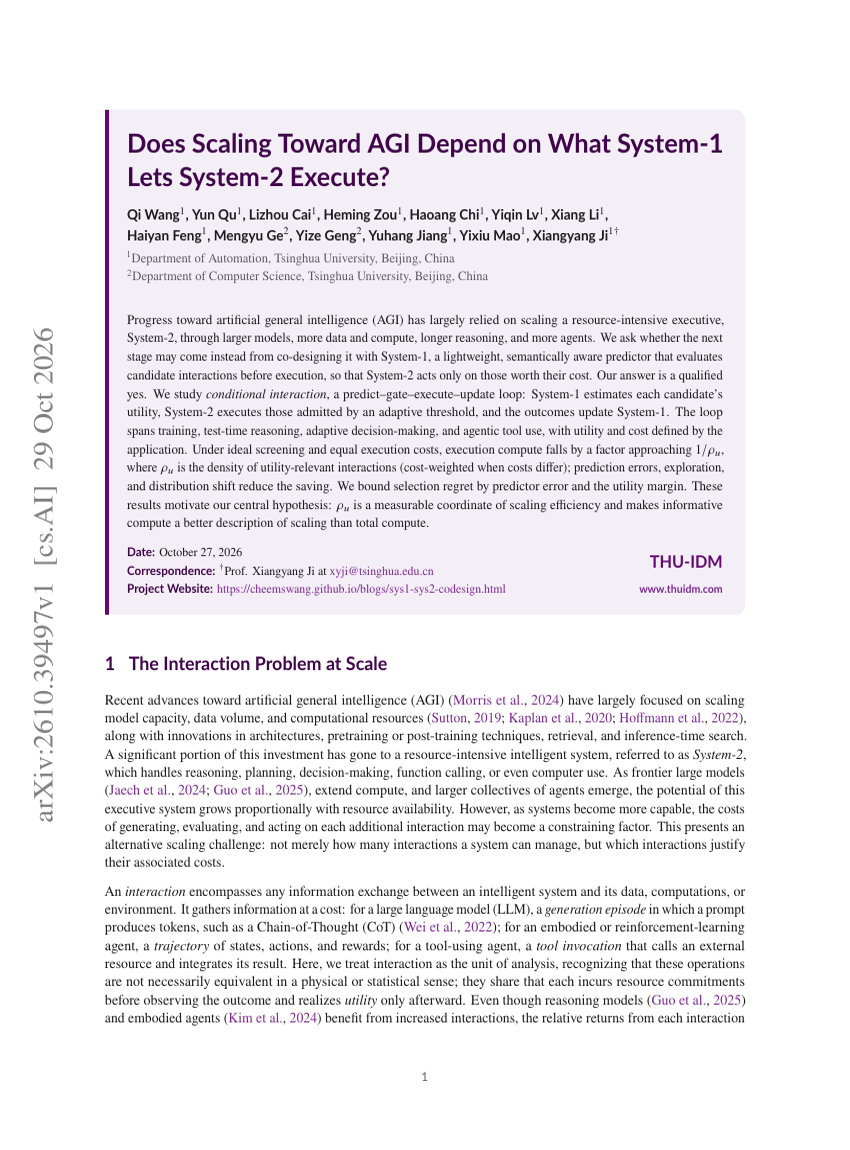
Does Scaling Toward AGI Depend on What System-1 Lets System-2 Execute?
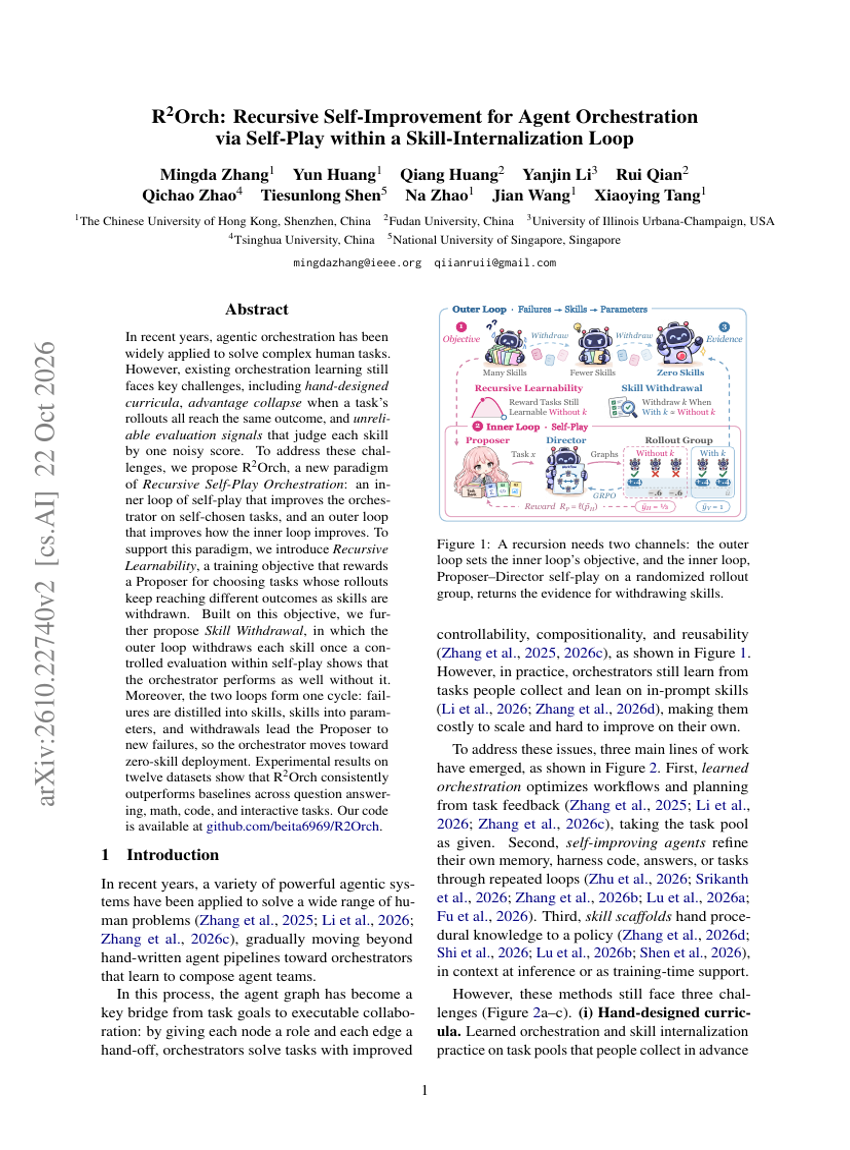
R2Orch: Recursive Self-Improvement for Agent Orchestration via Self-Play within a Skill-Internalization Loop
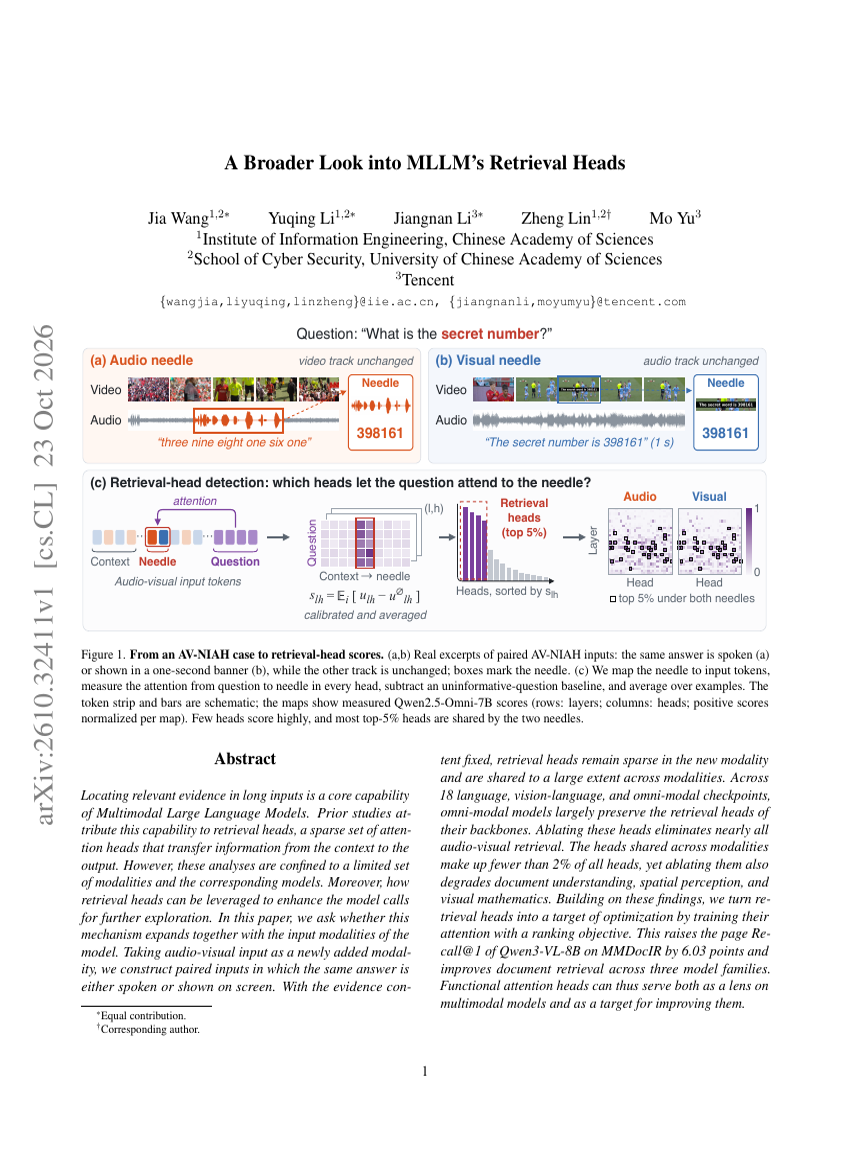
A Broader Look into MLLM’s Retrieval Heads