Command Palette
Search for a command to run...
Latent Reasoning in Continuous Space for Unified Multimodal Models
Latent Reasoning in Continuous Space for Unified Multimodal Models
Byungwoo Jeon Yoonwoo Jeong Hyunseok Lee Minsu Cho Jinwoo Shin
Abstract
Unified Multimodal Models (UMMs) achieve remarkable success on diverse multimodal understanding and generation tasks, yet they still struggle to effectively leverage language-based chain-of-thought reasoning for image generation. As a result, existing reasoning-augmented UMMs often fail to inherit the test-time scaling and fine-grained controllability observed in large language models. We attribute this failure to a fundamental modality mismatch: reasoning is performed in a discrete token space, whereas image generation operates in a continuous space. To bridge this gap, we introduce a Latent Reasoning framework in Continuous space (LARC), which alleviates the token-level bottleneck by reasoning over continuous hidden states. Specifically, the training framework consists of two stages: (i) curriculum supervised fine-tuning (SFT), and (ii) information-gain reinforcement learning (RL). First, the curriculum SFT stage gradually converts token-level reasoning into latent reasoning. Subsequently, the information-gain RL stage self-evolves latent reasoning without ground truth supervision. Experiments across diverse text-to-image generation benchmarks show that LARC consistently improves generation quality, prompt following, and compositional fidelity. Notably, LARC achieves state-of-the-art performance on GenEval with a 7%p gain over BAGEL and demonstrates clear test-time scaling behavior, outperforming tokenbased generation under both parallel and sequential test-time scaling strategies.
One-sentence Summary
Researchers from KAIST, POSTECH, and RLWRLD propose Latent Reasoning in Continuous space (LARC), a two-stage framework that combines curriculum supervised fine-tuning and information-gain reinforcement learning to shift multimodal reasoning from discrete token space to continuous hidden states, improving text-to-image generation quality, prompt following, and compositional fidelity while achieving state-of-the-art GenEval performance with a 7%p gain over BAGEL.
Key Contributions
- LARC is a latent reasoning framework that performs reasoning over continuous hidden states instead of discrete tokens, bridging the modality gap between discrete reasoning tokens and continuous image generation in unified multimodal models.
- The training pipeline combines curriculum supervised fine-tuning, which gradually converts token-level reasoning into latent reasoning, with an information-gain reinforcement learning stage that self-evolves latent reasoning without ground-truth supervision or an external critic.
- Experiments on text-to-image generation benchmarks show that LARC improves generation quality, prompt following, and compositional fidelity, and achieves state-of-the-art performance on GenEval with a 7%p gain over BAGEL. LARC is the first reasoning-augmented UMM to exhibit clear test-time scaling for image generation, outperforming token-based generation under both parallel and sequential test-time scaling strategies.
Introduction
Unified multimodal models (UMMs) combine image generation with large language models to handle language-level planning for complex visual semantics, but they have not inherited the test-time scaling behavior seen in LLMs. The authors attribute this to a modality mismatch: reasoning is performed over discrete tokens, whereas image generation requires dense, spatially grounded continuous latent representations. As a result, added reasoning compute often collapses into shallow prompt manipulation rather than meaningful planning. To address this, they introduce LARC, a framework that performs reasoning directly in a continuous latent space aligned with image generation. LARC uses curriculum supervised fine-tuning to gradually replace token reasoning with stochastic continuous hidden states, followed by reinforcement learning with an information-gain reward and a collapse-prevention reward, requiring no ground-truth reasoning chains or external critics. This enables the first reasoning-augmented UMM with clear test-time scaling for text-to-image generation.
Dataset
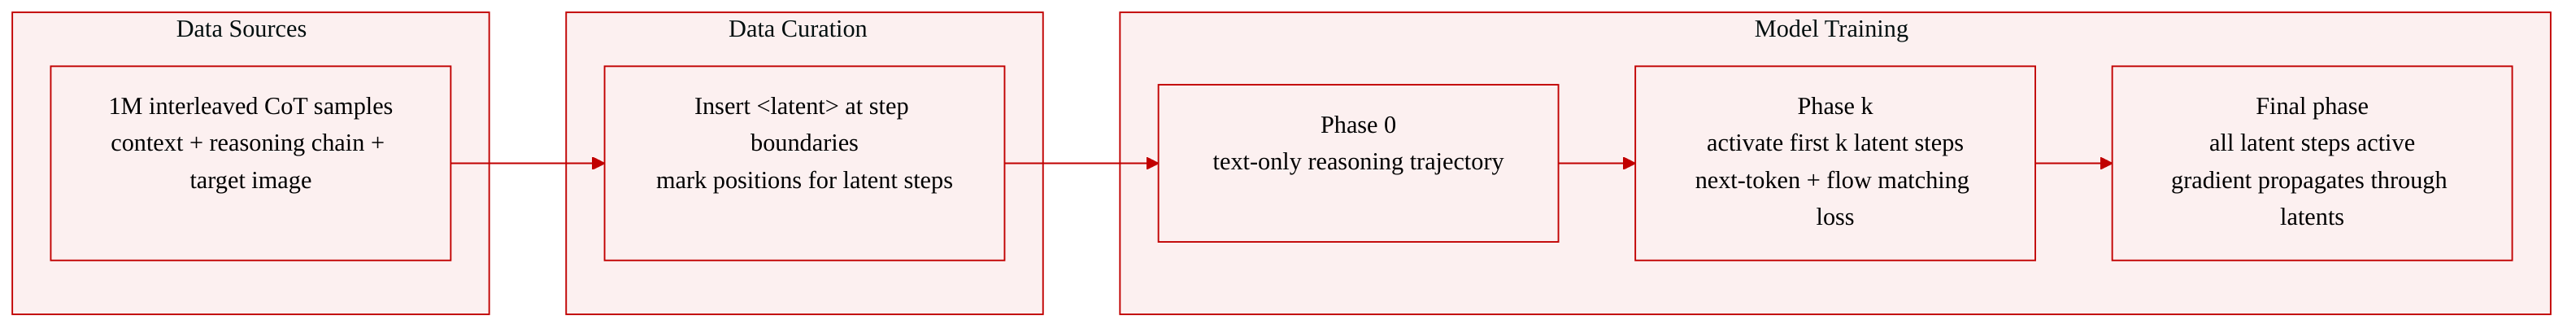
- Dataset composition and sources: The authors collect 1M interleaved chain-of-thought samples. Each sample includes an input context, a step-by-step reasoning chain, and a target image. Further source breakdown, mixture ratios, or train/validation splits are not specified in this excerpt.
- Data format and preprocessing: Each reasoning chain is processed by inserting the special token
<latent>at step boundaries. This marks the positions where latent steps can be introduced and creates an interleaved text and latent trajectory. - Curriculum-based usage: The data is used for supervised fine-tuning with a curriculum. Initially, all latent steps are suppressed, and the model trains on the text-only reasoning trajectory. In later phases, the first k latent steps are progressively activated, with each new latent step built on the already trained prefix. The final phase activates all latent steps.
- Training objective on this data: The model is optimized with a next-token prediction loss over text segments and a flow-matching loss on the target image. Latent steps receive no explicit supervision target; gradients propagate through them so they can learn useful representations automatically.
- Other processing: No cropping strategy or additional metadata construction is described in this portion of the paper.
Method
The authors propose LARC, a framework that enables unified multimodal models (UMMs) to perform image generation through latent reasoning in continuous space. The method is built around a two-stage training pipeline. Stage 1 uses curriculum supervised fine-tuning to convert token-level reasoning into interleaved latent reasoning, while Stage 2 uses self-evolving reinforcement learning with an information-gain reward to refine the latent reasoning trace without external critics.
Interleaved Latent Reasoning
To make continuous-space reasoning compatible with policy-gradient optimization, LARC formulates a reasoning trajectory as an alternating sequence of text segments and continuous latent steps, both generated by the UMM backbone. Given an input context c=(c1,…,cT) consisting of a text prompt and optionally a source image, the model produces a reasoning trajectory followed by a target image x.
The trajectory alternates between two modes. In language mode, the model emits text tokens through stochastic sampling, which exposes the trajectory to gradient signals during policy optimization. In latent mode, the model emits a continuous reasoning step that bypasses text decoding, preserving the semantic information of internal representations.
Formally, the UMM backbone first processes the input embedding ET=[e(c1),…,e(cT)] to produce hidden states HT=Transformer(ET). When the model produces the special token <latent> at position t, latent mode begins, and the embedding for the next position is set to ht, the hidden state at position t in the final transformer layer. The next-position embedding update is defined as
with
Ht+1=Transformer(Et+1).At inference, mode alternation continues until the model emits the <eos> token. Each <latent> token marks the transition from a language-mode span to the next latent step. After termination, the hidden states of the full trajectory, denoted h(τ), are read by the image module through cross-attention to produce the target image x. The resulting trajectory takes the form
where sn denotes the n-th language-mode span and ln denotes the n-th latent-mode hidden state. The trajectory length and the span lengths are determined by when the model emits <eos> and <latent> tokens rather than by an external schedule.
Stage 1: Supervised Fine-Tuning with Curriculum Learning
Introducing all latent steps from the beginning of training tends to be unstable because the latent stream lacks direct supervision while the model has not yet learned the basic reasoning format. To address this, LARC uses a curriculum that gradually converts token-level reasoning into latent reasoning.
For data construction, the authors collect 1M interleaved chain-of-thought samples, each containing an input context c, a step-by-step reasoning chain, and a target image x. The special token <latent> is inserted at reasoning step boundaries to mark the positions where latent steps are introduced.
The curriculum starts with a text-only trajectory
τ(0)=(s1,…,sN),which establishes the reasoning format under standard next-token prediction. In phase k for k=1,…,N−1, only the first k latent steps are activated, so each newly introduced latent step is built on top of a stable prefix. The final phase activates all latent steps, and the learning rate is reduced at each phase transition.
The SFT objective combines a next-token prediction loss over text segments with a flow-matching loss on the target image:
LSFT(k)=−n=1∑Nlogπθ(sn∣c,s<n,l<min(n,k+1))+Lflow(x∣c,s1:N,l1:k).Here, s<n and l<min(n,k+1) denote the text segments and active latent steps preceding sn at phase k. Gradients are propagated through the latent steps without explicit supervision targets, allowing the latent representations to encode useful information without external bias.
Stage 2: Self-Evolving Reinforcement Learning
Supervised fine-tuning alone is limited in refining latent reasoning because latent annotations are not directly available. LARC therefore introduces a self-evolving reinforcement learning stage with an intrinsic reward derived from the UMM itself, avoiding any external critic.
The reward is defined as the information gain that a reasoning trace provides to a frozen reference model. Letting πref denote the Stage 1 model and pπref(x∣⋅) denote the image-module density, the information-gain reward for a sampled trajectory τ is
rIG(τ;x,c)≜logpπref(x∣c,h(τ))−logpπref(x∣c).This reward is positive when the trajectory raises the likelihood of the target image under the reference model and is zero when the trajectory carries no additional information beyond the context. In expectation, it corresponds to the conditional mutual information between the latent reasoning trace and the target image given the context.
Because the image module does not provide direct access to log-likelihoods, the reward is estimated as a paired difference of conditional flow-matching losses under shared noise:
rIG(τ;x,c)≈Lflowπref(x,c)−Lflowπref(x,c,h(τ)).To prevent latent collapse, LARC adds an inter-step diversity regularizer that encourages distinct latent steps:
rdiv(τ)=N(N−1)1n=n′∑(1−cos(ln,ln′)),where cos(⋅,⋅) denotes cosine similarity between latent-mode hidden states. The total reward is therefore
R(τ;x,c)=rIG(τ;x,c)+λdiv⋅rdiv(τ).The policy is optimized by maximizing the expected reward over sampled trajectories:
πθmaxE(c,x)∼D[Eτ∼πθ(⋅∣c)[R(τ;x,c)]].The authors adopt GRPO as the optimization algorithm, which estimates advantages from group rollouts and removes the need for an explicit value model. This allows the same optimization setup to transfer across benchmarks while keeping training stable.
Experiment
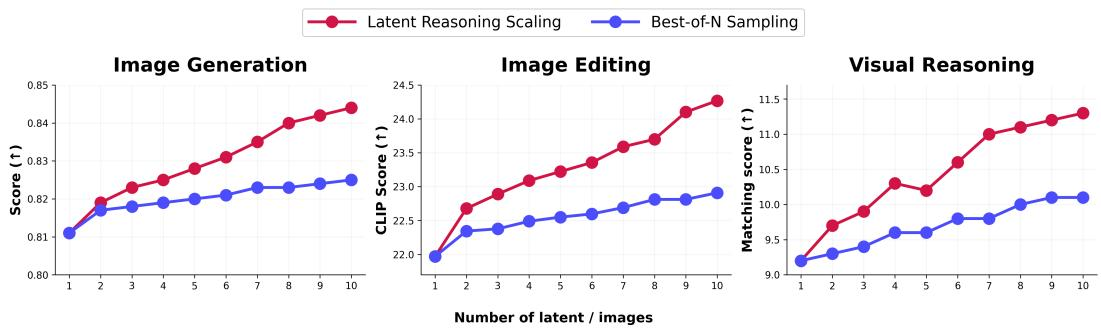
The evaluation examines LARC on text-to-image generation, image editing, and multimodal understanding tasks using benchmarks such as GenEval, DPG-Bench, OneIG-Bench, CompBench, MME, MMB, and MIRA, with comparisons against both unified multimodal models and dedicated generation models. LARC consistently improves generation quality, prompt following, editing fidelity, and visual reasoning, with the largest benefits appearing in compositionally demanding and multi-step reasoning scenarios. Test-time scaling shows that increasing the latent reasoning budget monotonically improves performance across tasks and outperforms best-of-N sampling, while ablations confirm that latent reasoning, interleaved text segments, and the two-stage training with self-evolving reinforcement learning all contribute to the overall gains.
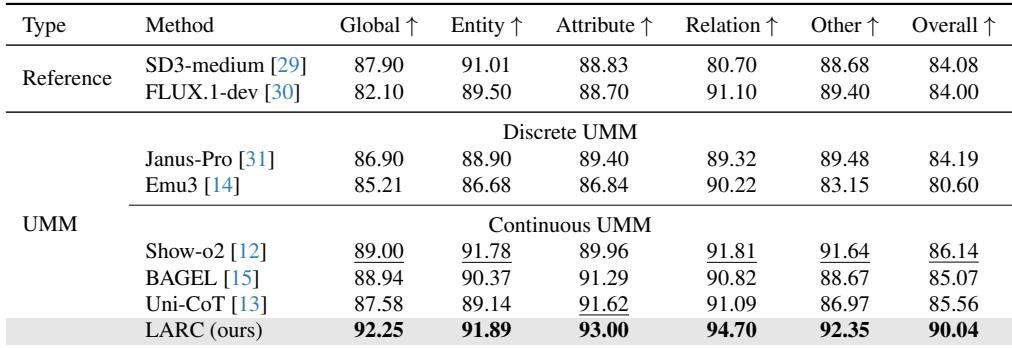
LARC achieves strong text-to-image generation performance on GenEval, outperforming or matching reference models and discrete unified multimodal models across most subcategories. The largest gain over the baseline appears in attribute binding, indicating improved compositional handling of object properties. Overall results point to broad gains in prompt-following generation. LARC outperforms or consistently matches competing baselines across GenEval subcategories and overall score. Attribute binding shows the most pronounced improvement over the baseline, with a 15 percentage point gain. The benefit is strongest for compositionally demanding generation, while other subcategories remain competitive.
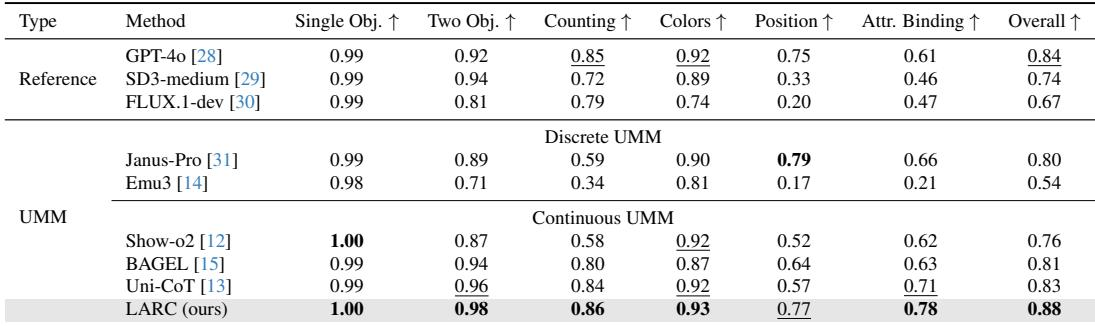
On DPG-Bench, LARC improves prompt-following fidelity relative to its base model BAGEL, with the overall score rising from 85.07 to 90.04. The reported gains are consistent across global, entity, attribute, relation, and other categories, indicating broad generalization across prompt types. Among the listed baselines, the continuous unified multimodal model Show-o2 records the highest overall score, ahead of the discrete unified multimodal baselines. LARC reaches an overall DPG-Bench score of 90.04, a 5.8% relative improvement over the base model BAGEL at 85.07. Across every subcategory, LARC shows consistent improvements over competing baselines, including global, entity, attribute, relation, and other prompt types. Among the provided baseline rows, continuous UMM Show-o2 achieves the highest overall score at 86.14, outperforming discrete UMMs such as Janus-Pro and Emu3.
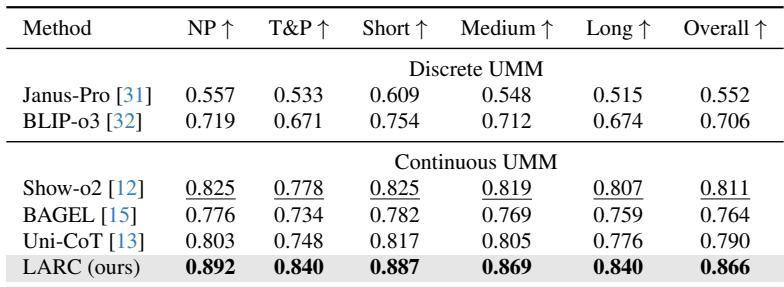
On OneIG-Bench, continuous unified multimodal models outperform discrete models, and natural language prompts consistently score higher than tag-based and phrase-based prompts. Scores generally decline as prompt length increases from short to medium to long, though the drop is modest for the strongest continuous models. LARC achieves a 10.2 percentage point overall gain over the BAGEL baseline with consistent improvements across prompt types and lengths. Continuous unified multimodal models score higher than discrete models across natural language and tag/phrase prompt categories. LARC improves the overall OneIG-Bench score by 10.2 percentage points over BAGEL, with reported gains across prompt types and lengths.
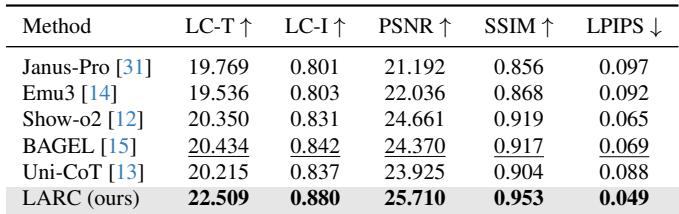
LARC achieves the strongest image editing results on CompBench, outperforming all listed baselines across text alignment, image similarity, pixel quality, and perceptual similarity. The improvement over BAGEL is especially large for instruction adherence and perceptual quality, while competing unified multimodal models generally trail behind. LARC records the best LC-T, LC-I, PSNR, SSIM, and LPIPS among all compared methods. Compared with BAGEL, LARC shows a clear gain in editing instruction adherence and markedly lower perceptual error.
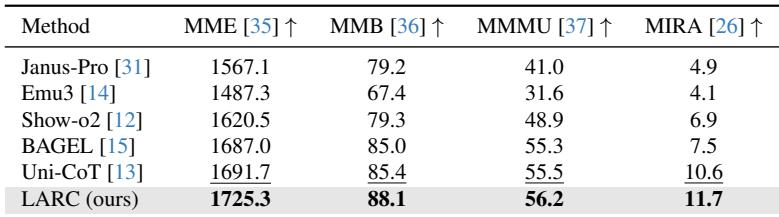
LARC achieves the highest reported scores among the compared methods on MME, MMB, MMMU, and MIRA. It improves over both BAGEL and Uni-CoT across all four benchmarks, with the most pronounced gain on MIRA visual reasoning. Gains on MME and MMB indicate stronger multimodal understanding transfers to perception-heavy tasks without sacrificing general visual understanding. LARC outperforms BAGEL and Uni-CoT on MME, MMB, MMMU, and MIRA. The largest improvement appears on MIRA, where LARC exceeds BAGEL and the discrete reasoning model Uni-CoT.
The evaluation covers text-to-image generation on GenEval and DPG-Bench, prompt adherence and length generalization on OneIG-Bench, image editing on CompBench, and multimodal understanding on MME, MMB, MMMU, and MIRA. LARC consistently improves over its BAGEL baseline, with notable gains in attribute binding, instruction adherence, and visual reasoning, while matching or surpassing competing discrete and continuous unified multimodal models. The results indicate that LARC's improvements generalize across generation, editing, and perception tasks without sacrificing general visual understanding.