Command Palette
Search for a command to run...
Jeva: System One Models from First Principles
Jeva: System One Models from First Principles
Qi Li Xinchao Wang
Abstract
System one models enable direct, low-latency decision-making. Yet recent practice of predicting an answer from serialized text does not, by itself, respect the structure of a decision problem. We argue tha current designs underemphasize four important structural requirements. (i) null-aware: Models should distinguish answer absence from uncertainty among candidates; (ii) permutation-invariant: Reordering alternatives should not change the decision; (iii) option-scalable: Growing candidate sets should not require redefining the output space; (iv) cacheable: Request-independent computation over recurring alternatives should be reusable across requests. We introduce Jeva, a decision-native architecture that addresses these requirements jointly. A shared encoder independently represents the request and each option, while a compact decision stack refines only the request state against immutable option memory. Symmetric aggregation yields permutation-equivariant probabilities; shared scoring accommodates variablesize candidate sets. A separate coverage estimate distinguishes answer absence from candidate competition, enabling explicit null outcomes. Request-independent option representations and layer projections support reuse across newly assembled sets. These mechanisms unify Choice, Noul, and Score outputs. Across evaluations, Jeva combines strong typed-decision performance with near-perfect null detection and no decision flips under any tested permutations. It scales to thousands of candidates and substantially reduces latency through cross-request reuse without changing decisions.
One-sentence Summary
Researchers at the National University of Singapore introduce Jeva, a decision-native architecture that jointly enforces null-awareness, permutation invariance, option scalability, and cacheability through a shared encoder, immutable option memory, symmetric aggregation, and coverage estimation, thereby achieving strong typed-decision performance, near-perfect null detection, no permutation-induced decision flips, and reduced latency via cross-request reuse.
Key Contributions
- Jeva is a decision-native architecture that jointly addresses null awareness, permutation invariance, option scalability, and cacheability by independently encoding the request and each option, refining a request state against immutable option memory, and applying symmetric aggregation and shared scoring.
- The architecture unifies Choice, Noul, and Score outputs, with a separate coverage estimate distinguishing answer absence from candidate competition to enable explicit null outcomes.
- With a Qwen3.5-4B backbone and one decision block, Jeva achieves strong typed-decision performance, near-perfect null detection, and no decision flips under tested permutations; it scales to 2,048 candidates and provides more than 2x median latency speedup for full-set scoring and more than 20x for cross-request reuse without changing decisions.
Introduction
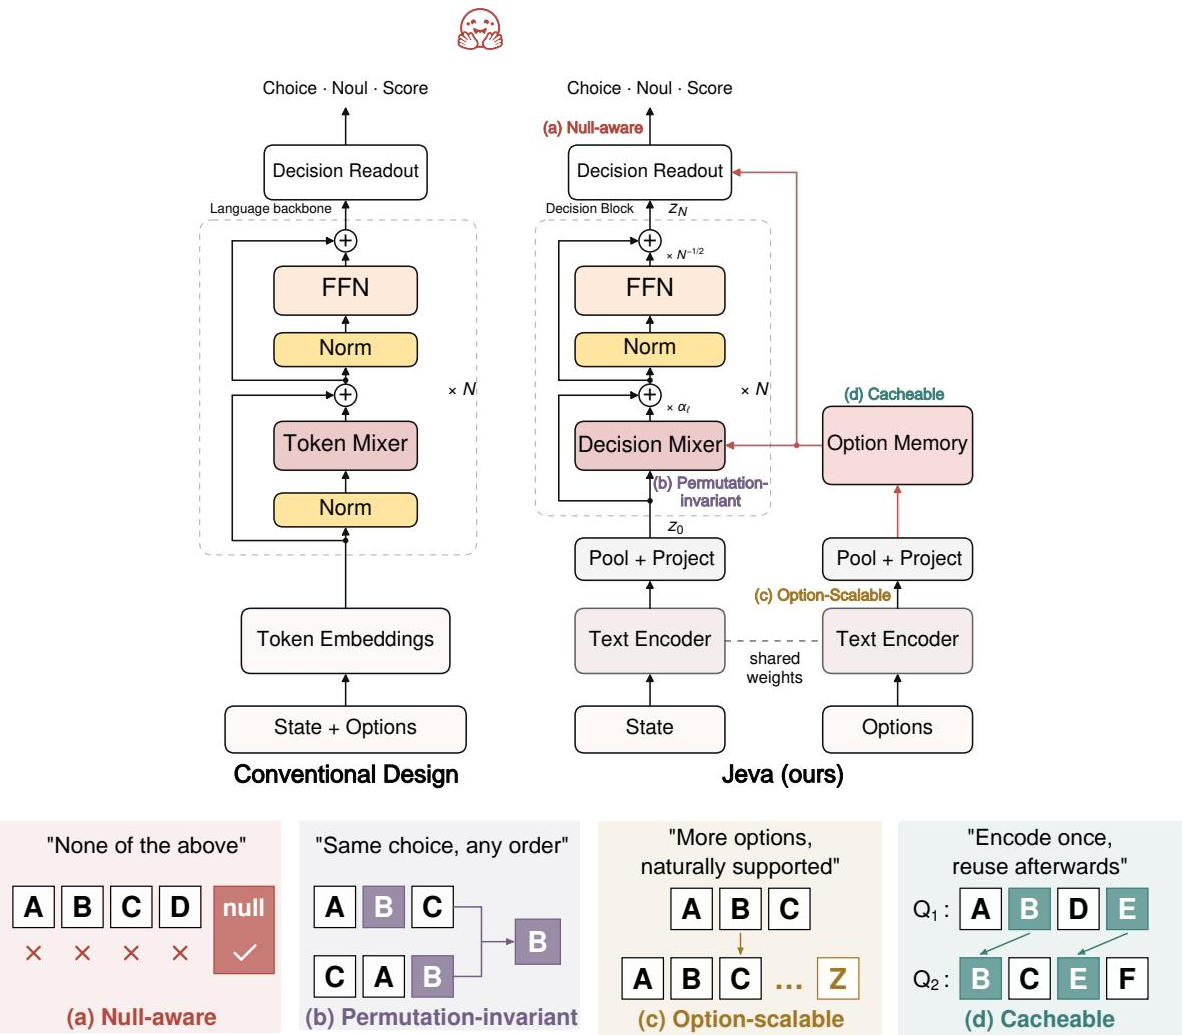
Many language-model requests require compact typed decisions such as choosing a tool, identifying a document, or assigning a score. These decisions need candidate order symmetry, support for variable candidate counts, explicit null awareness, and reusable candidate representations to reduce latency. Prior open-source system one models commonly encode requests and candidates jointly as text, which couples candidate representation to request-specific computation, makes predictions sensitive to candidate order, restricts candidate counts through fixed output spaces, and does not clearly separate answer absence from uncertainty among alternatives. The authors introduce Jeva, a decision-native architecture that independently encodes the request and each option with a shared language encoder, then refines only the request state by reading an immutable option memory. Symmetric aggregation, shared candidate scoring, and a separate coverage gate provide permutation-equivariant probabilities, variable-size candidate support, explicit null detection, and reusable option computation.
Method
Independent Encoding and Collective Decisions
The authors leverage a shared language backbone to independently encode the request and each option, separating reusable semantic encoding from set-dependent judgment. A compact decision module refines only the request state against immutable option memory, enabling computation reuse while retaining set-dependent scoring.
As shown in the figure below:
A request comprises state x, question ι, decision type t, and candidates O=(o1,...,oK). Inputs are formatted with two text templates: Tx(t,ι,x) combines the decision type, question, and state, while To(t,oi) contains only the decision type and candidate text. Let Eθ be the language backbone followed by last-non-padding-token pooling. Bias-free projections yield:
z0=PxEθ(Tx(t,ι,x)),ui=nrm(PoEθ(To(t,oi))),where nrm is stabilized ℓ2 normalization and z0,ui∈Rd. The rows of U=[u1⊤;…;uK⊤] stay fixed within a forward pass. Jeva conditions the scoring state on the candidate set, enabling preference reversals through compact per-request computation while keeping option representations reusable.
Candidate-Conditioned State Refinement
Each of L blocks reads U through H heads. For head h, queries are derived from the state, while keys and values are derived from the options. The candidate-weighted message is computed via attention:
aℓih=∑jexp((qℓh)⊤kℓjh/τℓ)exp((qℓh)⊤kℓih/τℓ),mℓ=WℓOConcath=1H(∑iaℓihvℓih).These weights yield an entropy-regularized allocation of candidate evidence for state refinement. The state undergoes two residual updates:
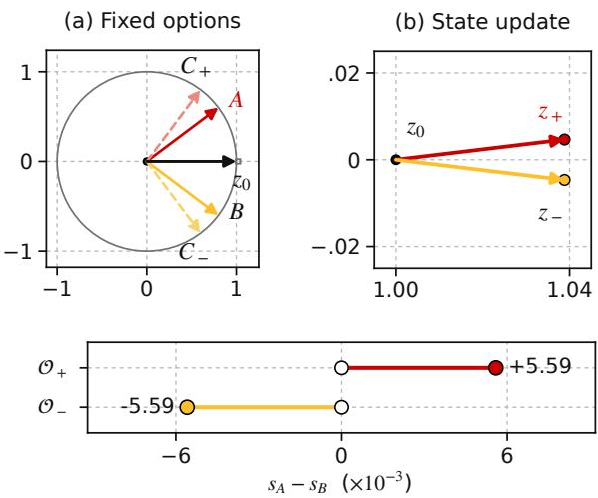
zℓ=zℓ+αℓmℓ,zℓ+1=zℓ+L−1/2Fℓ(RMSNorm(zℓ)),where Fℓ is a bias-free SwiGLU network and αℓ=τℓσ(γℓ)/L. Only zℓ evolves; keys and values depend solely on the unchanged options. This design allows a single block to uniquely select different options from the same set depending on the surrounding candidates, a property impossible for independent scorers.
Refer to the figure below:
Competition, Coverage, and Typed Outputs
Jeva computes final scores si=zL⊤ui and conditional candidate probabilities q=softmax(s/τdec). To form a full distribution p over candidates and null (⊥), the model separately estimates the probability ρ that at least one acceptable candidate is present:
ρ=σ(τcovmaxisi−bcov),p⊥=1−ρ,pi=ρqi.Here, bcov is a learned coverage threshold and τcov>0 is a learned temperature. This implements P(Y=i)=P(Y=⊥)P(Y=i∣Y=⊥). Adding options below the existing maximum leaves ρ unchanged, distinguishing coverage estimation from candidate-score normalization.
Symmetry, Reuse, and Scaling
An atomic option memory stores both its semantic vector and projected views:
Mt(oi)=(ui,{kℓih,vℓih}ℓ,h).Requests gather these entries in their current candidate order. The set cache stores assembled candidate tuples, while the hybrid cache additionally reuses individual options across newly assembled sets. State encoding and decision refinement still execute for every request.
As shown in the figure below:
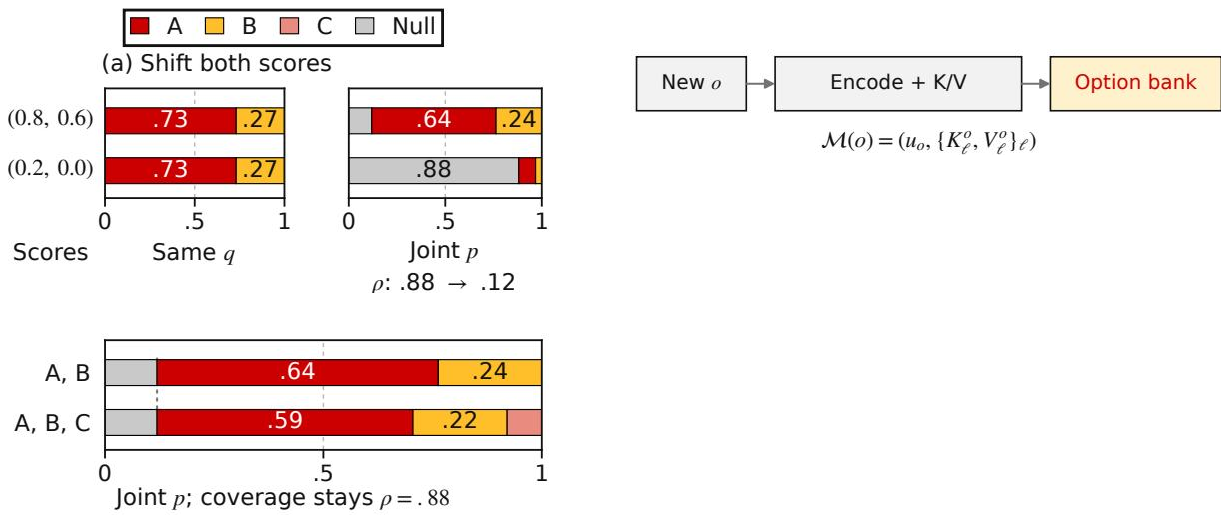
Permuting candidates permutes candidate probabilities but leaves zL, null probability, and typed outputs unchanged. Replacing option computations by identical cached entries also leaves all outputs unchanged. The decision cost is linear in K, and a bank of M options stores O(M(L+1)d) values.
Direct Supervised Learning
For normalized open-set targets (y⊥,y1,…,yK), let cy=∑iyi and g=logit(ρ). The authors minimize:
ℓ=BCEWithLogits(g,cy)−i∑yilogqi.This primary loss is joint cross-entropy on p: all-null examples supervise availability without imposing a spurious candidate ranking. The model uses a Qwen3.5-4B backbone with pooled width 2560, decision width d=768, L=1, H=8, and f=3072. Training employs rank-64 LoRA with both projections and the decision head, using a curriculum spanning typed decisions, intent selection, verification, reading and reasoning, and large-candidate retrieval. LoRA is merged for serving, and memories are prepared for the resulting fixed model.
Experiment
The experiments assess decision accuracy, null detection, candidate scalability, batching efficiency, and cache reuse across Typed Decisions, BANKING77, MASSIVE, and Mind2Web slices. Jeva demonstrates strong full-coverage decision quality, near-perfect order invariance, and effective detection of unsupported requests. It also scales to very large candidate sets with one-pass scoring and length-aware batching, while exact-set and hybrid caching preserve decisions and substantially reduce latency. Overall, the results validate Jeva’s robustness, coverage, and efficiency advantages over baselines.
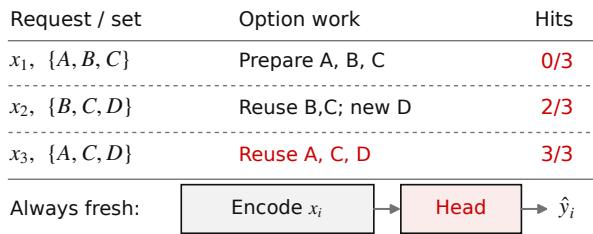
With a fixed model, type, and encoding policy, an initially empty option bank starts with no reusable candidate work, then reuses prepared options as new requests overlap with prior sets. Whole-set lookups consistently miss, while per-option reuse grows across overlapping sets and state encoding plus decisions remain fresh. Reuse rises from no hits on the first set to partial hits on a partially overlapping set and full hits on a fully covered set. Only previously prepared options are reused; new options are prepared on demand without eviction. Whole-set cache lookups miss for every new request set, while state encoding and decision outputs remain fresh.
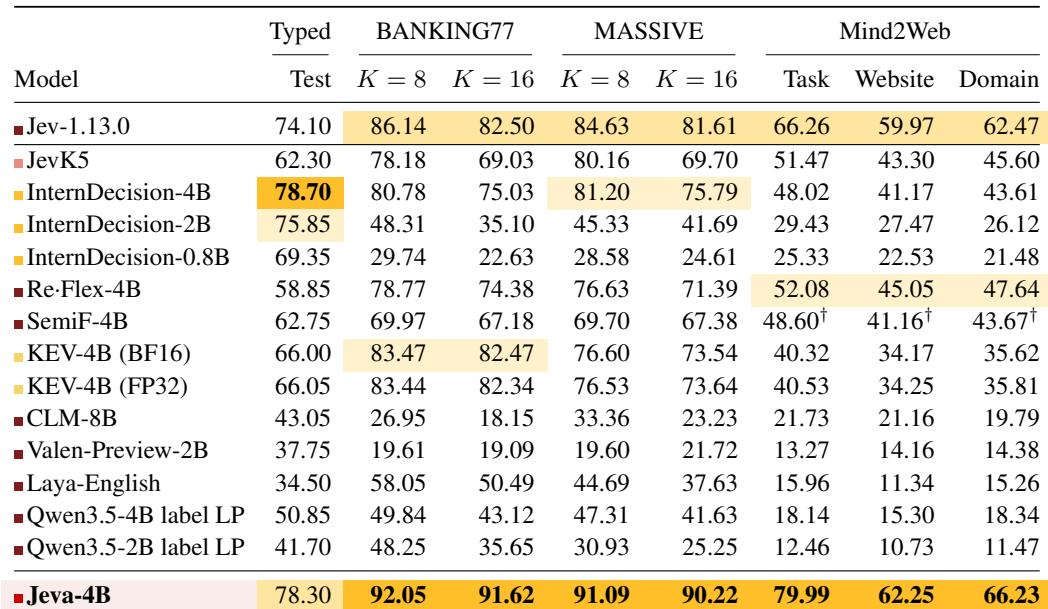
Jeva records the highest first-argmax accuracy on seven of eight full-coverage decision slices, leading BANKING77 and MASSIVE at both candidate counts and all Mind2Web splits. The exception is typed decisions, where a competing model ranks higher. Smaller models trail by wide margins on BANKING77, MASSIVE, and Mind2Web. Jeva leads seven of eight full-coverage accuracy slices, including BANKING77 and MASSIVE at both candidate counts and all Mind2Web splits. Typed decisions are the only full-coverage slice where Jeva is not the top model. Several smaller models show large accuracy drops on BANKING77, MASSIVE, and Mind2Web.
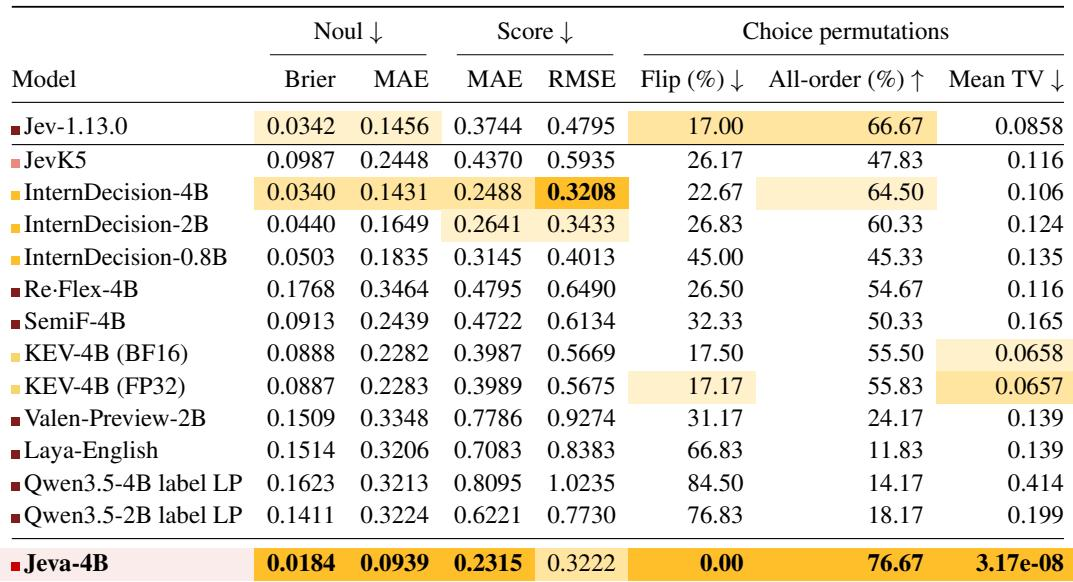
Jeva shows the strongest typed fidelity and order stability among the evaluated models. It achieves the lowest Noul and Score error metrics against soft targets and records zero decision flips across candidate order changes, while other models show higher error and non-zero flip rates. The remaining baselines vary substantially, with smaller variants and Re-Flex showing the largest errors. Jeva records the lowest Noul Brier and MAE against soft probability targets, along with the lowest Score MAE and a Score RMSE close to InternDecision-4B. Jeva has zero choice flips across original, reversed, and seeded random orders, with mean total variation near zero and identical original and all-order accuracy. Jev-1.13.0, InternDecision-4B, and JevK5 show order sensitivity, with flip rates between 17 and 26 percent and reduced all-order accuracy. Among the remaining baselines, InternDecision-0.8B has the highest flip rate, while Re-Flex-4B has the largest Noul and Score errors.
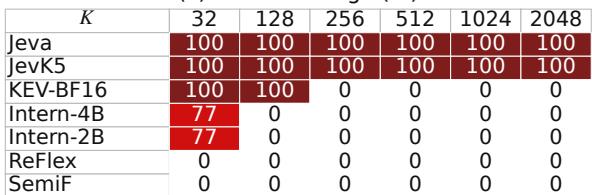
Jeva and JevK5 maintain full valid coverage across all candidate-count cohorts, while other approaches quickly become unsupported as the candidate set grows. Jeva also covers all requests with higher aggregate accuracy than recursive JevK5, and length-aware batching sharply reduces p50 latency at larger candidate counts without changing decisions. Jeva and JevK5 are the only methods with full valid coverage across every tested candidate-count cohort. KEV-BF16 supports the smallest cohorts but drops to zero coverage beyond 128 candidates, while InternDecision variants cover only a subset of requests at 32 candidates and none beyond. ReFlex and SemiF show no valid coverage in any tested cohort. Jeva attains higher aggregate accuracy than recursive JevK5 while scoring complete candidate sets in one decision-head pass. Length-aware batching preserves accuracy and order while cutting p50 latency dramatically at large candidate counts, with roughly an eightfold reduction at the largest cohort. In candidate-set expansion tests, Jeva remains correct at every size on more queries than JevK5 and CLM, and its all-size accuracy exceeds JevK5 by a notable margin.
The experiments evaluate option-bank reuse, decision accuracy, typed fidelity and order stability, and scaling behavior across candidate counts. A reuse test shows whole-set cache lookups always miss, while per-option reuse increases from no hits on the first set to full hits on covered sets, with only previously prepared options reused and decisions remaining fresh. In benchmark and fidelity tests, Jeva leads seven of eight full-coverage accuracy slices, records zero decision flips under order changes, and shows the lowest soft-target errors, while smaller baselines are less accurate or more order-sensitive. Coverage and latency experiments find Jeva and JevK5 are the only methods with full valid coverage across all candidate-count cohorts, with Jeva more accurate than recursive JevK5 and length-aware batching reducing latency without changing decisions.