Command Palette
Search for a command to run...
Neural Machine Translation of Rare Words with Subword Units
Neural Machine Translation of Rare Words with Subword Units
Rico Sennrich Barry Haddow Alexandra Birch
Abstract
Neural machine translation (NMT) models typically operate with a fixed vocabulary, but translation is an open-vocabulary problem. Previous work addresses the translation of out-of-vocabulary words by backing off to a dictionary. In this paper, we introduce a simpler and more effective approach, making the NMT model capable of open-vocabulary translation by encoding rare and unknown words as sequences of subword units. This is based on the intuition that various word classes are translatable via smaller units than words, for instance names (via character copying or transliteration), compounds (via compositional translation), and cognates and loanwords (via phonological and morphological transformations). We discuss the suitability of different word segmentation techniques, including simple character ngram models and a segmentation based on the byte pair encoding compression algorithm, and empirically show that subword models improve over a back-off dictionary baseline for the WMT 15 translation tasks English German and English Russian by up to 1.1 and 1.3 BLEU, respectively.
One-sentence Summary
University of Edinburgh researchers introduce a subword-based approach to open-vocabulary neural machine translation that encodes rare and unknown words as sequences of subword units derived from byte pair encoding, outperforming a dictionary back-off baseline by up to 1.1 and 1.3 BLEU on WMT 15 English-German and English-Russian translation tasks.
Key Contributions
-
The paper introduces an open-vocabulary neural machine translation approach that encodes rare and unseen words as sequences of variable-length subword units, allowing translation without a dictionary back-off system.
-
It presents a byte pair encoding segmentation method, along with simple character bigram segmentation, to build compact subword vocabularies while allowing attention over subword units instead of fixed-length word representations.
-
Experiments on WMT 15 English-German and English-Russian translation tasks show improvements over a back-off dictionary baseline of up to 1.1 and 1.3 BLEU, respectively, and show that reduced-vocabulary subword models also improve translation of rare in-vocabulary words.
Introduction
Neural machine translation has become a powerful approach for translating text, but it struggles with rare and unseen words because neural systems usually rely on a fixed vocabulary. This is especially important for languages with rich morphology or compounding, where new words are created by combining smaller meaningful units.
Prior work often handled unknown words by looking them up in a dictionary or copying them into the output, but these methods can fail when source and target words do not match one-to-one or when transliteration and morphological changes are needed. Word-level models also cannot easily generate words that were not present during training.
The authors leverage subword units to make neural machine translation open-vocabulary directly inside the model. They adapt byte pair encoding to segment words into variable-length character sequences, allowing the network to learn translations for compounds, names, loanwords, and unseen words without relying on back-off dictionaries.
Method
The method integrates a neural machine translation model with a subword segmentation approach. At the core of the system is an encoder-decoder architecture for sequence-to-sequence learning. The encoder reads an input sequence x=(x1,…,xm) using a bidirectional recurrent network. It produces a forward sequence of hidden states (h1,…,hm) and a backward sequence (h1,…,hm). The two directional states are concatenated at each position to form an annotation vector hj, which summarizes the corresponding source word together with its surrounding context.
The decoder generates the target sequence y=(y1,…,yn) one element at a time. Each predicted word yi depends on the current recurrent hidden state si, the previously generated word yi−1, and a context vector ci. The context vector is obtained as a weighted sum of source annotations:
ci=j=1∑mαijhjwhere αij is produced by an alignment model that estimates how strongly target position i should attend to source position j. This alignment model is a feedforward neural network and is trained jointly with the rest of the architecture using backpropagation. The overall model is optimized on parallel sentences with stochastic gradient descent, and inference typically uses beam search with a relatively small beam size.
The translation model is combined with a subword representation layer designed to support open-vocabulary translation. The key intuition is that many hard-to-translate or previously unseen words can still be translated transparently through smaller linguistic units, such as morphemes, shared name components, cognate patterns, or morphological affixes. The authors leverage the assumption that if rare words are split into meaningful or frequent subword pieces, the neural network can learn mappings from source subwords to target subwords and then generalize these mappings to words that were not seen during training.
The main subword method is Byte Pair Encoding, adapted from data compression to character-level segmentation. The procedure begins by representing every word as a sequence of characters plus a special word boundary symbol. This marker allows the model to reconstruct word boundaries after translation. The algorithm then repeatedly counts adjacent symbol pairs in the training text and merges the most frequent pair into a new compound symbol. For example, if the pair (a,b) is highly frequent, it may be replaced by a single symbol ab. Each merge creates a new subword symbol, which can later participate in further merges. The process stops after a specified number of merge operations.
The number of merge operations is the primary hyperparameter. The final subword vocabulary size is determined by the initial character vocabulary plus the number of merges. To improve efficiency, the segmentation process does not merge across word boundaries. This restriction allows the algorithm to operate on a dictionary where each word is weighted by its frequency. In implementation, pair occurrences and merge operations are indexed and updated incrementally. At test time, any input word is first decomposed into characters, then the learned merge operations are applied in order to obtain a subword segmentation. Because the segmentation procedure can be applied to arbitrary character sequences, the model can represent words outside the original training vocabulary without an unknown word class.
Two variants of the segmentation scheme are considered. One variant learns separate subword encodings for the source and target languages. This can produce smaller vocabularies and more compact segmented text, and it ensures that each subword unit is observed in the training text of its own language. The other variant learns a joint encoding over the combined source and target vocabularies. Joint encoding improves consistency between the segmentations of related languages, making it easier for the translation model to align corresponding subword units. For language pairs with different writing systems, this consistency can be improved by temporarily transliterating one language into a shared script for learning the merge operations, then mapping the resulting operations back to the original script.
Experiment
Experiments on WMT 2015 English–German and English–Russian translation compare word-level systems with and without a back-off dictionary against subword-based models using character bigrams, BPE, and joint BPE segmentations. The evaluation validates that compact subword vocabularies can support open-vocabulary translation, with particular gains on rare and unseen words and a clearer advantage for English–Russian due to the need for transliteration. Further frequency-based analysis and manual review show that subword representations improve productivity and robustness, especially when segmentation is more consistent, though overall metric improvements are moderated by the small proportion of rare words and training variability.
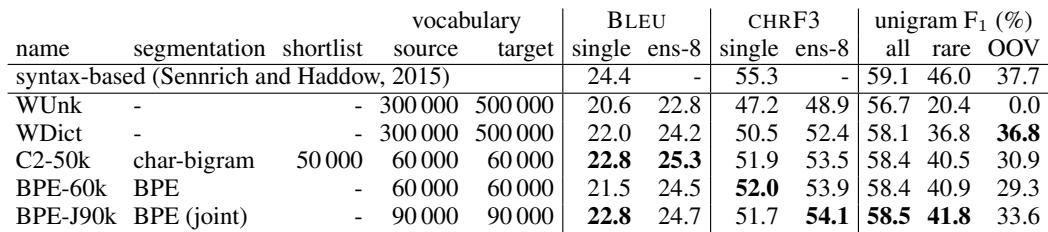
For English to German translation, subword representations generally improve rare word accuracy over word-level baselines while remaining competitive in overall quality. Joint BPE is especially effective for rare words, whereas character bigrams can reach competitive translation scores but introduce more out-of-vocabulary issues. Ensembling models tends to improve performance across the reported measures. Subword segmentation improves rare word handling compared with a word-level back-off dictionary baseline. Joint BPE gives the strongest rare-word overlap, while character bigrams remain viable but less reliable for unseen words.
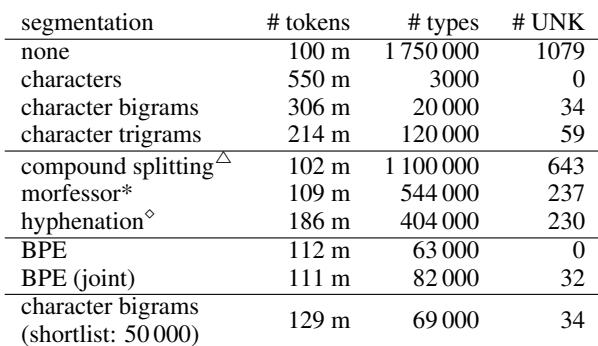
The corpus statistics show that character based segmentations greatly reduce unknown tokens by representing words with smaller units, but they substantially increase token sequences. Frequency, hyphenation, and Morfessor segmentations lower vocabulary size only moderately and still leave unknown words, making them less suitable for open vocabulary German translation. BPE and joint BPE provide compact subword representations with fewer sequence elements while remaining open vocabulary after applying learned merges. Character segmentations trade much longer sequences for much smaller vocabularies and very few unknown tokens. Compound splitting, hyphenation, and Morfessor reduce vocabulary size but do not eliminate unknown tokens. BPE gives a shorter subword representation than character n grams and can segment new text without unknown symbols.
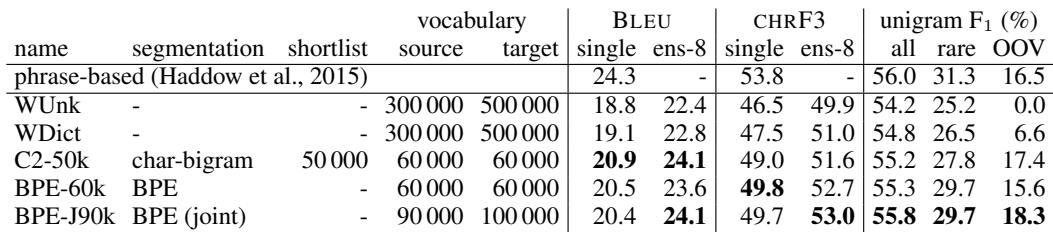
Across English Russian translation quality and word coverage metrics, subword segmentation systems consistently surpass word level baselines with a back off dictionary. The gains are largest for rare words and for unknown words that require transliteration across different alphabets. Among subword variants, joint BPE segmentation with ensembles gives the strongest coverage on rare and unknown words, while single models can vary in overall translation scores. Ensemble models attain higher BLEU and CHRF3 scores than their single model counterparts. Subword systems improve unigram F1 over dictionary based baselines, especially on rare words. For English Russian, where names must be transliterated, subword models handle unknown words much better than the back off dictionary baseline. Joint BPE segmentation is more effective than separately learned BPE or character bigrams for rare and unknown word recognition. A back off dictionary improves unknown word handling compared with an UNK only word model, but helps less for transliterating Russian names.
In the English German examples, the dictionary baseline fails by dropping content or copying words that should be translated, while subword systems can generate correct compound translations even when the subword segmentation oversplits or does not match morpheme boundaries. For sparse source terms, some systems produce wrong but loanword-like outputs instead of learned translations. Related results indicate that inconsistent segmentations cause copy or transliteration errors, while the joint BPE system improves segmentation consistency and out-of-vocabulary handling. Subword systems recover translations of compound words despite imperfect segmentation. The baseline can omit required content or leave source words untranslated. Inconsistent segmentations contribute to transliteration errors and spurious character changes. The joint BPE system improves consistency and out-of-vocabulary handling over standard BPE.
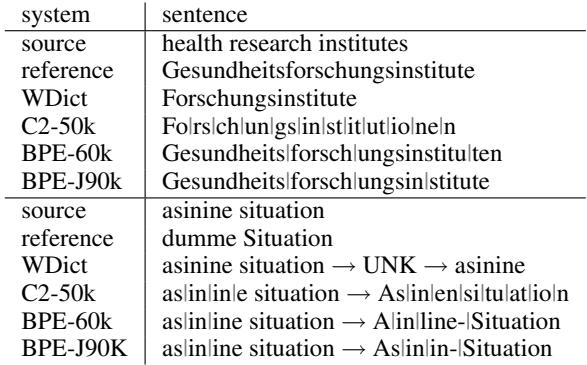
In English Russian translation of names and rare terms, the dictionary baseline tends to copy the source or fail to produce a target form, while subword models can generate Cyrillic transliterations. The joint subword encoding is presented as a more consistent option, because irregular segmentations can introduce inserted or missing characters. Subword systems can transliterate unknown English words into Russian even when direct copying is not useful. Joint subword segmentations support more stable target side mappings than inconsistent BPE segmentations. The baseline fails on the shown English Russian examples by leaving source material untranslated.
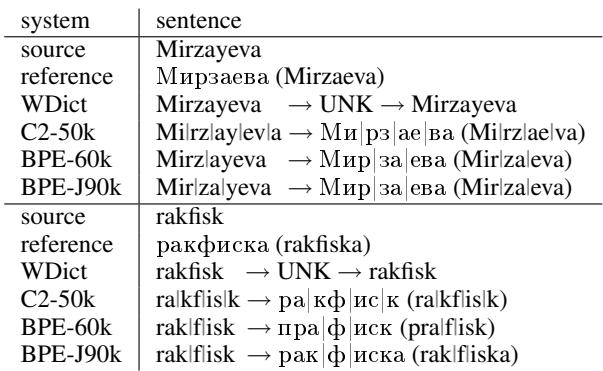
Experiments compare word-level back-off dictionary baselines with subword segmentations for English-German and English-Russian translation, including BPE, joint BPE, character bigrams, frequency-based, hyphenation, and Morfessor variants. Subword models generally handle rare, unseen, and transliteration-heavy cases better than word-level baselines, with joint BPE and ensembles giving the strongest consistency and coverage. Corpus analysis shows that character segmentations reduce unknown tokens at the cost of much longer sequences, while BPE variants remain compact and open vocabulary. Qualitative examples further show that subword systems can translate compounds and transliterate names where baselines drop content or copy source text.