Command Palette
Search for a command to run...
CausalGym: Benchmarking causal interpretability methods on linguistic tasks
CausalGym: Benchmarking causal interpretability methods on linguistic tasks
Aryaman Arora Dan Jurafsky Christopher Potts
Abstract
Language models (LMs) have proven to be powerful tools for psycholinguistic research, but most prior work has focused on purely behavioural measures (e.g., surprisal comparisons). At the same time, research in model interpretability has begun to illuminate the abstract causal mechanisms shaping LM behavior. To help bring these strands of research closer together, we introduce CausalGym. We adapt and expand the Syntax-Gym suite of tasks to benchmark the ability of interpretability methods to causally affect model behaviour. To illustrate how CausalGym can be used, we study the pythia models (14M–6.9B) and assess the causal efficacy of a wide range of interpretability methods, including linear probing and distributed alignment search (DAS). We find that DAS outperforms the other methods, and so we use it to study the learning trajectory of two difficult linguistic phenomena in pythia-1b: negative polarity item licensing and filler-gap dependencies. Our analysis shows that the mechanism implementing both of these tasks is learned in discrete stages, not gradually.
One-sentence Summary
Stanford University introduces CausalGym, a benchmark adapted from Syntax-Gym that evaluates whether interpretability methods can causally affect language model behavior, finding that distributed alignment search outperforms alternatives on pythia models (14M–6.9B) and revealing that the mechanisms implementing negative polarity item licensing and filler-gap dependencies are learned in discrete stages rather than gradually.
Key Contributions
- CausalGym is introduced as a benchmark adapted from SyntaxGym that uses templated minimal pairs and model interventions to measure whether interpretability methods identify features that causally affect linguistic behavior in language models, with evaluation on Pythia models from 14M to 6.9B parameters.
- The study benchmarks linear probing and distributed alignment search on causal tasks, finds distributed alignment search is most causally efficacious, and introduces control tasks from probing to account for arbitrary input-output mappings, making comparisons fairer by narrowing the gap with other methods.
- CausalGym with distributed alignment search is used to analyze negative polarity item licensing and filler-gap dependency learning in Pythia-1b, finding that the causal mechanisms rely on multi-step movement of information and emerge in discrete stages rather than gradually.
Introduction
Language models are increasingly used as psycholinguistic tools for estimating word surprisal, grammaticality, and broader language processing behavior, with targeted syntactic benchmarks testing whether they assign higher probability to grammatical sentence pairs. A major limitation of this line of work is that it evaluates input-output behavior without revealing the internal mechanisms behind model decisions. At the same time, interpretability methods such as probing and distributed alignment search have mostly been tested on narrow datasets rather than diverse, psycholinguistically grounded benchmarks. The authors leverage the linear representation hypothesis and interventional methods to introduce CausalGym, a benchmark adapted from SyntaxGym that measures whether interpretability methods can identify linear feature subspaces whose manipulation causally changes linguistic behavior. They also adapt control tasks from probing to prevent methods from succeeding merely by producing arbitrary input-output mappings, enabling fairer evaluation.
Dataset
-
The authors introduce CausalGym, a dataset built by converting SyntaxGym's core English-language test suites into template-based generators for span-aligned minimal pairs.
-
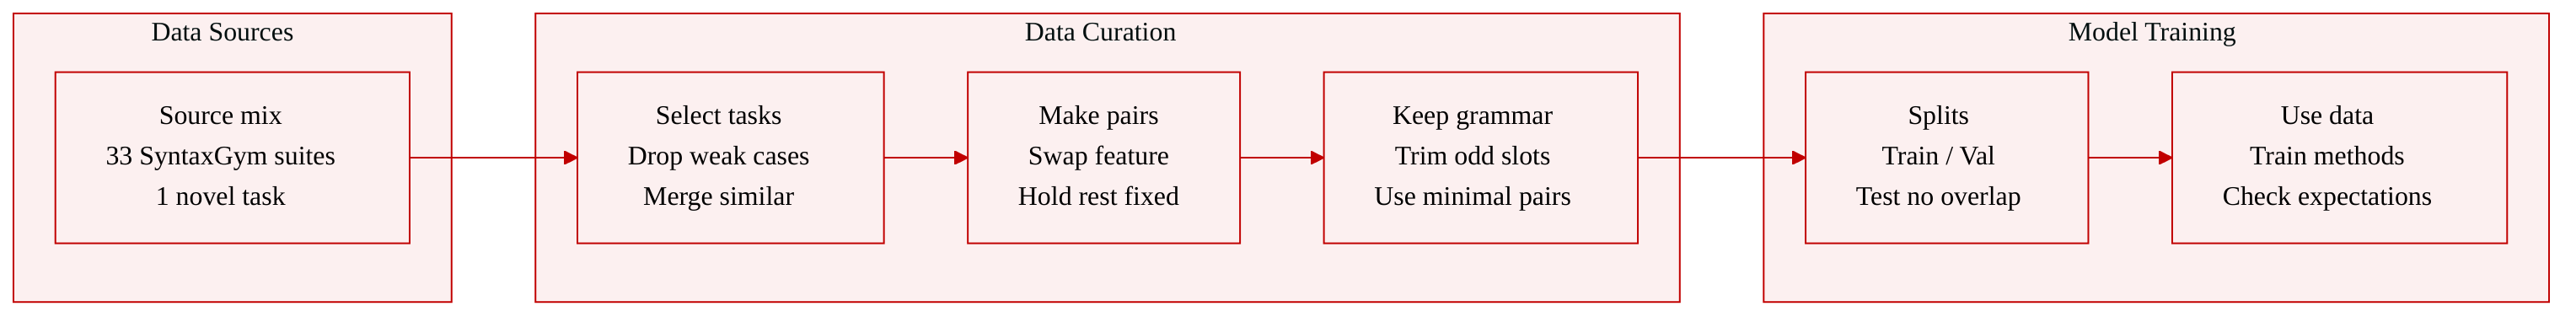
The benchmark starts from 33 SyntaxGym test suites. The authors discard 2 center-embedding tasks, merge 6 gendered reflexive licensing tasks into 3 non-gendered tasks, and keep tasks that allow paired grammatical sentences, yielding 28 templatised tasks. They add 1 novel task, agr_gender, for a total of 29 tasks.
-
Source tasks from SyntaxGym focus on one linguistic feature at a time. Each item uses the same template and region structure, holds irrelevant features constant, and varies only the feature of interest across conditions.
-
Because the original test suites contain fewer than 50 items, the authors template them to generate much larger corpora. They use the aligned syntactic regions as slots that can be mixed and matched across items to combinatorially create new examples.
-
The authors convert SyntaxGym conditions into supervised input-output pairs by selecting only the two grammatical conditions per item and recasting the behavior as a counterfactual mapping. For example, subject number determines the expected next verb, while other parts of the sentence, including distractor nouns, remain constant.
-
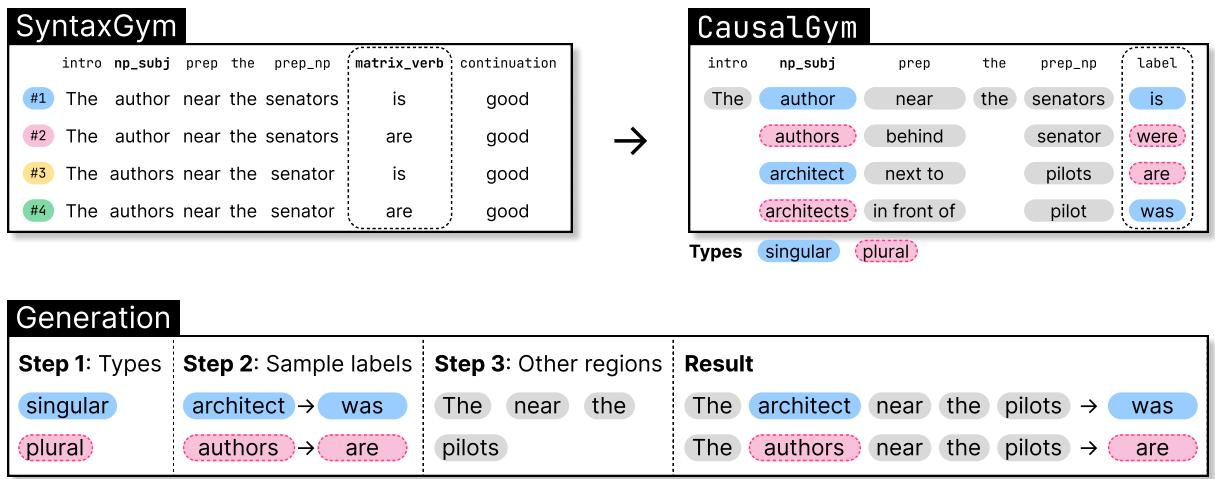
Each template includes types for the label variable and the expected next-token label. To generate a pair, the authors sample two different types, choose an option of the first type for one sentence and an option of the second type for the other, then sample a shared option for all non-label regions so that only the relevant feature changes.
-
The dataset is filtered by requiring grammatical pairs and by manually removing slot options that could produce questionably grammatical sentences.
-
The authors use the generated data to train supervised interpretability methods, construct non-overlapping test sets, and evaluate whether language models produce human-like expectations when input features change.
Method
The authors build the method as a coupled pipeline that first converts linguistic benchmark items into dense counterfactual templates and then uses those templates to study causal mechanisms inside language models. The central idea is to simplify each original test item into a minimal input-output transformation that varies a single linguistic feature, such as subject number, while holding all other content fixed. This makes the behavior suitable for supervised feature discovery and causal intervention.
To create enough usable data for training interpretable models, the authors select the two grammatical conditions from each original item and recast them as counterfactual pairs. For example, subject-verb number agreement is represented as two sentences that differ only in the grammatically relevant subject slot and the corresponding agreeing verb:
The author near the senators⇒is The authors near the senators⇒areIn the original benchmark, each item is relatively small and contains only a few examples. The authors therefore decompose each item into aligned regions and reuse those regions as slots in a templatic generation system. Each template has a set of types that govern both the variable label region and the expected next-token label. To generate a counterfactual pair, the procedure first samples two distinct types t1 and t2. It then samples one option of type t1 for the first sentence and one option of type t2 for the second sentence. All non-label regions are sampled once and shared across the pair so that only the intended feature changes. The authors also apply a manual filtering step by removing slot options that could produce sentences whose grammaticality is uncertain. Refer to the framework diagram.
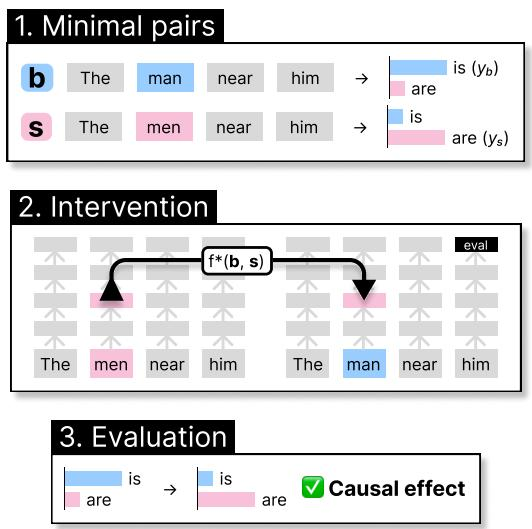
The downstream analysis is centered on an intervention function. The authors benchmark interventions along a single feature direction using one-dimensional distributed interchange intervention, abbreviated as 1D DII. Let f be a function that maps an input representation to a token-level representation. Given a feature direction a∈Rn, the intervention function replaces f with fa∗, defined as
fa∗(b,s)=f(b)+(f(s)a⊤−f(b)a⊤)awhere b is the base input and s is the counterfactual input. The intervened model is written as
pf←fa∗The authors fix f to operate on token-level representations. Because the base and counterfactual sequences may have different lengths after tokenization, representations are aligned at the last token of each template region. This one-dimensional intervention form is chosen because binary linguistic features can often be controlled through a one-dimensional subspace of the model's activation space. It also aligns naturally with linear probes, whose learned class directions can be used directly as intervention vectors.
The benchmark compares several methods for discovering the feature direction a. The supervised methods include distributed alignment search, linear probing, difference in means, and linear discriminant analysis. The unsupervised methods include principal component analysis, two-component clustering, and a random direction baseline. Each method outputs a vector a, which is then used as a fixed direction inside the 1D DII function.
Distributed alignment search learns the intervention direction directly from counterfactual training data. The procedure initializes adas, freezes the base model weights, and optimizes only the intervention vector so that the intervened model assigns high probability to the desired counterfactual output ys. The training objective is
adasmin−(b,s,yb,ys)∈T∑logpf←fadas∗(ys∣b,s)The learned adas then defines the intervention function fadas∗.
Linear probing trains a softmax classifier on base input-output examples. Given a representation x, the probe is
qθ(y∣x)=softmax(aprobe⋅f(x)+b)The parameters are optimized on the base training set, typically by maximizing the likelihood of the base label yb. The probe weight vector aprobe is then reused as the causal intervention direction.
Difference in means learns the direction from the separation between class means. Let X1 and X2 be the sets of base examples associated with two target classes. The learned direction is
amean=∣X1∣1x∈X1∑f(x)−∣X2∣1x∈X2∑f(x)or equivalently
amean=μ1−μ2Linear discriminant analysis extends this idea by assuming class-specific means and a shared covariance matrix Σ. Its intervention direction is
alda=Σ−1(μ1−μ2)Principal component analysis does not use class labels. It selects the first principal component of mean-centered activations as the intervention direction. The objective is to maximize variance along that direction:
apcamaxx∈X1∪X2∑(f(x)⋅apca)2where f(x) denotes mean-centered activation.
For clustering-based discovery, the authors use two-component clustering on activations. If the two clusters have centroids μ1 and μ2, the direction is
akmeans=μ1−μ2Together, these components form the experimental architecture: templatised counterfactual generation supplies controlled training and evaluation examples, feature-finding methods produce candidate feature directions, and 1D distributed interchange intervention tests whether those directions causally control the linguistic behavior being studied.
Experiment
The evaluation uses CausalGym, a large templatised benchmark derived from SyntaxGym, to test whether language models represent linguistic features in causally aligned ways by intervening on residual stream components and measuring log odds-ratio shifts across the Pythia model series. Experiments compare feature-finding methods on many tasks, finding that supervised methods, especially DAS, identify causally impactful subspaces more effectively than unsupervised approaches, though DAS also performs well on control tasks, indicating part of its advantage reflects expressivity rather than pure linguistic selectivity. Case studies on NPI licensing and filler-gap dependencies further show that models implement complex distributed mechanisms that emerge and expand during training.
Across model scales, DAS consistently identifies the most causally efficacious features, followed by probing and difference-in-means, while unsupervised methods perform substantially worse. Supervised LDA barely exceeds random features, and average task accuracy rises with model scale. DAS is not clearly more selective than probing or difference-in-means at larger scales, suggesting that access to model outputs during training contributes to its advantage. DAS shows the strongest feature-finding performance across sizes, with a larger absolute advantage over probing as model scale increases. DAS selectivity remains comparable to or lower than probing and difference-in-means at larger scales, supporting the idea that its advantage comes partly from using model outputs.
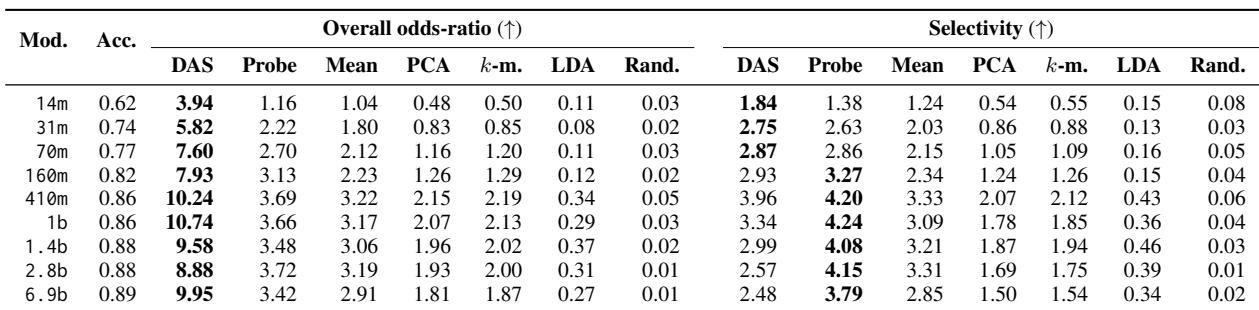
Across model scales, the experiments evaluate methods for identifying causally efficacious features and show that DAS consistently performs best, followed by probing and difference-in-means, while unsupervised methods perform substantially worse and supervised LDA barely exceeds random features. Average task accuracy rises with model scale, and DAS gains a larger absolute feature-finding advantage over probing as models become larger. Its selectivity remains comparable to or lower than probing and difference-in-means at larger scales, supporting the idea that its advantage partly comes from access to model outputs during training.