Command Palette
Search for a command to run...
HATEDAY: Insights from a Global Hate Speech Dataset Representative of a Day on Twitter
HATEDAY: Insights from a Global Hate Speech Dataset Representative of a Day on Twitter
Manuel Tonneau Diyi Liu Niyati Malhotra Scott A. Hale Samuel P. Fraiberger Victor Orozco-Olvera Paul Röttger
Abstract
To address the global challenge of online hate speech, prior research has developed detection models to flag such content on social media. However, due to systematic biases in evaluation datasets, the real-world effectiveness of these models remains unclear, particularly across geographies. We introduce HATEDAY, the first global hate speech dataset representative of social media settings, constructed from a random sample of all tweets posted on September 21, 2022 and covering eight languages and four English-speaking countries. Using HATEDAY, we uncover substantial variation in the prevalence and composition of hate speech across languages and regions. We show that evaluations on academic datasets greatly overestimate real-world detection performance, which we find is very low, especially for non-European languages. Our analysis identifies key drivers of this gap, including models' difficulty to distinguish hate from offensive speech and a mismatch between the target groups emphasized in academic datasets and those most frequently targeted in real-world settings. We argue that poor model performance makes public models ill-suited for automatic hate speech moderation and find that high moderation rates are only achievable with substantial human oversight. Our results underscore the need to evaluate detection systems on data that reflects the complexity and diversity of real-world social media.
One-sentence Summary
Researchers at the University of Oxford, World Bank, and other institutions introduce HATEDAY, the first globally representative hate speech dataset constructed from a random sample of all tweets posted on September 21, 2022 across eight languages, demonstrating that academic evaluation datasets greatly overestimate real-world detection performance, particularly for non-European languages.
Key Contributions
- HATEDAY is introduced as the first global hate speech dataset built from 240,000 annotated tweets randomly sampled from all tweets posted on September 21, 2022, spanning eight languages and four English-speaking countries.
- Using HATEDAY, the study shows that standard academic datasets greatly overestimate real-world detection performance, especially for non-European languages, and identifies causes such as difficulty distinguishing hate from offensive speech and mismatched target groups between academic data and real discourse.
- The moderation assessment shows that fully automatic use of publicly available models is too error-prone, while human review of flagged content can achieve higher moderation rates across languages and countries but requires substantial oversight.
Introduction
Social media platforms increasingly rely on automated hate speech detection to moderate content that can escalate into offline harm, making model performance on real feeds a practical safety concern. Prior work provides an incomplete picture because platform models are often opaque, academic benchmarks use biased and imbalanced datasets, and most resources are English only, which limits generalization and comparisons across languages. The authors also note that grouping content only by language can hide important differences between countries that share a language. To address these gaps, they introduce HATEDAY, a global Twitter dataset of 240,000 tweets sampled across eight languages and four English speaking countries, and use it to compare hate prevalence, evaluate public detection models, and test moderation workflows. Their evaluation shows that standard academic benchmarks overestimate real world performance, public models perform poorly in deployed settings, especially for non European languages, and fully automated moderation is too error prone, while human review can improve moderation at substantial manual cost.
Dataset
-
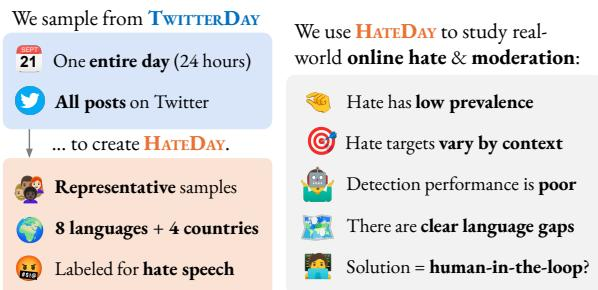
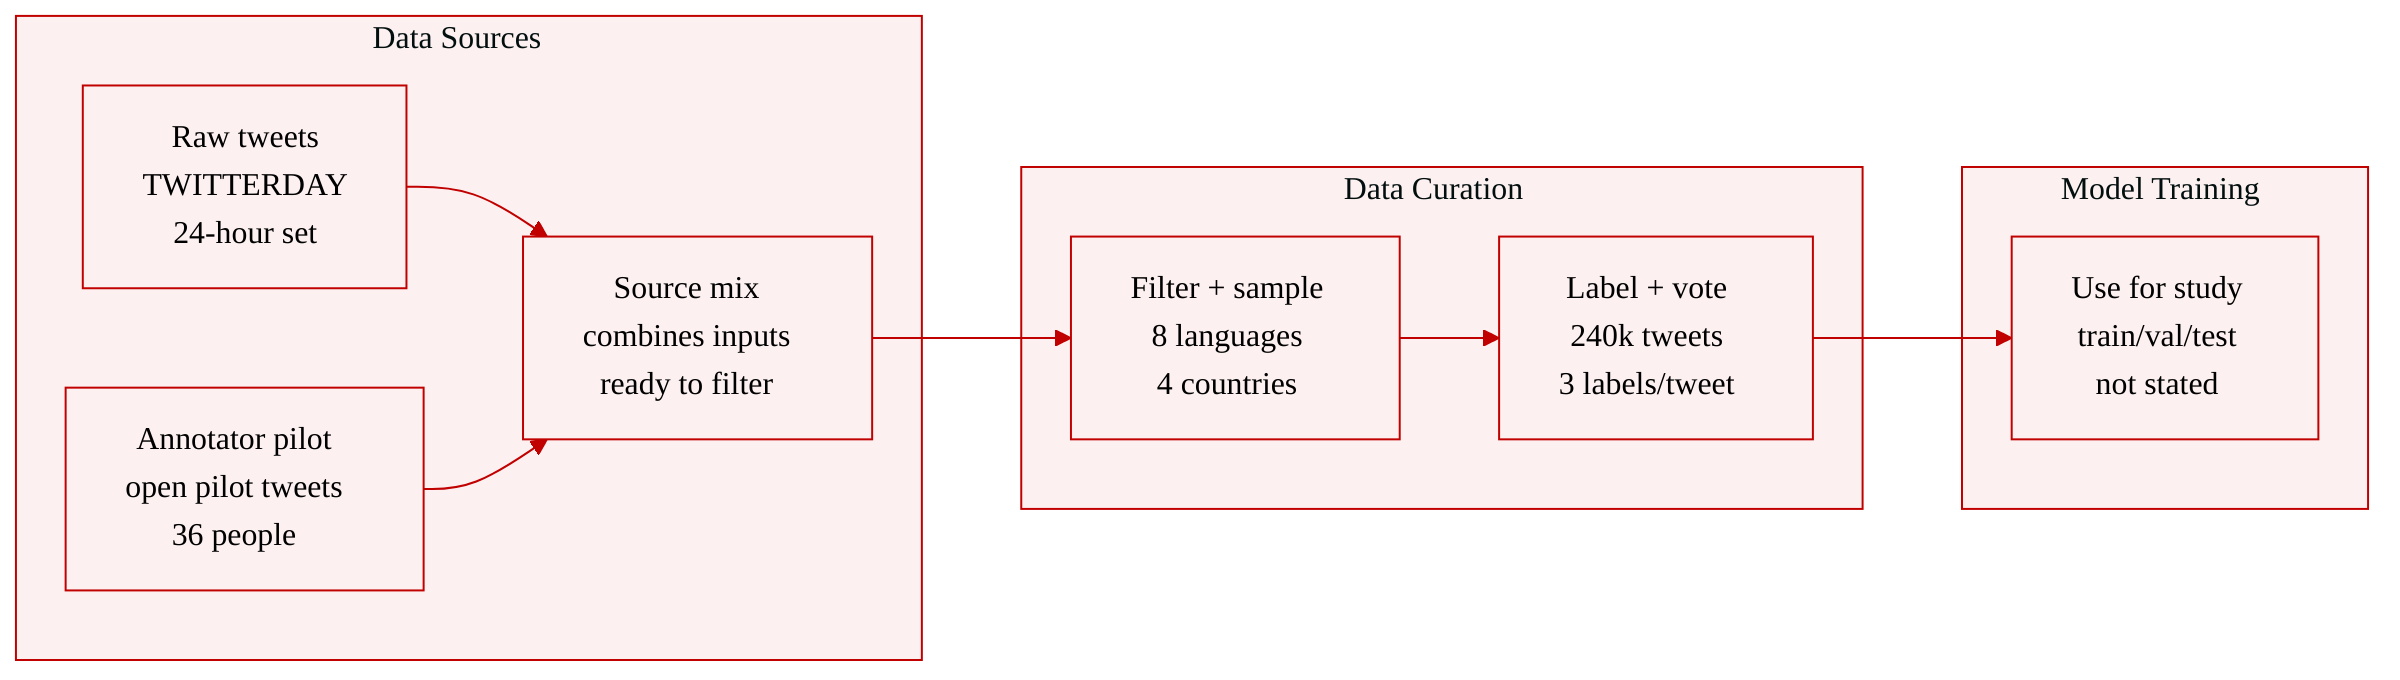
The authors build the HATEDAY dataset from the TWITTERDAY collection, which contains all Twitter posts from a 24-hour period starting on September 21, 2022, totaling about 375 million tweets from roughly 40 million users.
-
The dataset is constructed by applying language-level and country-level filters to TWITTERDAY:
- Language filter: The authors retain eight widely used languages with available hate speech detection resources: Arabic, English, French, German, Indonesian, Portuguese, Spanish, and Turkish.
- Country filter: For English, they additionally focus on four English-dominant Twitter markets: India, Kenya, Nigeria, and the United States.
-
User country is inferred from self-reported profile locations using the Google Geocoding API, with the authors noting that this approach has limitations.
-
Before sampling, the authors remove retweets so the dataset emphasizes original user content.
-
The final HATEDAY dataset consists of 240,000 annotated tweets:
- 20,000 tweets are randomly sampled for each of the eight retained languages.
- 20,000 tweets are randomly sampled for each of the four retained countries.
- These samples are intended to represent real-world Twitter activity within each language and country context.
-
The annotation setup includes 36 annotators, with three annotators assigned per language or country.
- For globally spoken languages such as English, Arabic, and French, the authors try to increase the geographic diversity of annotators.
-
Tweets are labeled into three categories:
- Hateful: posts that promote violence or directly attack, abuse, or threaten individuals or groups based on perceived identity characteristics.
- Offensive: posts that are objectionable but not hateful, including insults, threats, profanity, or swear words.
- Neutral: posts that are neither hateful nor offensive.
-
For hateful tweets, annotators also record the targeted group as free-text metadata.
-
Each annotator first completes a pilot phase, labeling 100 tweets drawn from open-source hate speech datasets on Hugging Face, repeated until inter-annotator agreement reaches a Krippendorff’s alpha threshold of 0.7.
-
Each tweet in the final sample is labeled by three annotators, and the final label is decided by majority vote. Agreement statistics show full agreement on 93.4% of tweets, partial agreement on 6.4%, and full disagreement on only 0.2%.
-
The authors use the resulting dataset to study the prevalence and nature of harmful content on Twitter.
- Hate speech is rare overall, averaging about 0.7% of posts and staying below 2% across languages and countries.
- Offensive content is much more common than hateful content, by factors ranging from 2.5 times in French to 19 times in Portuguese.
-
The annotated data also supports analysis of hate speech targets.
- The most common targets are political, racial, and gender-related groups.
- Context-specific patterns emerge, such as high religious hate speech in India, strong political hate speech in Germany, and forms like casteism appearing primarily in India.
Method
The authors leverage a structured annotation pipeline to produce consistent and subjectivity controlled labels for hate speech detection. The workflow begins by assigning each tweet to one of three semantic classes. A tweet is labeled as hateful if it promotes violence or contains a direct attack, abuse, or threat against an individual or a group based on perceived characteristics such as gender or race. A tweet is labeled as offensive if it contains potentially objectionable language that is not hateful, including insults, threats, profanity, or swear words. A tweet is labeled as neutral if it is neither hateful nor offensive. For tweets classified as hateful, annotators also provide a free text label identifying the targeted group, which creates a richer annotation signal beyond a single class assignment.
The annotation process is designed to reduce annotator subjectivity through prescriptive instructions and quality controlled training. A team of annotators is organized by language or country, and annotators working on globally spoken languages are selected to maximize diversity of origin. All annotators follow extensive guidelines that describe the hate speech taxonomy and clarify the boundary between hateful, offensive, and neutral content. Before annotating the main sample, each annotator completes a pilot phase using posts from previously open sourced annotated datasets. In this phase, annotators label 100 posts, and the process is repeated until interannotator agreement, measured by Krippendorff’s α, reaches a threshold of 0.7.
Once annotators pass the pilot phase, they label a random sample of 20,000 tweets for their assigned language or country. Each tweet is independently annotated by three annotators, and the final label is determined by simple majority vote. This multi annotator design creates redundancy and allows noisy individual judgments to be resolved through consensus. The resulting agreement statistics indicate a highly aligned annotation process: the three annotators agree on 93.4% of tweets, two annotators agree in an additional 6.4% of cases, and all three annotators disagree in only 0.2% of cases. The workflow therefore combines a predefined taxonomy, guided training, repeated agreement checks, redundant labeling, and majority voting to construct a reliable supervised signal for downstream model training.
Experiment
The experiments evaluate supervised hate-speech detectors, a widely used toxicity API, and zero-shot large language models on representative HATE-DAY social media data, alongside academic datasets and functional tests. They validate that real-world detection is far weaker than benchmark evaluations suggest, with supervised methods generally outperforming zero-shot models and the API often leading, while performance varies across languages and countries. Further analyses attribute the gap to offensive false positives, missing context, target misalignment between academic datasets and real-world hate prevalence, and the high human-review burden of moderation, implying that fully automated moderation is not viable.
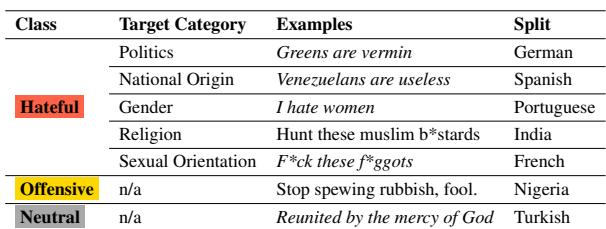
The examples distinguish hateful tweets, which target specific groups such as political, national, gender, religious, or sexual orientation groups, from offensive tweets that contain objectionable language but no specified target. They also show neutral tweets as ordinary language that is neither hateful nor offensive. This suggests that target identification is central to the hateful category, while offensive tweets are defined more by tone and profanity than by a group target. Hateful examples are tied to concrete target categories, including politics, nationality, gender, religion, and sexual orientation. Offensive and neutral examples have no target, with offensive tweets marked only by insulting or profane language.
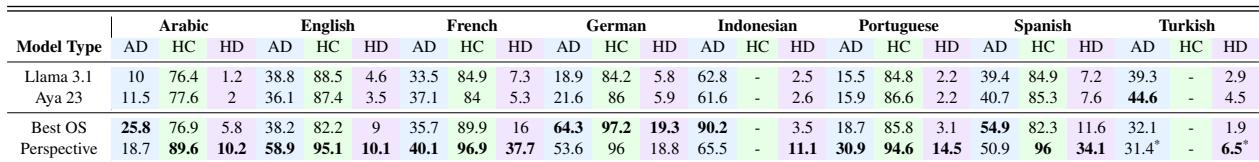
Models perform substantially better on academic hate speech datasets and functional tests than on the representative real-world dataset. Across languages and countries, real-world detection remains limited, with stronger results for European languages and Indian data and weaker results for non-European languages and several other contexts. Supervised models generally score better than zero-shot open-source models, while the Perspective API shows strong functional-test performance and often higher real-world detection than open-source hate speech models. Detection performance drops sharply on real-world data compared with academic and functional test settings. European languages and Indian tweets generally show higher real-world accuracy than non-European languages and other countries. Supervised open-source models and the Perspective API often outperform zero-shot open-source models on real-world detection.
Across countries, model performance is much lower on real-world evaluation than on academic evaluation. Open-source models show the strongest real-world results in Nigeria, while the Perspective API performs relatively higher in the United States and India. Kenya lacks open-source supervised models for direct comparison, highlighting a coverage gap. Academic evaluation precision is consistently higher than real-world precision for both open-source and API models. The Perspective API outperforms open-source models on real-world data in the United States and India, while open-source models are strongest in Nigeria. No open-source supervised models are available for the Kenyan context, limiting model comparison there.
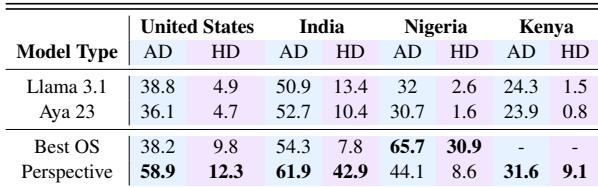
The examples clarify that hateful tweets depend on attacks against specific target groups, whereas offensive tweets are characterized mainly by insulting or profane language without a specified target. Experiments comparing academic tests with real-world, multilingual data show that hate speech detection is much harder in real-world settings, with generally stronger performance for European-language and Indian contexts and weaker performance for several non-European languages and regions. Supervised open-source models and the Perspective API typically outperform zero-shot models, though model strengths vary by country and coverage gaps remain.