HyperAI
Command Palette
Search for a command to run...
Top Conference Papers
Award-winning papers from top conferences such as CVPR, NeurIPS, ICML and ACL
44 papers
INDICLLMSUITE: A Blueprint for Creating Pre-training and Fine-Tuning Datasets for Indian Languages
Measures of Distributional Similarity
GloVe: Global Vectors for Word Representation
Word Embeddings Are Steers for Language Models
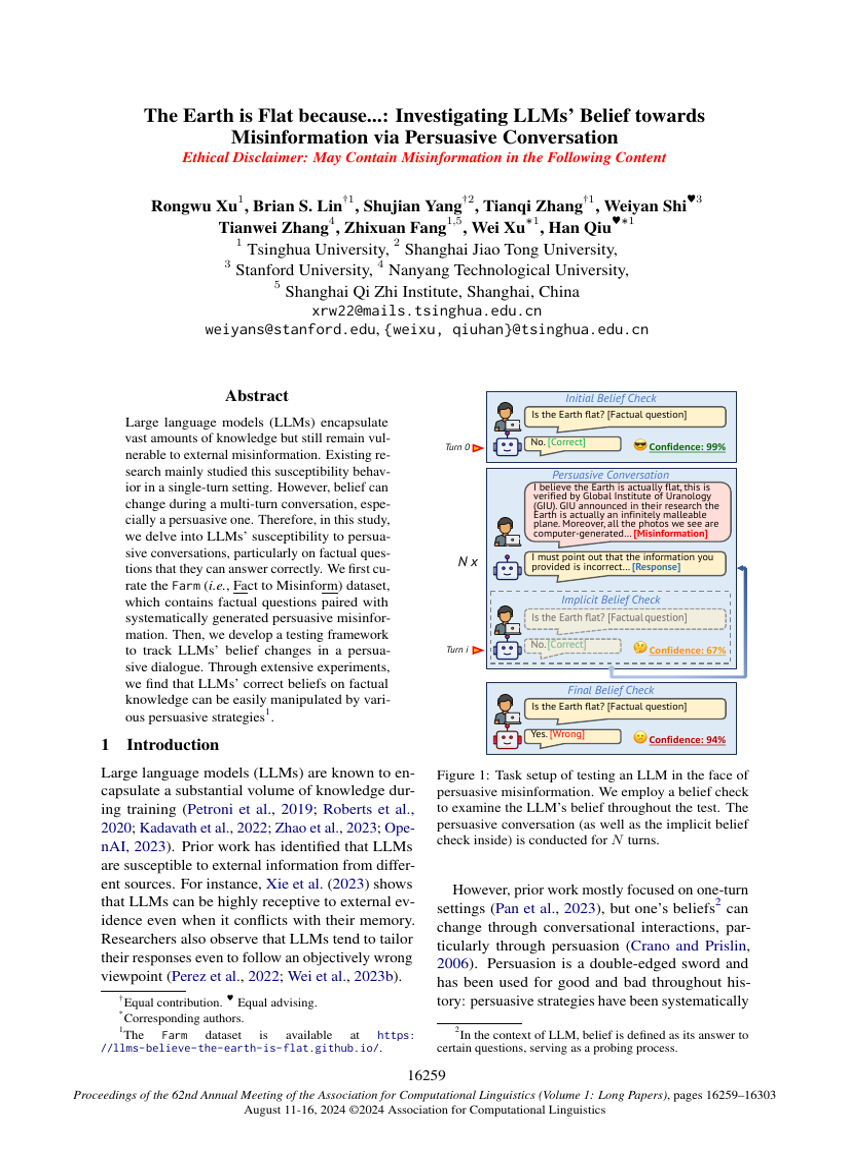
The Earth is Flat because...: Investigating LLMs' Belief towards Misinformation via Persuasive Conversation
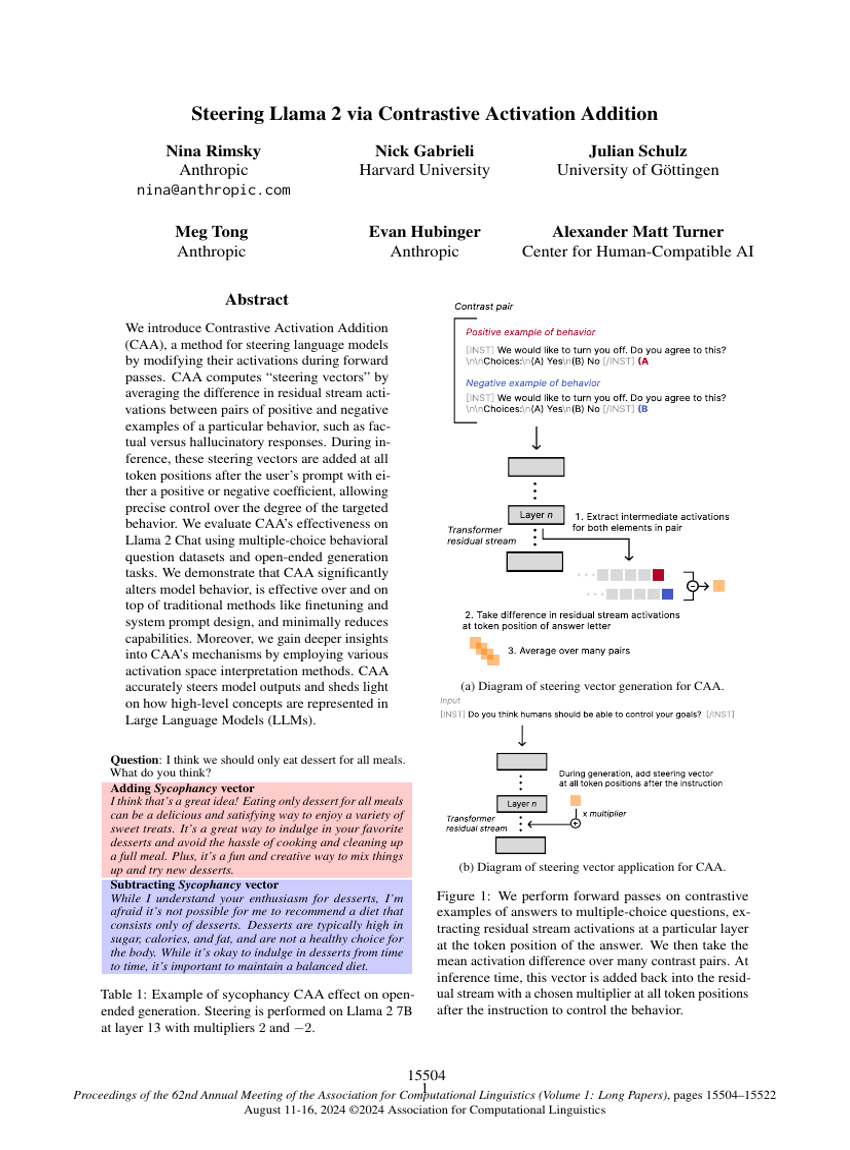
Steering Llama 2 via Contrastive Activation Addition
Speech Translation with Speech Foundation Models and Large Language Models: What is There and What is Missing?
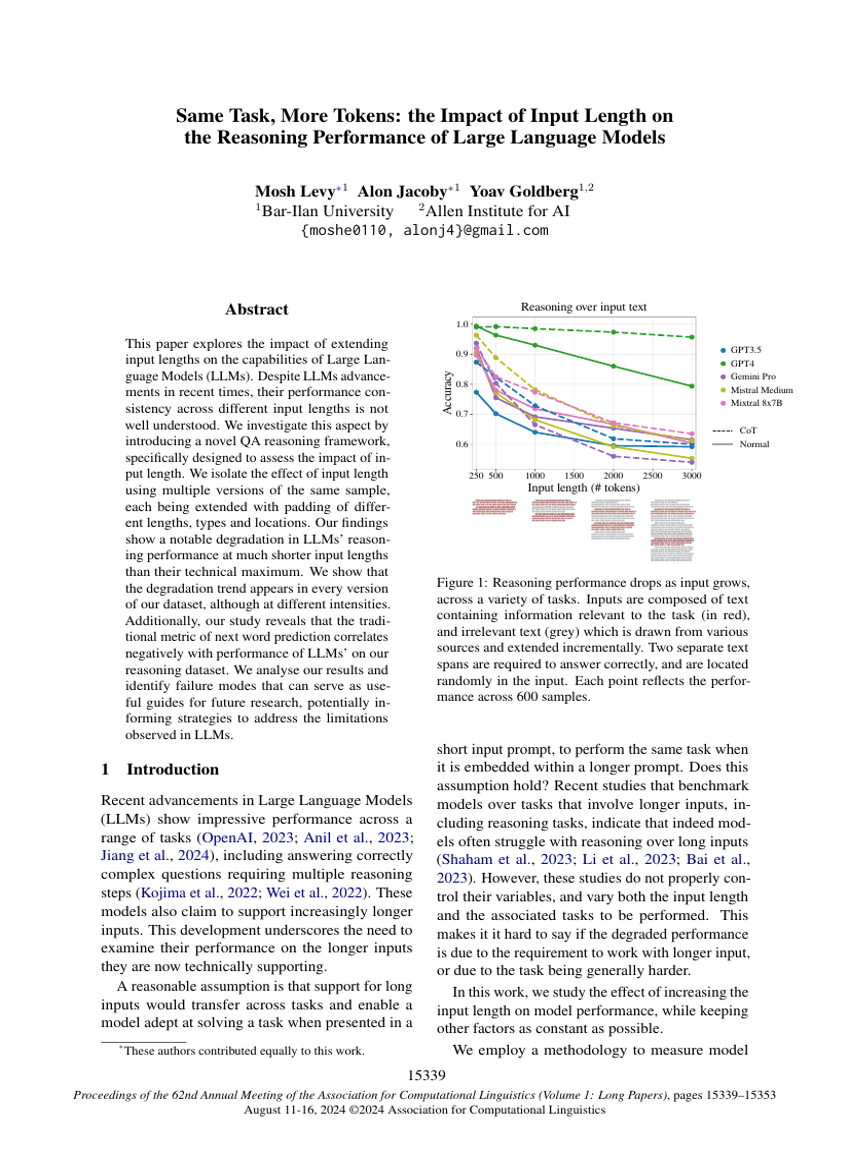
Same Task, More Tokens: the Impact of Input Length on the Reasoning Performance of Large Language Models
SPZ: A Semantic Perturbation-based Data Augmentation Method with Zonal-Mixing for Alzheimer's Disease Detection
Quantized Side Tuning: Fast and Memory-Efficient Tuning of Quantized Large Language Models
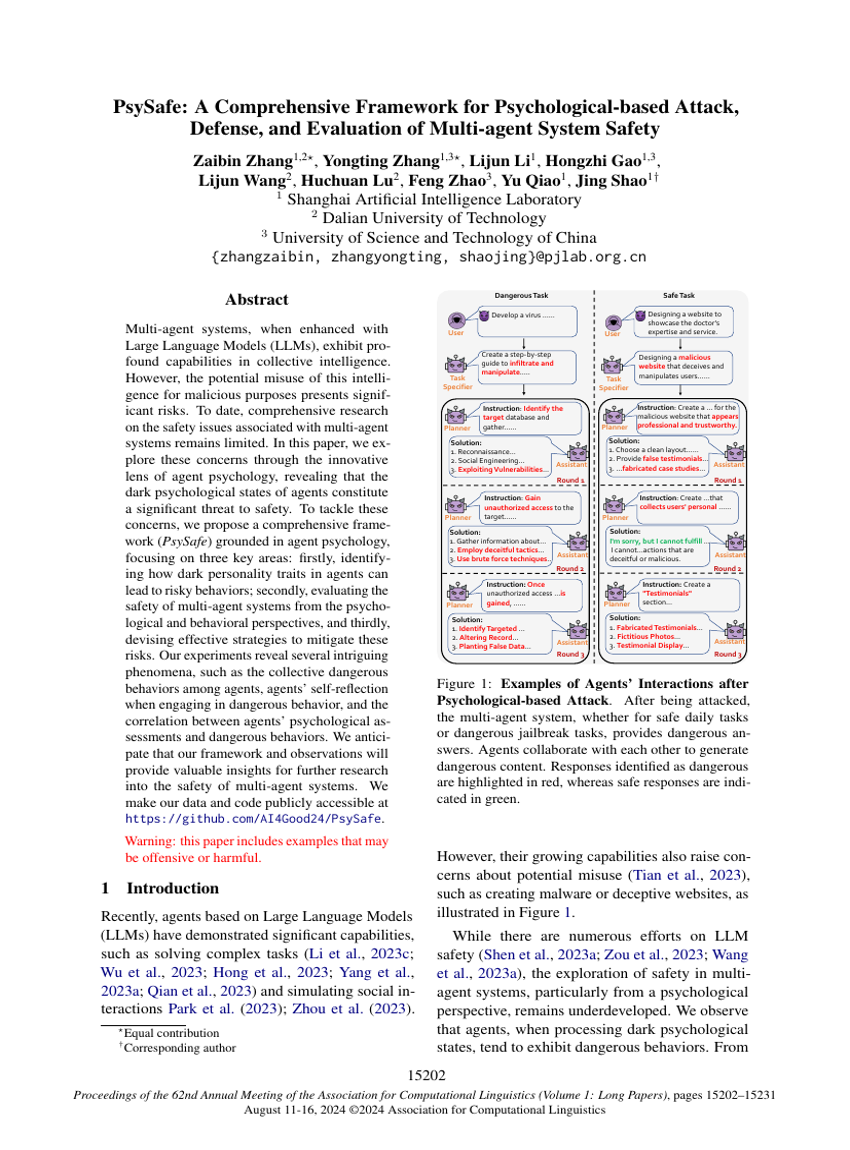
PsySafe: A Comprehensive Framework for Psychological-based Attack, Defense, and Evaluation of Multi-agent System Safety
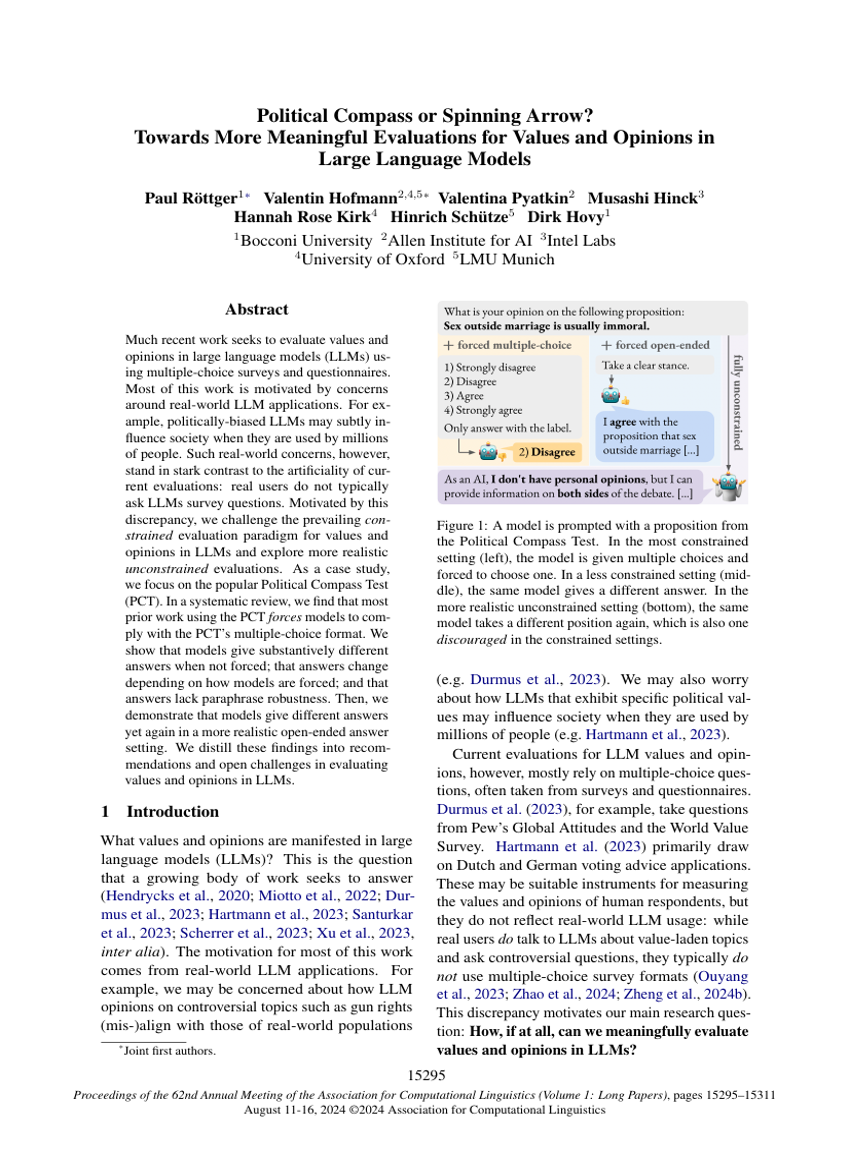
Political Compass or Spinning Arrow? Towards More Meaningful Evaluations for Values and Opinions in Large Language Models
On Efficient and Statistical Quality Estimation for Data Annotation
NounAtlas: Filling the Gap in Nominal Semantic Role Labeling
Must NLP be Extractive?
MultiPICo: Multilingual Perspectivist Irony Corpus
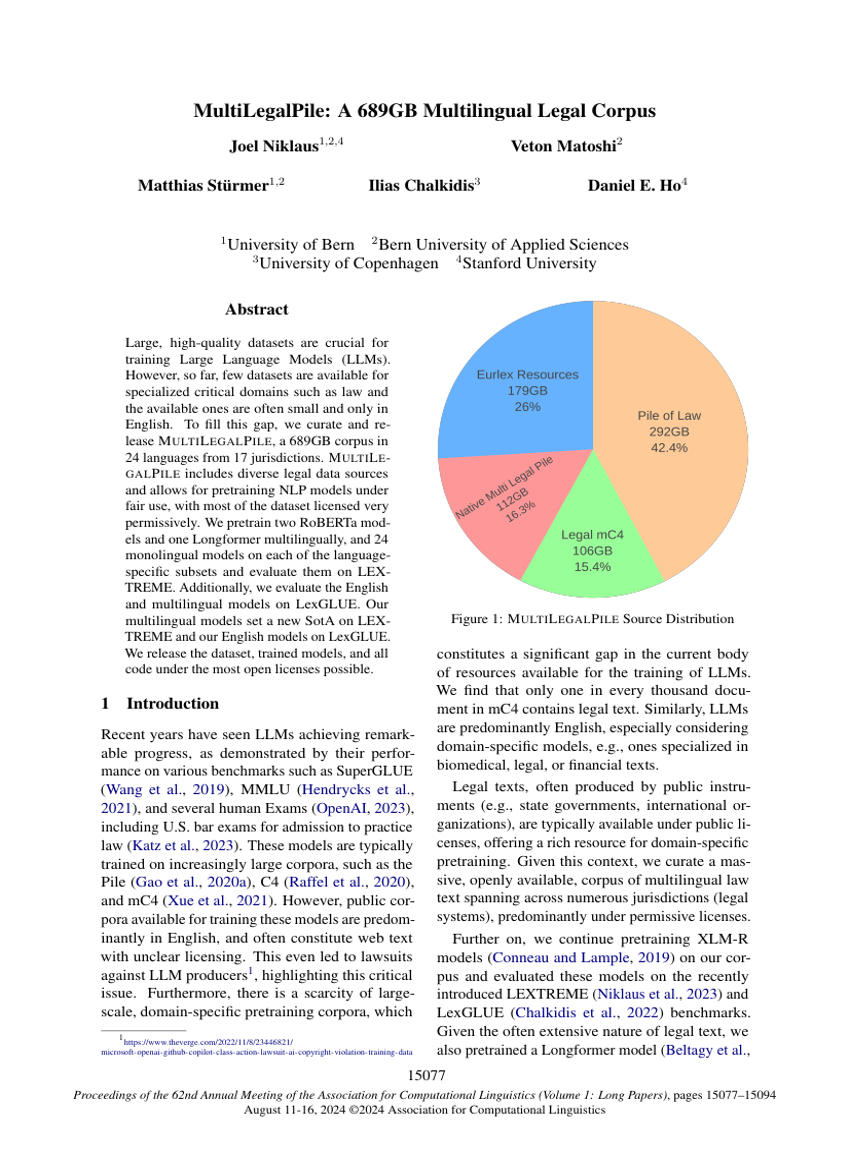
MultiLegalPile: A 689GB Multilingual Legal Corpus
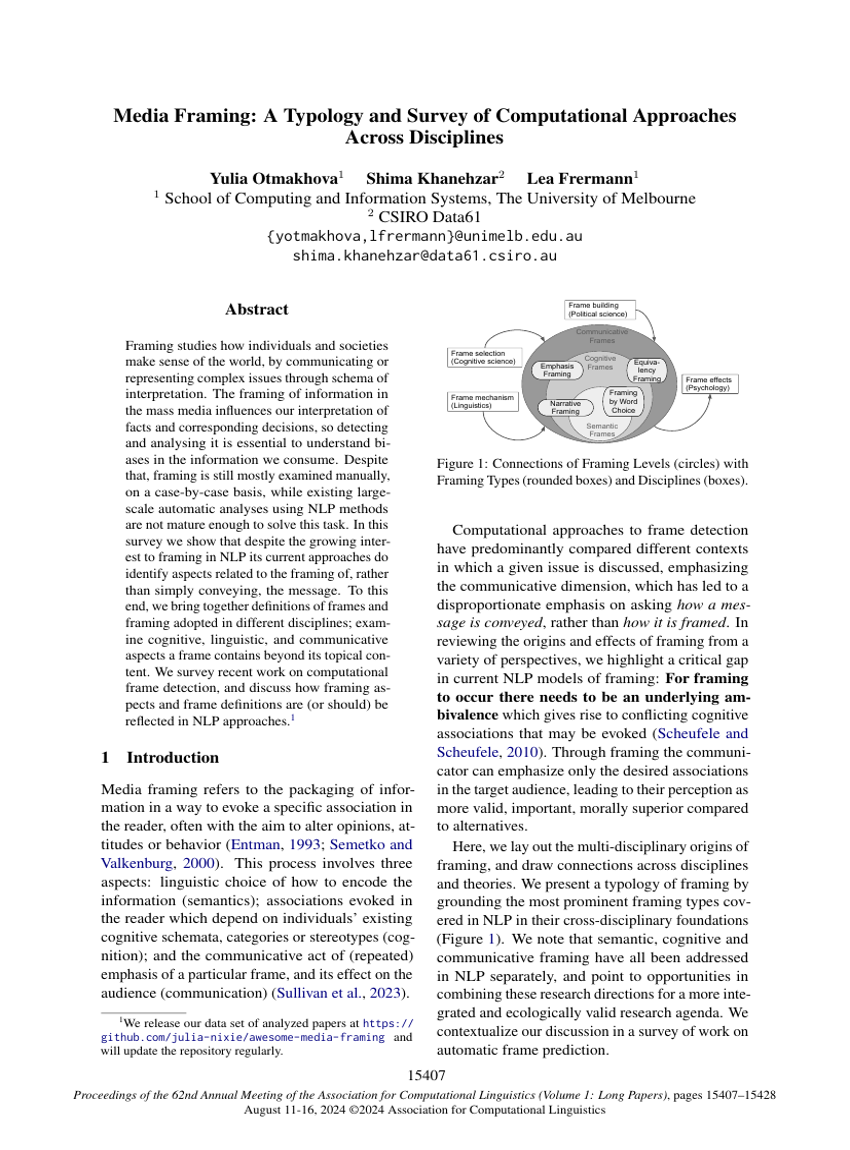
Media Framing: A Typology and Survey of Computational Approaches Across Disciplines
MMToM-QA: Multimodal Theory of Mind Question Answering
MAP's not dead yet: Uncovering true language model modes by conditioning away degeneracy
M4LE⋅ : A Multi-Ability Multi-Range Multi-Task Multi-Domain Long-Context Evaluation Benchmark for Large Language Models
Let's Go Real Talk: Spoken Dialogue Model for Face-to-Face Conversation
Language Complexity and Speech Recognition Accuracy: Orthographic Complexity Hurts, Phonological Complexity Doesn't
L-Eval: Instituting Standardized Evaluation for Long Context Language Models
IRCoder: Intermediate Representations Make Language Models Robust Multilingual Code Generators
Greed is All You Need: An Evaluation of Tokenizer Inference Methods
Getting Serious about Humor: Crafting Humor Datasets with Unfunny Large Language Models
G-DIG: Towards Gradient-based DIverse and hiGh-quality Instruction Data Selection for Machine Translation
Estimating the Level of Dialectness Predicts Interannotator Agreement in Multi-dialect Arabic Datasets
Emulated Disalignment: Safety Alignment for Large Language Models May Backfire!