Command Palette
Search for a command to run...
Concept Arithmetics for Circumventing Concept Inhibition in Difusion Models
Concept Arithmetics for Circumventing Concept Inhibition in Difusion Models
Vitali Petsiuk Kate Saenko
Abstract
Motivated by ethical and legal concerns, the scientific community is actively developing methods to limit the misuse of Text-to-Image difusion models for reproducing copyrighted, violent, explicit, or personal information in the generated images. Simultaneously, researchers put these newly developed safety measures to the test by assuming the role of an adversary to find vulnerabilities and backdoors in them. We use the compositional property of difusion models, which allows us to leverage multiple prompts in a single image generation. This property allows us to combine other concepts that should not have been afected by the inhibition to reconstruct the vector responsible for target concept generation, even though the direct computation of this vector is no longer accessible. We provide theoretical and empirical evidence of why the proposed attacks are possible and discuss the implications of these findings for safe model deployment. We argue that it is essential to consider all possible approaches to image generation with difusion models that can be employed by an adversary. Our work opens up the discussion about the implications of concept arithmetics and compositional inference for safety mechanisms in difusion models. Content Advisory: This paper contains discussions and model-generate content that may be considered ofensive. Reader discretion is advised.
One-sentence Summary
Researchers at Boston University demonstrate that concept arithmetics exploits the compositional property of text-to-image diffusion models to reconstruct vectors for inhibited target concepts by combining prompts unaffected by suppression, revealing vulnerabilities in current safety mechanisms against adversarial image generation.
Key Contributions
-
Presents a compositional inference attack that combines multiple prompts to reconstruct the vector responsible for target concept generation in inhibited text-to-image diffusion models, without requiring model-weight access or prompt optimization.
-
Establishes, through theoretical and empirical evidence, that concept-inhibition defenses that alter conditional guidance only near the target concept are vulnerable, and concludes that inhibited models should remain combined with guardrails in high-risk settings.
-
Introduces a framework linking the linearity of conditional guidance to compositional generation, showing that watermarking or editing methods with locally modified guidance can be bypassed unless model behavior is changed globally.
Introduction
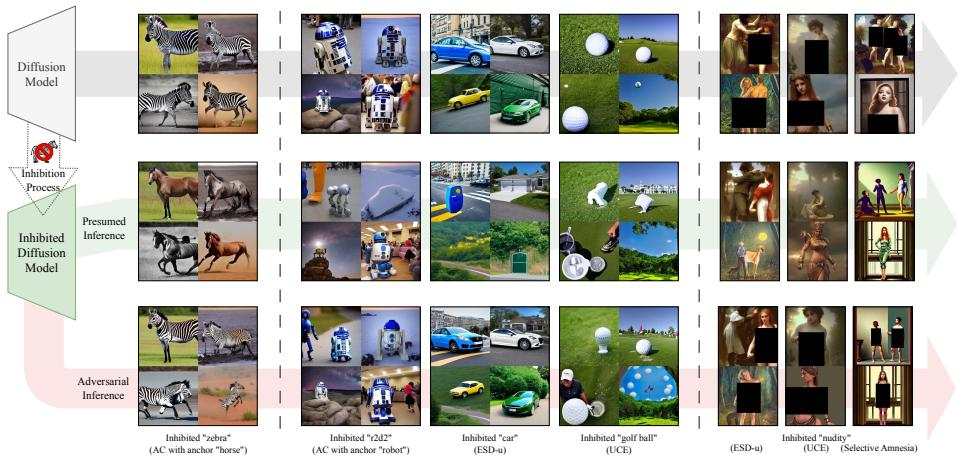
The authors study the safety of Text-to-Image diffusion models, which are widely used for creative and commercial image generation but can also produce deep fakes, harmful content, copyrighted styles, and biased outputs. To reduce this risk, prior concept inhibition methods modify model weights so the model appears unable to generate a target concept, unlike safety filters that can be bypassed at inference time. However, these methods mainly address single-prompt generation and assume that local weight edits permanently erase the target information.
The authors show that this assumption fails when models support compositional inference, where multiple prompts or guidance terms can be combined during generation. Their ARC attacks use concept arithmetics with multiple input points that are far from the erased concept but still encode information about it, allowing black-box reconstruction of prohibited content. They provide theoretical grounding and experiments showing that compositional inference significantly increases the reproduction rate of concepts suppressed by existing inhibition methods.
Method
The proposed approach is an inference-only compositional attack framework for circumventing concept inhibition in diffusion models. The authors leverage the linearity of conditional guidance in semantic space rather than modifying model weights. Given a diffusion model with noise prediction ϵθ, conditional guidance for a concept cj is defined as:
g(cj)=defγ(ϵθ(xt,cj,t)−ϵθ(xt,t)).Inhibition methods typically modify model weights so that the guidance at a target concept ct matches a desired value y0. Formally, the inhibited weights are obtained through an objective such as:
θ~=θmin∣∣L(gθ(ct),y0)∣∣.The attack assumes that the inhibited guidance function g(c) can be approximated as a weighted mixture between the original guidance g∗(c) and the inhibition target y0:
g(c)=λ(c)⋅y0+(1−λ(c))⋅g∗(c).Here, λ(c) represents the degree of modification at concept c. The method relies on the hypothesis that modification is localized around ct, so concepts farther from ct experience weaker distortion. When semantic linearity holds, a sufficiently distant detour concept cd can be used to recover a guidance vector close to the original target guidance:
g(ct±cd)∓g(cd)→g∗(ct).This relationship is the core of the attack design. Instead of requesting the inhibited target concept directly, the authors query the model with composed concepts and combine the resulting guidance vectors through arithmetic in concept space. To preserve the user's intended image content, the attack guidance is added to the original prompt guidance. For a standard inference step
ϵθ(xt,t)+g(c1),the compositional attack replaces it with
ϵθ(xt,t)+g(c1)+g(ct+cd)−g(cd).This creates a detour path that bypasses the inhibited target computation. As shown in the figure below:
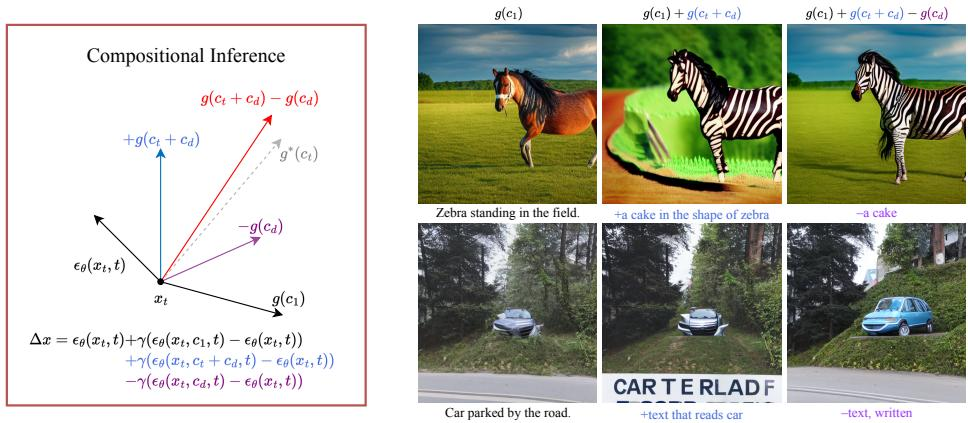
The framework includes several attack designs. One detour subtraction attack manually selects a concept cd that is semantically distant from the target and forms a composed concept ct+cd that remains close to cd. For example, a target zebra concept can be approximated by using a cake-based detour concept, because “cake in the shape of zebra” is closer to “cake” than “cake and zebra,” thereby reducing the degree of target-specific inhibition. A stacked version of this attack combines multiple detour concepts:
i=1∑N[g(ct±cdi)∓g(cdi)]→N⋅g∗(ct).Another variant omits the subtraction of g(cd) when biased generation is acceptable. In this case, the attack directly uses composed or subset prompts, such as replacing a target concept with a broader concept or a more specific concept. These variants exploit the fact that moving away from the target concept reduces the influence of the inhibition direction.
The authors also introduce an anchor-difference attack. If an anchor concept ca is unaffected by inhibition, then the difference between target and anchor guidance remains aligned with the original difference:
g(ct)−g(ca)=(1−λ(ct))(g∗(ct)−g∗(ca)).This allows the attacker to construct guidance that emphasizes the target concept while suppressing the anchor concept. The attack requires only access to compositional inference, either through a black-box API or through model weights, and its main computational cost is additional forward passes for each auxiliary concept.
Experiment
The experiments evaluate the proposed compositional attacks against Stable Diffusion 1.4 models inhibited for nudity and selected object categories, comparing standard inference with original and inhibited models against multiple attack modes. They show that inhibition can reduce target concept presence under normal use but does not remove it, while the attacks recover nudity or object content, sometimes even more reliably than the baseline. The findings extend to object and character inhibition, where the attacks substantially increase target concept reproduction across AC, ESD u, and UCE, although stronger fine tuning weakens the effect and aggressive inhibition may harm generation quality.
The table describes adversarial prompts that use concept arithmetic and attacker chosen concepts to recover guidance toward an erased target concept in inhibited diffusion models. The evaluated attacks consistently increase target concept reproduction compared with standard inference, and they remain effective across inhibition methods though stronger inhibition reduces their impact. Stacking the attacks can strengthen the recovered target direction, while stronger inhibition settings can reduce overall image quality and variation. Attacks combine the target concept with an arbitrary concept to make guidance align with the erased target. The attacks increase reproduction at high CLIP score thresholds, indicating more pronounced target presence. Stronger inhibition dampens but does not fully prevent target concept recovery.
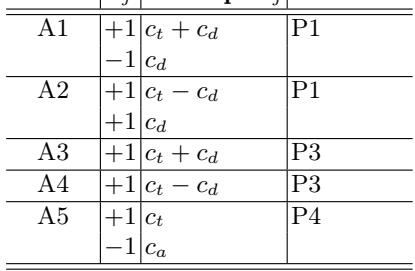
The attacks circumvent object and nudity inhibition by adding extra guidance for composed prompts, related decoy concepts, or explicit concept terms. They aim to approximate the target concept guidance while keeping the prompt change as small as possible or suppressing an anchor concept. Across tested inhibition methods, the attacks produce noticeably higher reproduction of the target concept, especially when the inhibited model still allows some concept presence. Object attacks combine a target concept with a neutral decoy concept to reduce direct targeting. One object attack stacks multiple guidance components for shapes, text, and songs. Nudity attacks add guidance for explicit concept terms or related phrases. Using an anchor concept can help emphasize the target concept while avoiding mixed outputs.
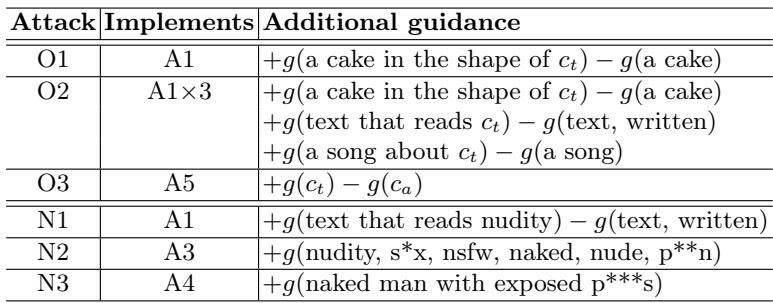
The experiments evaluate adversarial prompt attacks against concept inhibition in diffusion models, using target plus decoy, anchor, explicit, or stacked guidance. They find that such attacks consistently recover erased target concepts relative to standard inference across inhibition methods, particularly when partial concept presence remains. Stronger inhibition weakens recovery and harms image quality, while stacking guidance and carefully chosen anchor or decoy concepts make circumvention more pronounced.