Command Palette
Search for a command to run...
GENERALIZATION IN DIFFUSION MODELS ARISES FROM GEOMETRY-ADAPTIVE HARMONIC REPRESENTATIONS
GENERALIZATION IN DIFFUSION MODELS ARISES FROM GEOMETRY-ADAPTIVE HARMONIC REPRESENTATIONS
Zahra Kadkhodaie Florentin Guth Eero P. Simoncelli Stéphane Mallat
Abstract
Deep neural networks (DNNs) trained for image denoising are able to generate highquality samples with score-based reverse diffusion algorithms. These impressive capabilities seem to imply an escape from the curse of dimensionality, but recent reports of memorization of the training set raise the question of whether these networks are learning the "true" continuous density of the data. Here, we show that two DNNs trained on non-overlapping subsets of a dataset learn nearly the same score function, and thus the same density, when the number of training images is large enough. In this regime of strong generalization, diffusion-generated images are distinct from the training set, and are of high visual quality, suggesting that the inductive biases of the DNNs are well-aligned with the data density. We analyze the learned denoising functions and show that the inductive biases give rise to a shrinkage operation in a basis adapted to the underlying image. Examination of these bases reveals oscillating harmonic structures along contours and in homogeneous regions. We demonstrate that trained denoisers are inductively biased towards these geometry-adaptive harmonic bases since they arise not only when the network is trained on photographic images, but also when it is trained on image classes supported on low-dimensional manifolds for which the harmonic basis is suboptimal. Finally, we show that when trained on regular image classes for which the optimal basis is known to be geometry-adaptive and harmonic, the denoising performance of the networks is near-optimal.
One-sentence Summary
Researchers at NYU, Flatiron Institute, and Collège de France demonstrate that generalization in diffusion models arises because DNN denoisers learn geometry-adaptive harmonic bases, showing that networks trained on disjoint subsets converge to the same score function and that this inductive bias yields near-optimal denoising on regular image classes.
Key Contributions
-
The paper shows that diffusion-model training exhibits a phase transition: two DNNs trained on large, non-overlapping subsets learn nearly the same score function, and hence nearly the same density, while diffusion samples remain distinct from the training set and are of high visual quality.
-
Analysis of trained denoisers reveals an inductive bias that performs shrinkage of noisy coefficients in a geometry-adaptive harmonic basis adapted to image contours and homogeneous regions. This basis appears for photographic images and also for image classes supported on low-dimensional manifolds, indicating that it is intrinsic to the learned denoisers.
-
Evaluation on image classes with known optimal bases demonstrates near-optimal denoising when the optimal basis is geometry-adaptive and harmonic, such as C^alpha images with bandlet-like bases, while manifold-supported classes show suboptimal residual noise along additional GAHB components. This contrast supports the hypothesis that the GAHB inductive bias of DNN denoisers explains both strong performance and limited performance.
Introduction
Diffusion generative models use deep neural network denoisers to estimate the score of noisy image distributions and produce new samples through reverse diffusion, making them central to high-quality image generation. A key challenge is that learning a continuous density in a high-dimensional space is difficult, and prior results show that when training sets are small relative to model capacity, these models memorize training samples rather than generalizing. The authors show that with sufficiently large datasets, DNN denoisers converge to nearly the same denoising function on non-overlapping training sets and generate nearly identical images, providing direct evidence of strong generalization. They also leverage the link between denoising and density estimation to reveal a geometry-adaptive harmonic basis inductive bias, in which the denoisers perform shrinkage of noisy coefficients in bases adapted to image geometry.
Method
The authors leverage a score-based generative pipeline in which the model does not approximate the clean image density directly. Instead, it learns the score of noise corrupted image distributions. Starting from an unknown clean density p(x), the method observes noisy images
y=x+z,z∼N(0,σ2Id),so that the noisy density is a Gaussian convolution of the clean density,
pσ(y)=∫p(y∣x)p(x)dx=∫gσ(y−x)p(x)dx.The family {pσ} forms a scale space representation of p(x), analogous to the evolution of a diffusion process. The learned object is a score model sθ(y)≈∇logpσ(y) at different noise levels. These scores define a reverse diffusion process and therefore an induced model pθ(x) for the clean data distribution. The quality of the generative model is controlled by the integrated score error,
DKL(p(x)∥pθ(x))≤∫0∞Ey[∥∇logpσ(y)−sθ(y)∥2]σdσ.To learn the score, the method uses the identity
∇logpσ(y)=σ2Ex[x∣y]−y.This makes score learning equivalent to learning a denoiser fθ(y) that approximates the posterior mean Ex[x∣y]. The training objective is the mean squared error
MSE(fθ,σ2)=Ex,y[∥x−fθ(y)∥2],and the estimated score is recovered from the denoiser output as
sθ(y)=σ2fθ(y)−y.The resulting density approximation satisfies the bound
DKL(p(x)∥pθ(x))≤∫0∞(MSE(fθ,σ2)−MSE(f⋆,σ2))σ−3dσ,where f⋆(y)=Ex[x∣y] is the optimal denoiser. This shows that generative modeling accuracy is governed by denoising optimality across all noise levels.
The training workflow is analyzed by comparing denoising performance on training and test samples as the training set size grows. The figure below shows output PSNR against input PSNR for multiple training set sizes. For very small datasets, the model memorizes the training samples, giving high train performance but poor test performance. As the dataset size increases, test performance improves and eventually matches train performance, indicating that the denoiser has entered a generalization regime rather than a memorization regime.
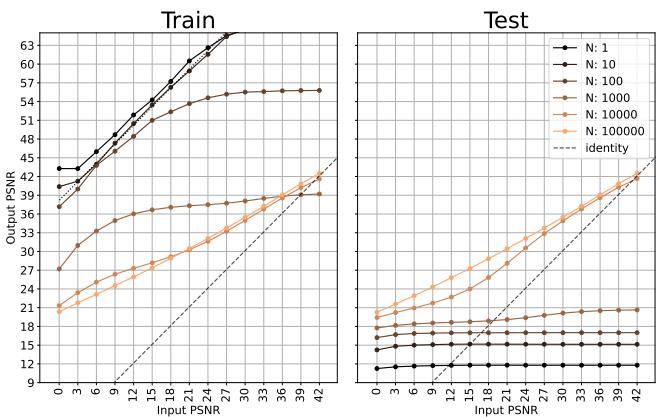
This generalization behavior is central to the framework because high dimensional density estimation is otherwise impossible without strong inductive biases. The learned denoiser, for example a UNet, acts as the core generative module. Its architecture and optimization procedure constrain the score estimates it can represent. When these constraints align with the structure of images, the denoiser learns scores that generalize well and produce diverse generated samples. When they do not, the model may either memorize limited data or introduce substantial model bias in the learned density.
The method then examines the internal structure of the denoiser through a local Jacobian analysis. Given a denoising estimator x^=f(y), the authors study ∇f(y). If the network has no additive bias parameters, the mapping is piecewise linear, and the denoiser can be expressed through the eigendecomposition of its Jacobian as
f(y)=∇f(y)y=k∑λk(y)⟨y,ek(y)⟩ek(y).Here λk(y) are eigenvalues and ek(y) are eigenvectors. This representation reveals the central mechanism of the method: denoising is interpreted as shrinkage in an adaptive basis. The eigenvectors define a local coordinate system, while the eigenvalues determine how much of each local component is retained or suppressed. Both the basis and the shrinkage factors depend on the noisy image y.
The MSE objective naturally enforces this shrinkage behavior. Using Stein’s unbiased risk estimate, the denoising error can be written as
MSE(f,σ2)=Ey[2σ2tr∇f(y)+∥y−f(y)∥2−σ2d].Minimizing MSE requires a tradeoff between the rank of the Jacobian, measured by the sum of eigenvalues, and the residual denoising error. The denoiser therefore behaves locally like a soft projection onto a subspace whose dimensionality corresponds to the Jacobian rank. For the optimal denoiser, the Jacobian has a direct probabilistic interpretation:
∇f⋆(y)=Id+σ2∇2logpσ(y)=σ−2Cov[x∣y].Thus the optimal adaptive basis is tied to the posterior covariance of the clean image given the noisy observation. The optimal MSE satisfies
MSE(f⋆,σ2)=σ2Ey[k∑λk⋆(y)],so a low denoising error corresponds to an approximately low rank Jacobian with many small eigenvalues.
The authors also connect this local basis viewpoint to classical sparse denoising. In a fixed orthonormal basis ek, an oracle shrinkage rule is
λk(x)=⟨x,ek⟩2+σ2⟨x,ek⟩2.This acts as a soft threshold: coefficients whose signal energy dominates the noise are preserved, while weak coefficients are suppressed. If the coefficients of x decay as k−(α+1), the resulting denoising error scales as σ2α/(α+1), which corresponds to a PSNR slope of α/(α+1). The analysis extends this idea to adaptive bases selected from a dictionary, where adaptivity can yield sparser representations and better asymptotic denoising rates.
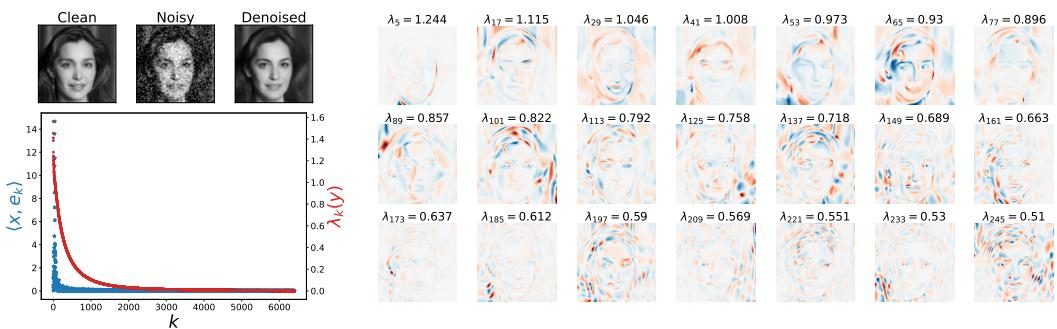
The empirical design analysis studies whether learned DNN denoisers exhibit such adaptive sparse behavior. For a denoiser trained on face images, the Jacobian eigenvectors contain oscillating patterns that align with image contours and smooth regions. The eigenvalues decay rapidly, and the clean image coefficients in this basis are sparse. This indicates that the denoiser uses a geometry adaptive harmonic basis, a local basis that adapts to both shape structure and regional smoothness.
As shown in the figure below, the top panel compares clean, noisy, and denoised images, while the lower panel plots the decay of shrinkage factors and signal coefficients. The basis vectors shown on the right display harmonic like oscillations along facial contours and within smoother regions. Their frequencies increase as the shrinkage factors decrease.
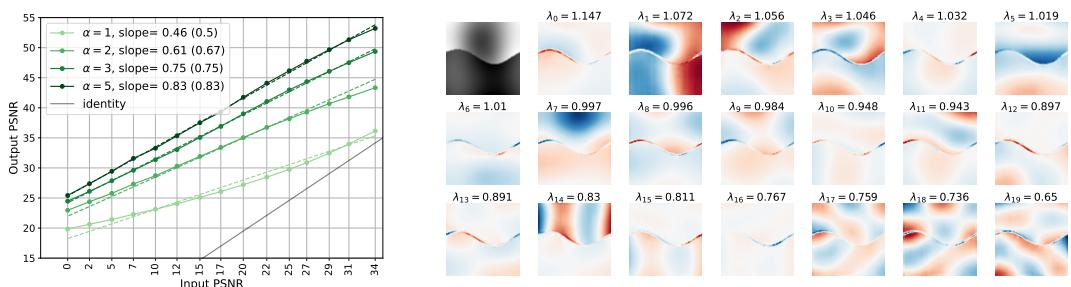
To evaluate whether this basis structure reflects a favorable inductive bias, the authors test geometric image classes for which optimal sparse representations are known. In the geometric Cα setting, images contain regular contours on regular backgrounds, with regularity controlled by α. The optimal sparse representation for this class is obtained with bandlet bases, where coefficient decay leads to the asymptotic PSNR slope α/(α+1). When UNet denoisers are trained on such synthetic data, their PSNR curves approach the theoretical optimal slopes for different values of α. The learned eigenvectors resemble bandlets, with harmonic structure along regions and across boundaries, but with a more flexible geometry.
The figure below shows PSNR curves for several regularity levels and the corresponding leading eigenvectors for a Cα image. The empirical slopes track the theoretical values, and the basis vectors display region based harmonics with increasing frequency.
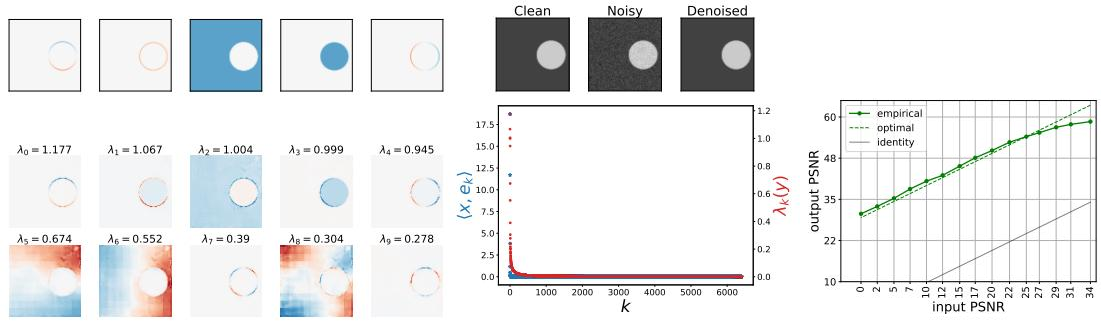
The authors also examine cases where the data distribution lies on a low-dimensional manifold, such as disk images with variations in position, size, and intensity. In the small noise limit, the optimal denoiser should project onto a local tangent space, producing only a few non-negligible eigenvalues and a PSNR slope of 1.0. The trained denoiser does recover some tangent directions, but it also generates additional nonzero eigenvalues whose eigenvectors have geometry adaptive harmonic structure. These extra components increase the effective rank of the Jacobian and lead to a suboptimal PSNR slope below the theoretical optimum.
The figure below presents clean, noisy, and denoised disk images, the decay of shrinkage factors and coefficients, the first eigenvectors of the learned basis, and the denoising performance curve. The first learned basis vectors correspond closely to the tangent space of the disk manifold, while later vectors follow contour and background oscillations rather than purely low-dimensional manifold directions.
Experiment
Experiments comparing denoisers trained on small to large image subsets validate a transition from memorization to generalization: small training sets yield training-data-specific samples and poor test performance, whereas larger sets produce matched training and test behavior and near-identical generations across disjoint subsets, indicating convergence to a common score function. Additional experiments analyze learned denoising bases and test them on geometrically structured synthetic image classes. They show that DNN denoisers learn contour-aligned oscillatory bases that match the regularity assumptions of natural images, achieving near-optimal behavior on geometrically regular synthetic data, but becoming suboptimal when the data structure conflicts with these harmonic inductive biases.