Command Palette
Search for a command to run...
PhysLoop: Harnessing LLMs’ Physics Awareness for Self-Improving Video Generation Models
PhysLoop: Harnessing LLMs’ Physics Awareness for Self-Improving Video Generation Models
Abstract
Video generation models produce visually realistic videos but still struggle with physical dynamics and causal consistency. Learning from generated videos requires fine-grained physical supervision, yet reliable quality judgments, correction pairs, and controlled variations are dificult to obtain. Large language models (LLMs) possess physical knowledge, but struggle to reliably guide video generation models in producing their training videos. We present PhysLoop, a unified harness designed to support physically grounded self-improvement in video generation models. The harness guides and constrains LLMs throughout video generation, selection, and correction, distilling their physical knowledge into physically consistent videos. The framework supports controllable training-data construction and inference-time video repair. By identifying and correcting failures, PhysLoop marks a key milestone toward recursive self-improvement (RSI) in video generation models with limited human intervention. We release 100K videos spanning diverse, realistic indoor and outdoor scenes, along with generation tools and two evaluation datasets: PhysLoop-Gen and PhysLoop-Repair. We evaluate controllable generation and localized repair on these datasets, respectively, and assess physical behavior on the external Physics-IQ Verified benchmark.
One-sentence Summary
Researchers from Peking University, ByteDance Seed, UC Santa Barbara, MIT, et al. propose PhysLoop, a unified harness that guides and constrains LLMs throughout video generation, selection, and correction to distill physical knowledge into physically consistent videos, enabling controllable training-data construction, inference-time video repair, and recursive self-improvement, and they release 100K diverse indoor and outdoor videos along with the PhysLoop-Gen and PhysLoop-Repair evaluation datasets while assessing physical behavior on the external Physics-IQ Verified benchmark.
Key Contributions
- PhysLoop is a unified harness that guides and constrains LLMs throughout video generation, selection, and correction, distilling their physical knowledge into physically consistent videos and supporting controllable training-data construction and inference-time video repair.
- PhysLoop provides a shared workflow for failure identification, correction, and verification, connecting diagnosis to simulation-grounded correction. It evaluates both the resolution of the target physical error and the preservation of unaffected content.
- The release includes 100K videos spanning diverse, realistic indoor and outdoor scenes, generation tools, and two evaluation datasets, PhysLoop-Gen and PhysLoop-Repair. Evaluations are reported for controllable generation, localized repair, and physical behavior on the external Physics-IQ Verified benchmark.
Introduction
Video generation models can produce temporally coherent and viewpoint-consistent scenes, but visual realism does not guarantee physical or causal consistency; objects may appear or disappear, contact may have no plausible response, and motion can conflict with gravity, inertia, or contact forces. Collecting real-world videos that systematically vary physical conditions is difficult to scale while preserving controlled setups and reliable annotations, and fine-tuning data for specific physical failures is similarly hard to obtain. Current self-improvement pipelines also struggle because general-purpose multimodal evaluators cannot reliably judge physical validity, so generating more videos does not by itself produce dependable learning signals. The authors introduce PhysLoop, a unified harness that guides LLMs to apply their existing physical knowledge inside a simulator, using physical assessment and iterative correction to construct training data and repair generated videos. They release 100K videos covering common physical phenomena, the PhysLoop-Gen and PhysLoop-Repair evaluation datasets, and generation tools, and they evaluate controllable generation, localized repair, and physical behavior.
Dataset
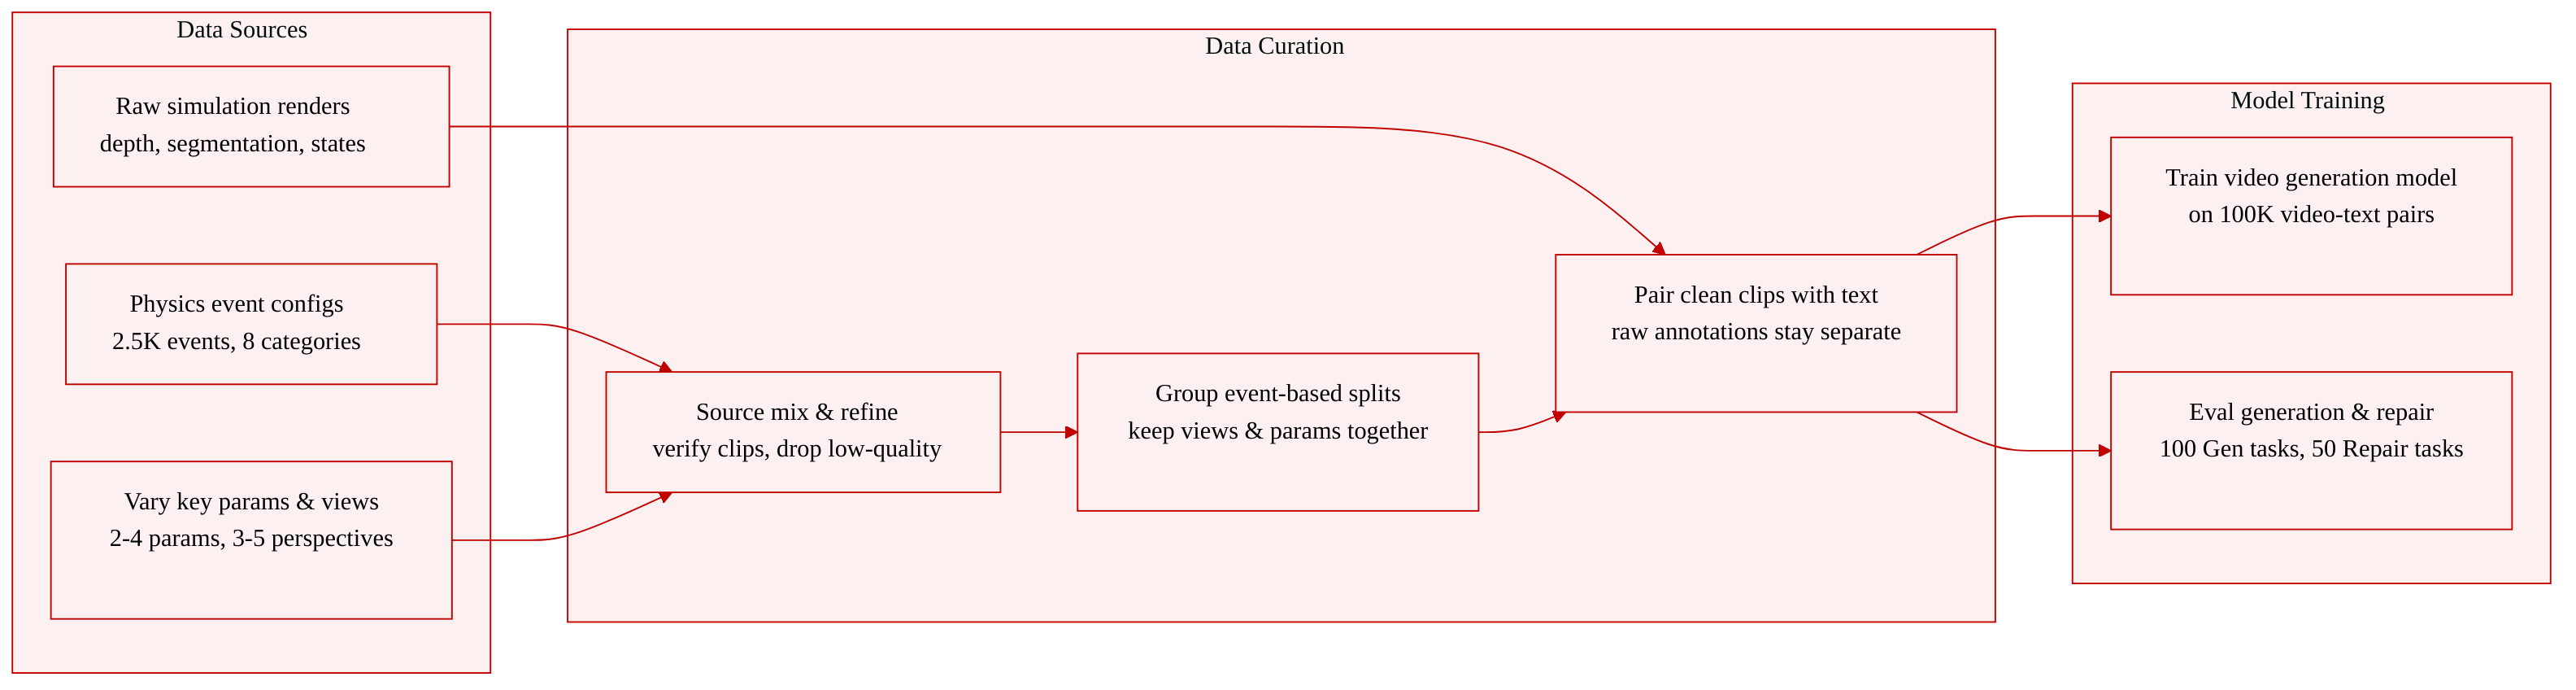
Dataset overview
The authors describe a physics-grounded data pipeline and three resources:
- PhysLoop-100K: a training set with video-text pairs and simulation annotations.
- PhysLoop-Gen: an evaluation set for generation.
- PhysLoop-Repair: an evaluation set for physical-error repair.
PhysLoop-100K
- Scale: 100K accepted videos from 2.5K distinct physical events.
- Structure: each event has about 40 videos on average, captured from 3 to 5 perspectives, with 2 to 4 key physical parameters set to multiple levels.
- Covered categories: kinematics, dynamics, rigid-body dynamics, magnetism, fluid mechanics, flexible and elastic materials, fragmentation, and fracture.
- Source and variation: the system automatically varies physical parameters such as mass and initial velocity, along with assets, scenes, lighting, and camera views. It includes all valid combinations defined for each case.
- Annotations: refined video-text pairs, generating configurations, original simulation videos, depth maps, instance segmentation maps, and object states. Depth, segmentation, and object-state annotations are not pixel-aligned with refined videos.
- Split protocol: groups each source event with its camera views and parameter variants.
PhysLoop-Gen
- Size: 100 generation tasks.
- Input: each instance has a text request, and some cases also include image references.
- Coverage: rigid-body, cloth, and fluid phenomena, from simple bouncing or sliding to coupled interactions and multistage mechanical chains.
- Difficulty definition: based on input properties such as interaction count, event ordering, and observable conditions, not on a specific model’s performance.
- Use: supports comparison between agentic frameworks such as PhysLoop and direct video generation models.
PhysLoop-Repair
- Size: 50 repair tasks.
- Source videos: generated by different video models, including Seedance series, MiniMax H3, and Gemini Omni 1.1 Flash.
- Input: a source video with a physical error and an optional repair request.
- Annotations: include error description and temporal interval. The primary evaluation protocol provides only the source video and request, while error and interval annotations remain evaluation-only.
- Inclusion criteria: requires an observable error, a specified correction, and source content to preserve.
- Evaluation checks: target-error removal, connection to surrounding events, and preservation of unrelated content.
Processing and usage
- The authors use an agent to expose task-specific parameters in generated scene configurations, such as release height and initial velocity.
- Selected parameters are varied while other conditions are held fixed. Scene and camera settings can be edited, and multiple views can be rendered from the same simulation.
- Task descriptions and visual references specify the appearance to be produced. Videos that pass final verification are paired with their task descriptions as training examples.
- Each sample retains its generating configuration for inspection, expansion, and regeneration.
- Downstream training uses the video-text pairs to update the video generation model.
- Raw simulation renders retain synchronized depth, segmentation, and object-state annotations. Because refinement may alter geometry or object positions, these annotations are kept separate from the refined video-text pairs and are not treated as pixel-aligned supervision.
- The provided text does not specify a cropping strategy or training mixture ratios.
Method
The authors present PhysLoop, a harness that guides large language models to identify physical errors and generate physically consistent videos through simulators and supporting tools. The system processes a text request, optionally accompanied by image or video references, to produce a generated or repaired video alongside its task specification and execution record.
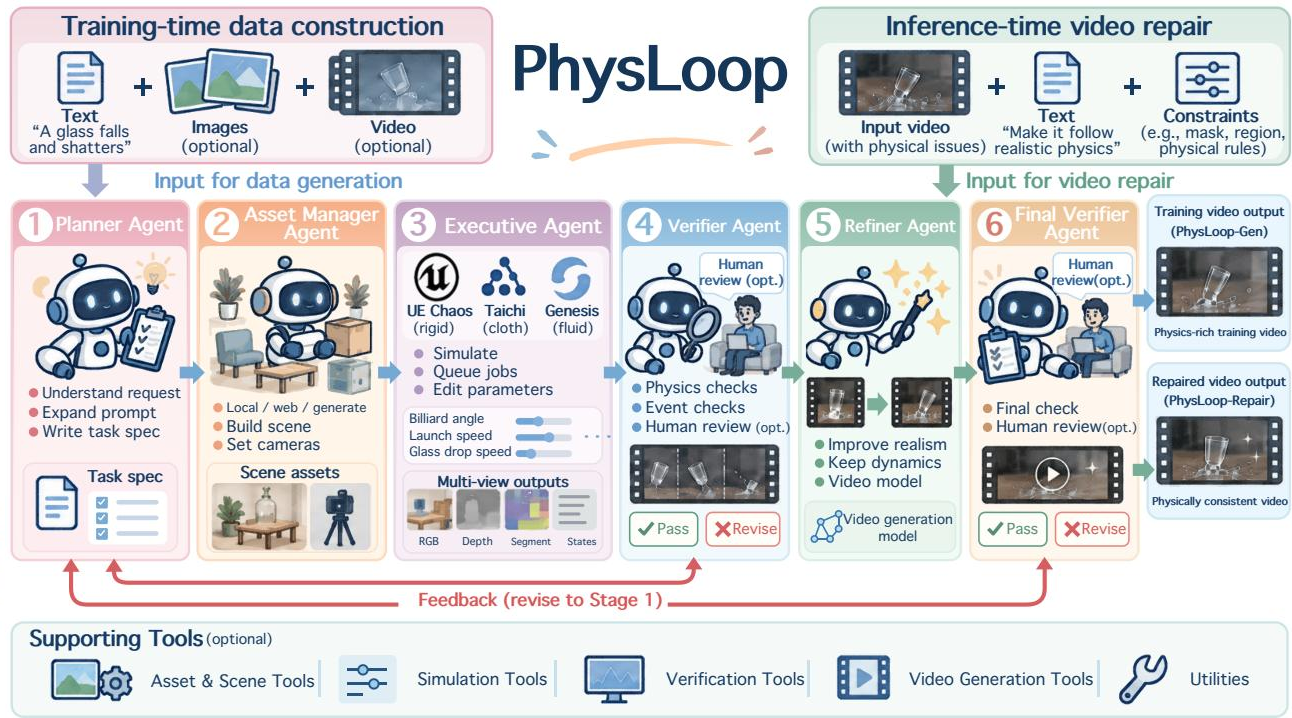
The workflow is orchestrated by a code agent that leverages a suite of specialized modules. First, a Planner Agent expands the user request into a detailed task specification, recording the target event, construction assumptions, and verification conditions. The Asset Manager Agent then retrieves or generates 3D assets that meet visual and interaction requirements, checking asset scale and collision geometry against the target interaction. Visual meshes and physical representations are handled separately to pair detailed appearance with appropriate collision proxies. The agent writes a scene program combining retrieved assets and procedural geometry, and renders low-resolution preview frames to inspect placement before full simulation.
Next, the Executive Agent drives the physics execution. The harness integrates Unreal Engine as the primary simulator, with Taichi and Genesis providing additional support. Simulator adapters translate scene configurations into the inputs of each simulator and transfer the resulting motion with aligned coordinates and timing. Alongside RGB, the system captures depth, instance segmentation, and object states.
Before appearance refinement, a Verifier Agent compares the simulation states and visual observations with the predefined event requirements. If checks fail, the verifier returns a failure description with supporting evidence, prompting the agent to revise the configuration. Once simulation checks pass, a Refiner Agent adapts the rendered scene to the requested visual appearance using a video generation model, taking the verified simulation video as a motion reference. A Final Verifier Agent then evaluates whether the visible behavior preserves the target event and physical relationships after refinement. If either verification stage fails, the system iterates until all checks pass or the resource budget is exhausted.
For video diagnosis and repair, the agent identifies physical or event-level errors in an existing video and specifies the segment to replace. The repair process replaces only the selected interval [a,b) of a source video V with T frames. The corrected segment V^a:b matches the source resolution and frame rate, and the final output is assembled as:
V′=V0:a∥V^a:b∥Vb:Twhere ∥ denotes concatenation. The verifier evaluates the replacement within the complete video to ensure consistency with preceding and following frames, guiding further revision if necessary.
Experiment
The evaluation covers controllable video generation on PhysLoop-Gen, diagnosis and repair on PhysLoop-Repair, and continuation matching on Physics-IQ Verified, comparing PhysLoop configurations with standalone generators and alternative agent backbones or refiners. Human and automatic metrics assess physical plausibility, causal consistency, visual quality, and task success. PhysLoop improves generation and repair success substantially, with higher human ratings for physical and causal consistency, although its visual realism can trail standalone generators. Case analysis shows that plausible local motion is insufficient because baseline models often fail on event outcomes and scene consistency, while scene construction, simulation, verification, and appearance refinement serve complementary roles.
PhysLoop improves generation and repair success over standalone video generators, with especially large gains in repair. Adding refinement raises task success and human-rated visual realism, while the full configuration leads human ratings for physical plausibility and causal consistency. Physics-IQ rankings diverge from task success rankings, showing that refiner and backbone choices affect different aspects of performance. PhysLoop converts repair from a weak area for standalone generators into a clear strength. Refinement improves generation and repair success and visual realism, while slightly improving physical plausibility and causal consistency. Human ratings favor the full PhysLoop configuration, but Physics-IQ performance depends on the refiner and backbone combination.
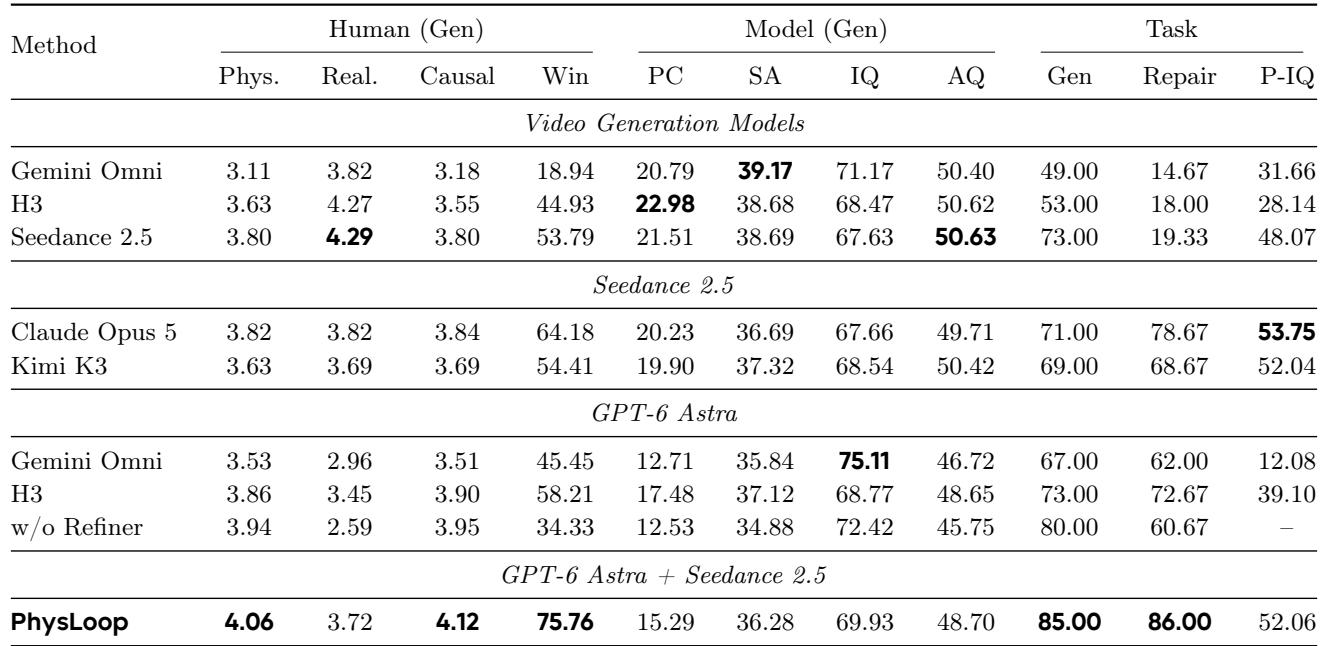
The experiments compare PhysLoop with standalone video generators on generation and repair tasks, measuring task success, human ratings of visual realism, physical plausibility, and causal consistency, along with Physics-IQ. PhysLoop substantially improves generation and especially repair performance, turning repair into a strength, while refinement further raises task success and visual realism and yields modest gains in physical plausibility and causal consistency. Human ratings favor the full PhysLoop configuration, but Physics-IQ rankings diverge from task success rankings, indicating that refiner and backbone choices affect different aspects of performance.