HyperAI
Command Palette
Search for a command to run...
Top Conference Papers
Award-winning papers from top conferences such as CVPR, NeurIPS, ICML and ACL
papers
Effective Approaches to Attention-based Neural Machine Translation
Automatic Labeling of Semantic Roles
Pre³: Enabling Deterministic Pushdown Automata for Faster Structured LLM Generation
I0T: Embedding Standardization Method Towards Zero Modality Gap
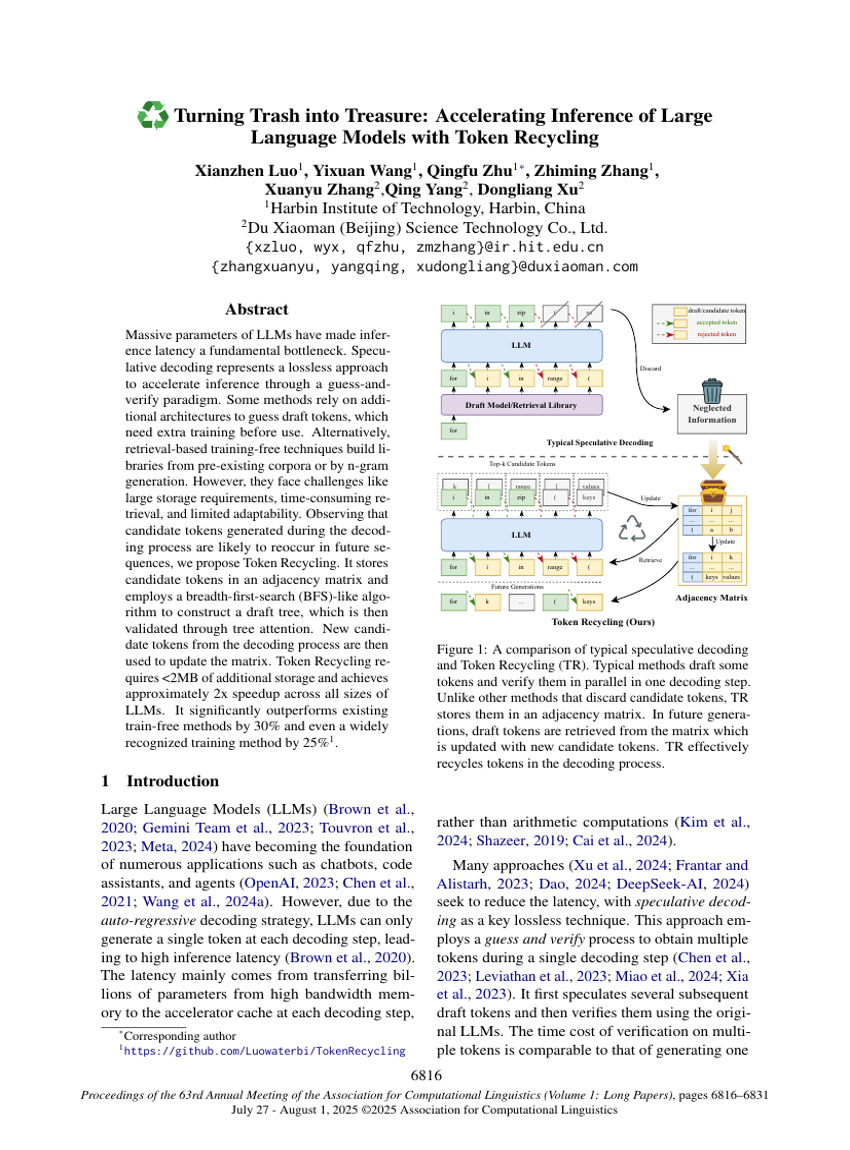
Turning Trash into Treasure: Accelerating Inference of Large Language Models with Token Recycling
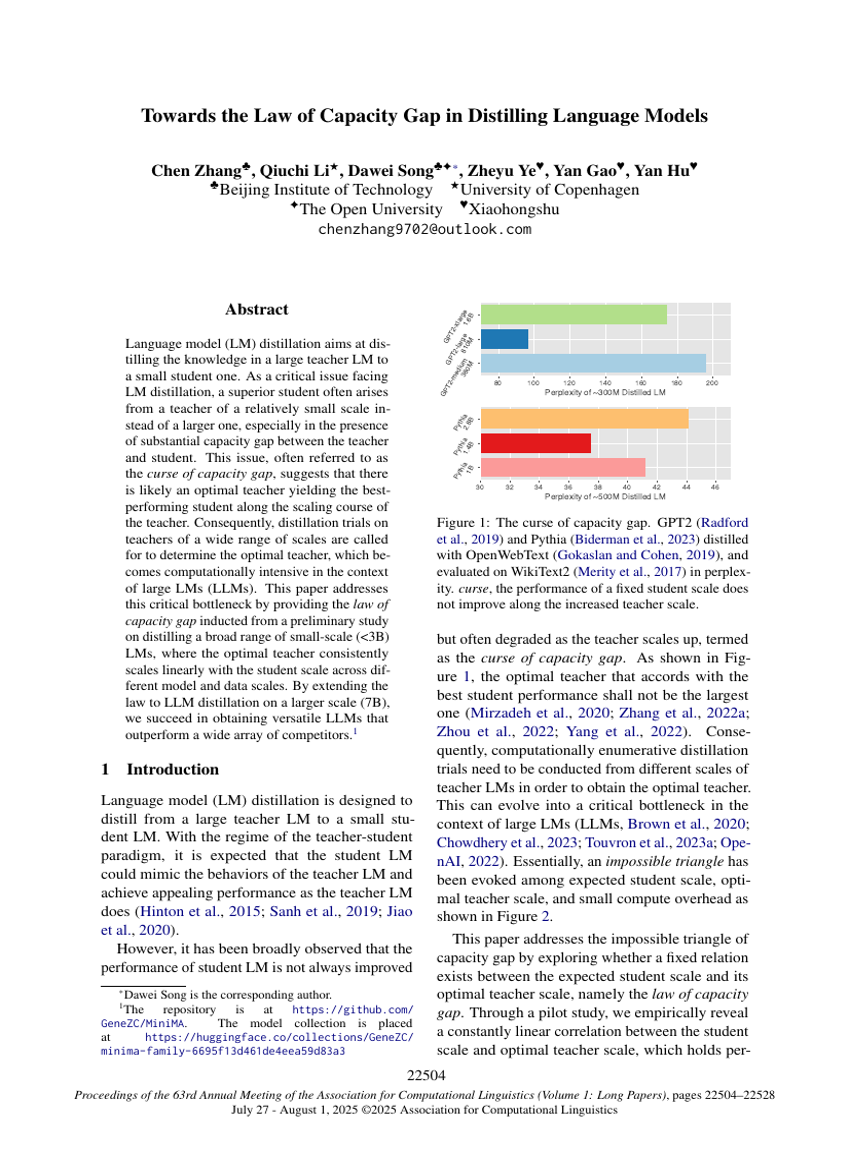
Towards the Law of Capacity Gap in Distilling Language Models
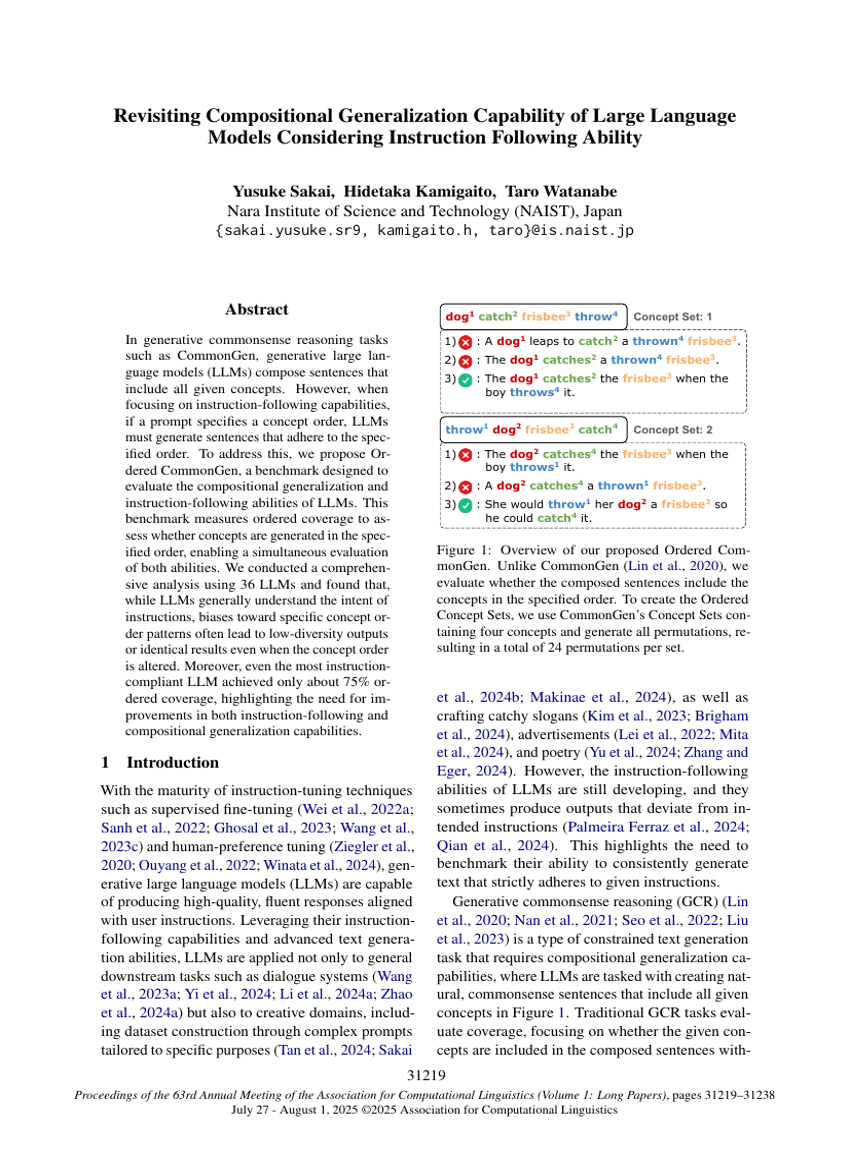
Revisiting Compositional Generalization Capability of Large Language Models Considering Instruction Following Ability
Rethinking the Role of Prompting Strategies in LLM Test-Time Scaling: A Perspective of Probability Theory
Past Meets Present: Creating Historical Analogy with Large Language Models
MiniLongBench: The Low-cost Long Context Understanding Benchmark for Large Language Models
Mapping 1,000+ Language Models via the Log-Likelihood Vector
Llama See, Llama Do: A Mechanistic Perspective on Contextual Entrainment and Distraction in LLMs
LATIM: Measuring Latent Token-to-Token Interactions in Mamba Models
IndicSynth: A Large-Scale Multilingual Synthetic Speech Dataset for Low-Resource Indian Languages
HATEDAY: Insights from a Global Hate Speech Dataset Representative of a Day on Twitter
HALOGEN : Fantastic LLM Hallucinations and Where to Find Them
From REAL to SYNTHETIC: Synthesizing Millions of Diversified and Complicated User Instructions with Attributed Grounding
Capability Salience Vector: Fine-grained Alignment of Loss and Capabilities for Downstream Task Scaling Law
Bridging the Language Gaps in Large Language Models with Inference-Time Cross-Lingual Intervention
Beyond N-Grams: Rethinking Evaluation Metrics and Strategies for Multilingual Abstractive Summarization
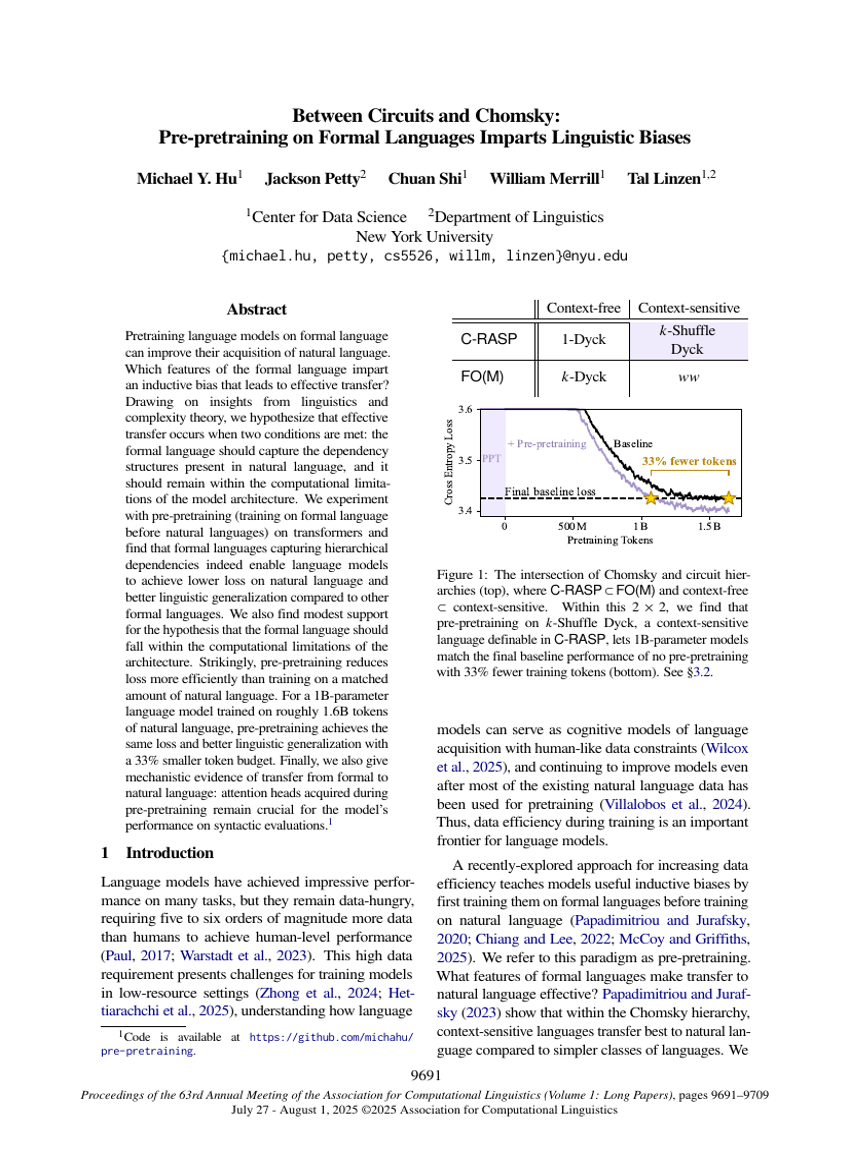
Between Circuits and Chomsky: Pre-pretraining on Formal Languages Imparts Linguistic Biases
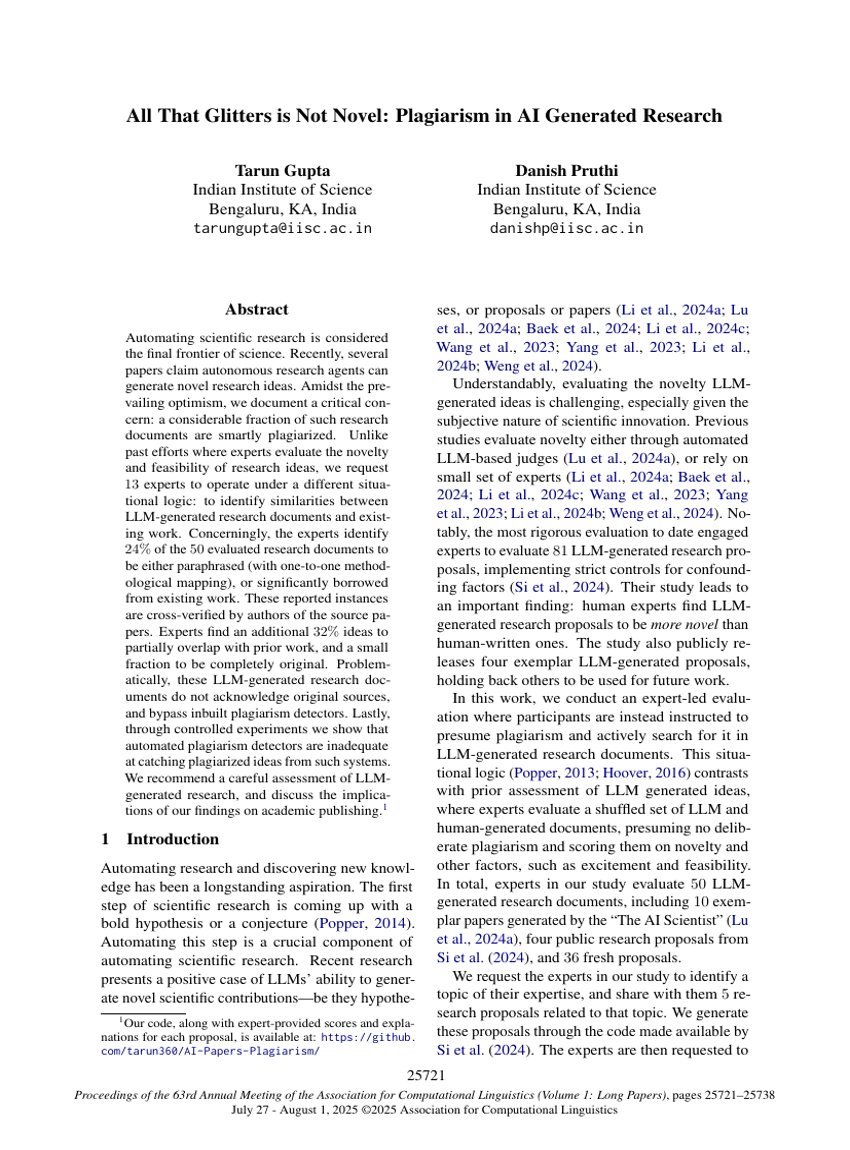
All That Glitters is Not Novel: Plagiarism in AI Generated Research
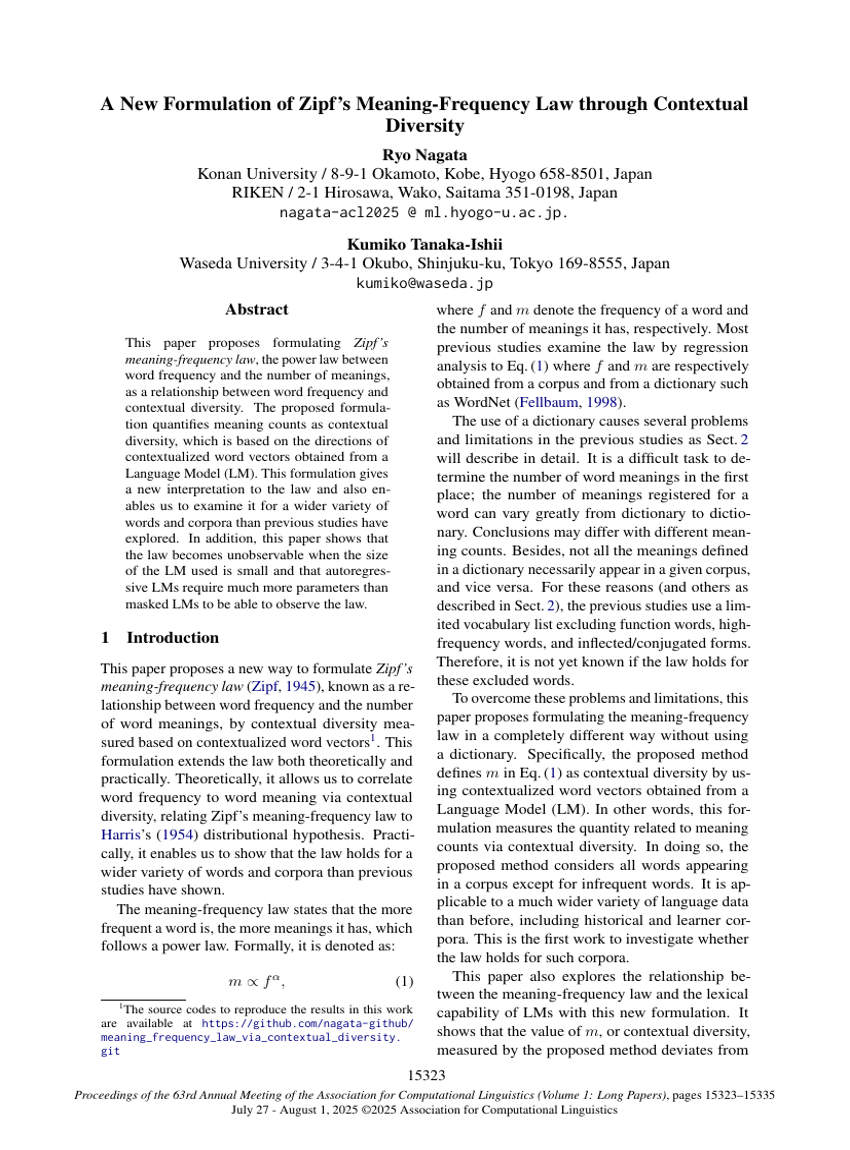
A New Formulation of Zipf's Meaning-Frequency Law through Contextual Diversity
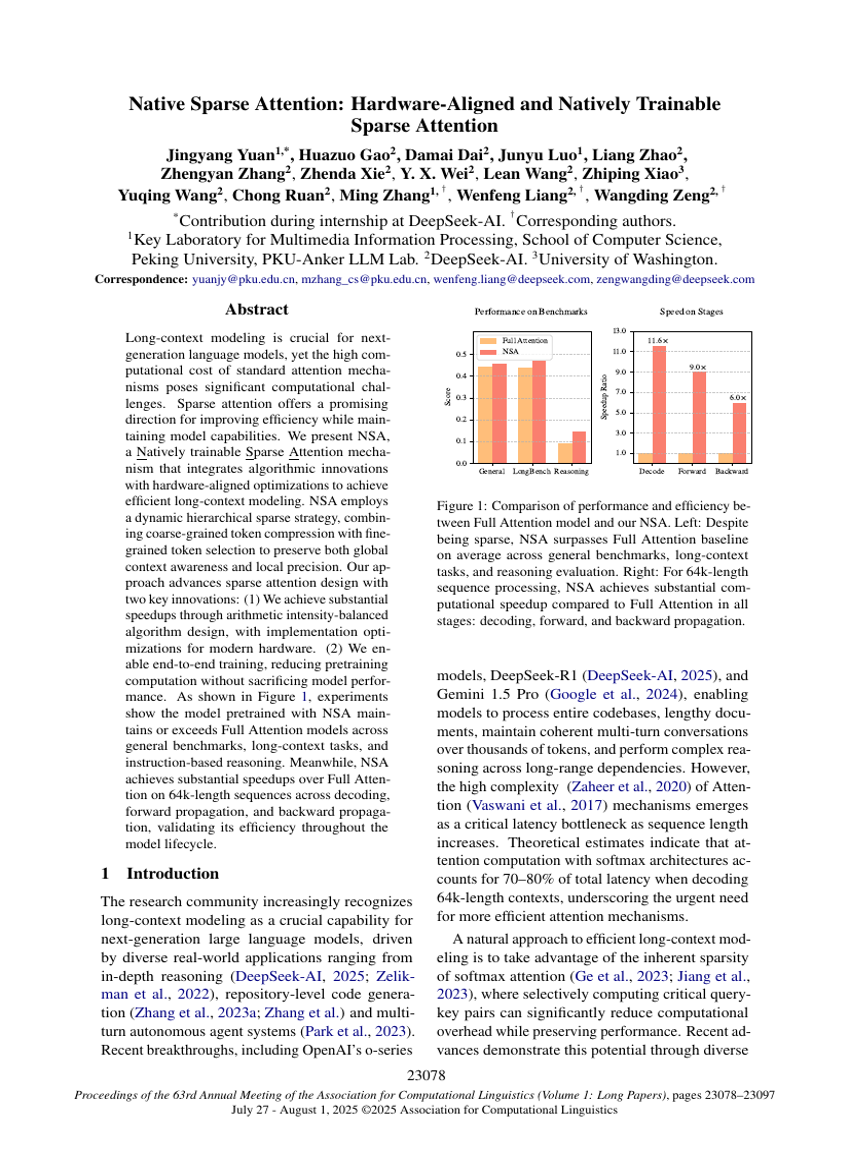
Native Sparse Attention: Hardware-Aligned and Natively Trainable Sparse Attention
Language Models Resist Alignment: Evidence From Data Compression
Fairness through Difference Awareness: Measuring Desired Group Discrimination in LLMs
A Theory of Response Sampling in LLMs: Part Descriptive and Part Prescriptive
Byte Latent Transformer: Patches Scale Better Than Tokens
Toward Automatic Discovery of a Canine Phonetic Alphabet
PARME: Parallel Corpora for Low-Resourced Middle Eastern Languages