HyperAI
Command Palette
Search for a command to run...
Papers
Daily updated cutting-edge AI research papers to help you keep up with the latest AI trends
papers
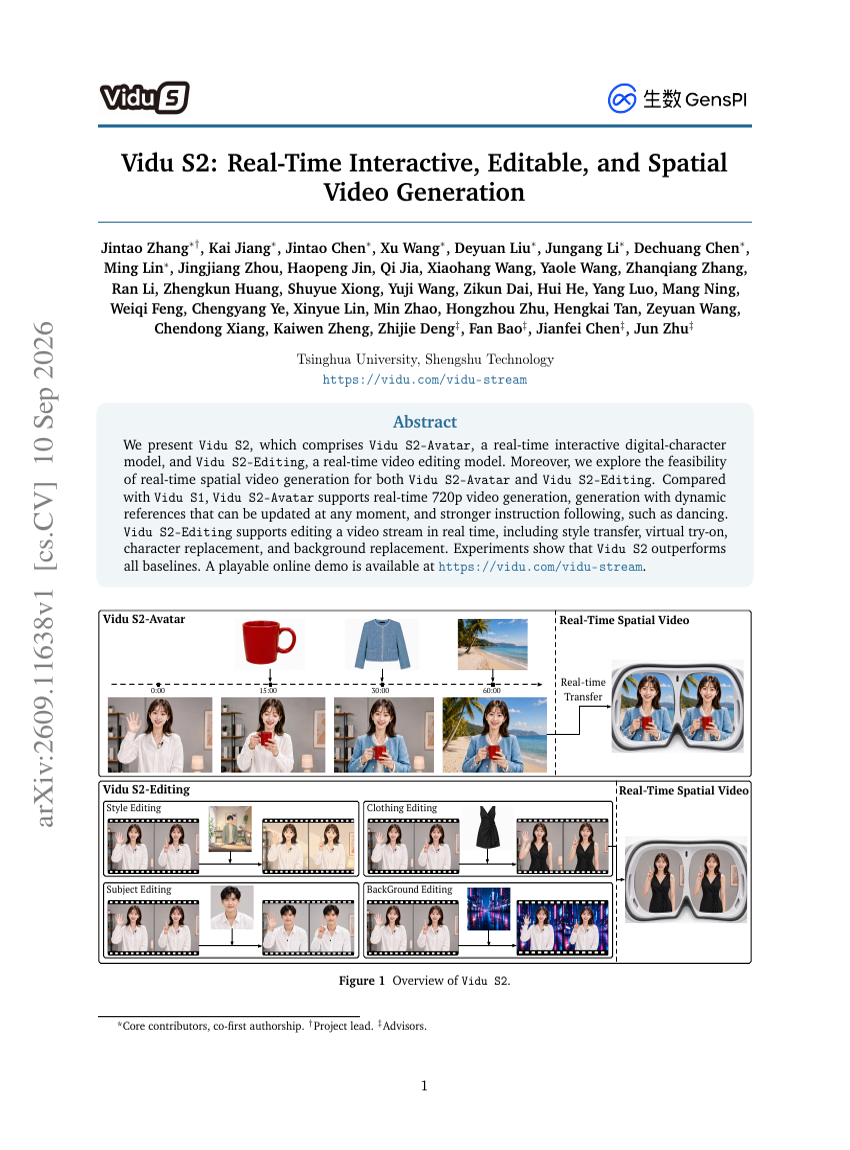
Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation
AI in Science: Early Insights
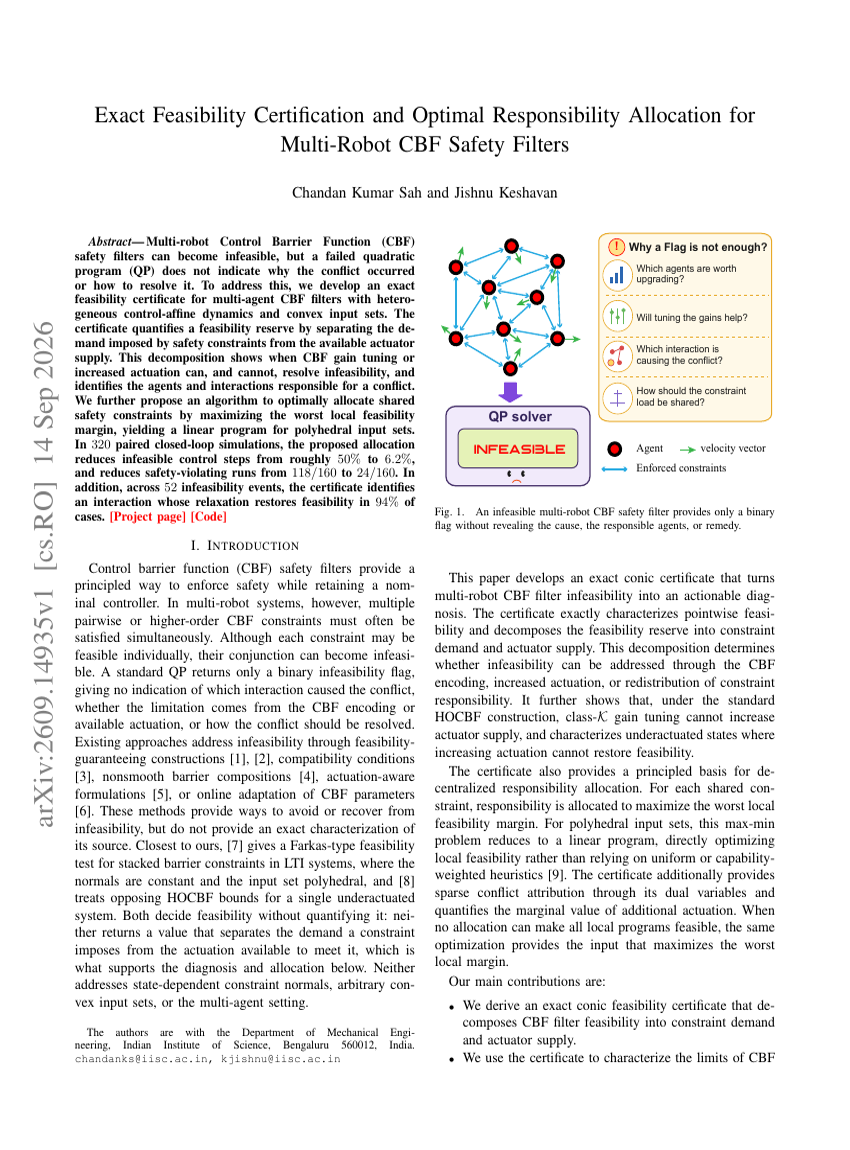


Exact Feasibility Certification and Optimal Responsibility Allocation for Multi-Robot CBF Safety Filters
CROSS-BLOCK CONDITIONING IN DEEP BOLTZMANN MACHINES FOR STATISTICAL DATA FUSION
The Complexity of Weak Partition Connectivity in Hedgegraphs
Accelerated Local Algorithms for Personalized and Regularized PageRank
Geometric Signatures of Conceptual Reorganization: A Counterfactual Embedding Framework for Detecting Scientific Revolutions
RSIAgent: Autonomous Exploration for Recursive Self-improvement in New Environments
Breaking the Token Ceiling: Distilling Smaller, Stronger Byte Models
COBRA-SKILLS: CONTEXTUAL BANDIT-GUIDED EVOLUTION FOR AGENT SKILL OPTIMIZATION
SAS: Simple Attention Sparsification via End-to-End Optimization of Context Ranking
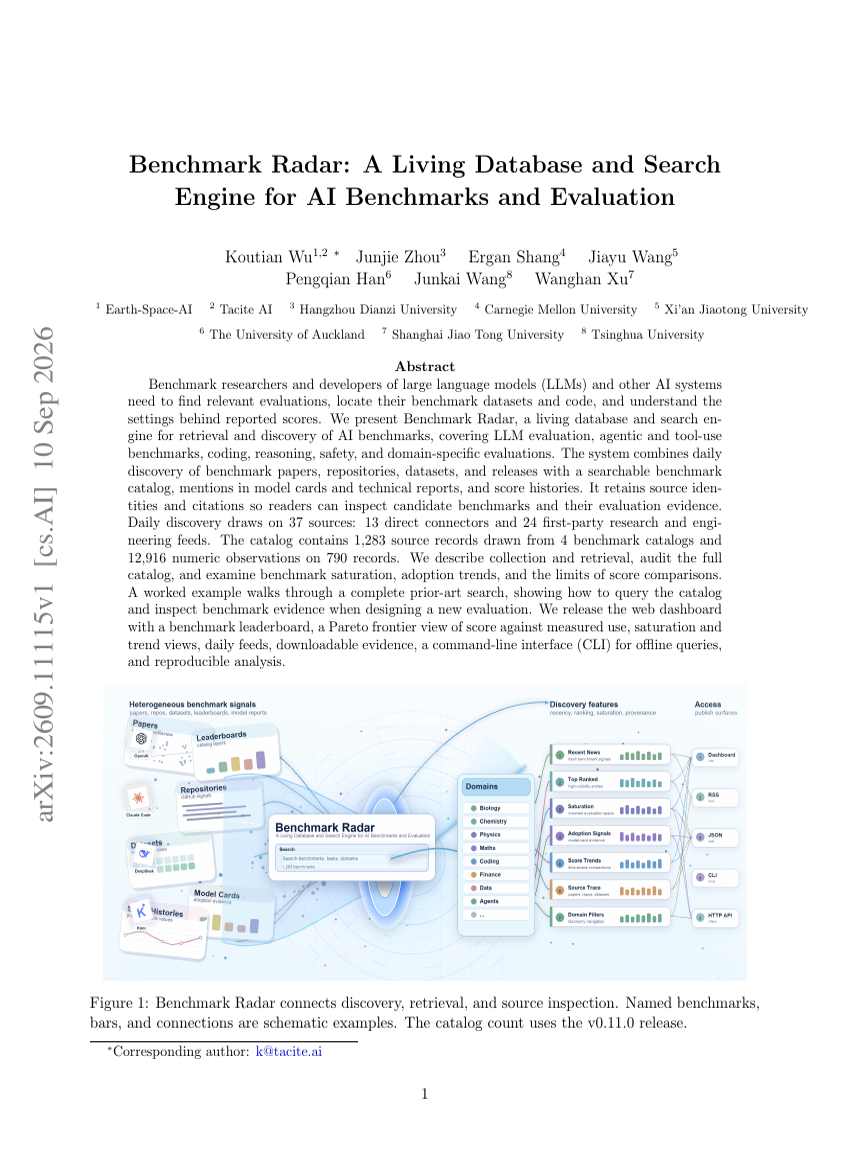
Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation
DataFlex-RL: An Evaluation Platform for RLVR Data Policies
Breaking the Vision–Action Shortcut: Latent Interface Training for Generalizable Robotics Foundation Models
Feyospace-v1: How the Cyber Mercury Seven Trained Frontier Cyber Models
X-AuT: Progressive Audio-Encoder Compression for Speech LLMs with Cross-Scale Distillation
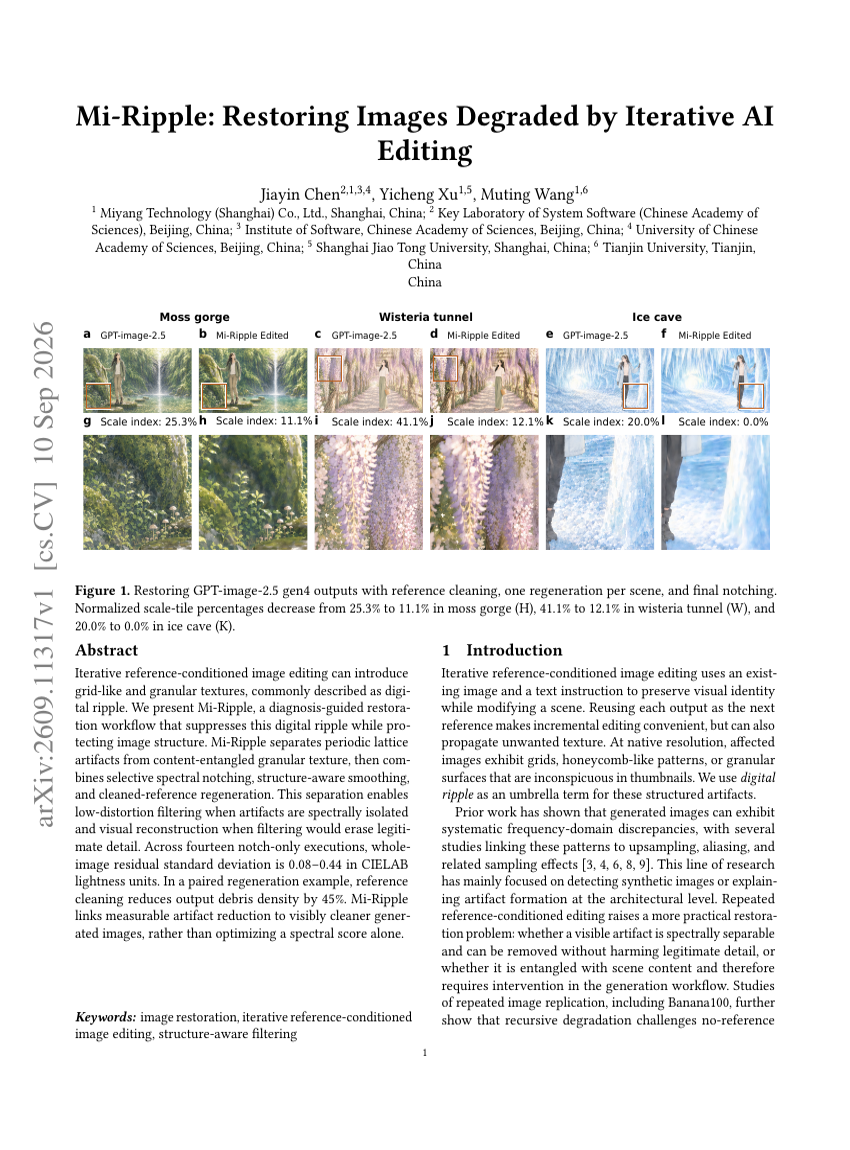
Mi-Ripple: Restoring Images Degraded by Iterative AI Editing
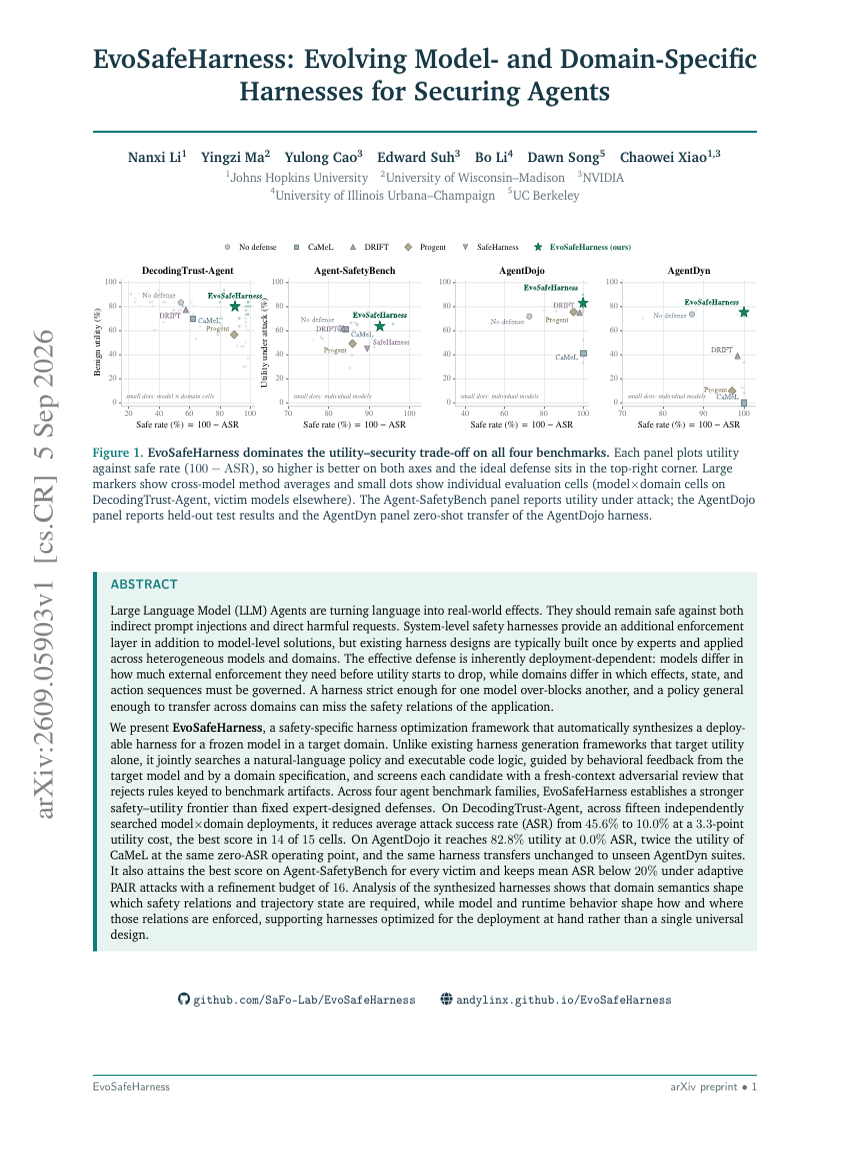
EvoSafeHarness: Evolving Modeland Domain-Specific Harnesses for Securing Agents
SpatialBlock: Enhancing Spatial Intelligence in LVLMs via Synthetic Block-Stacking Problem
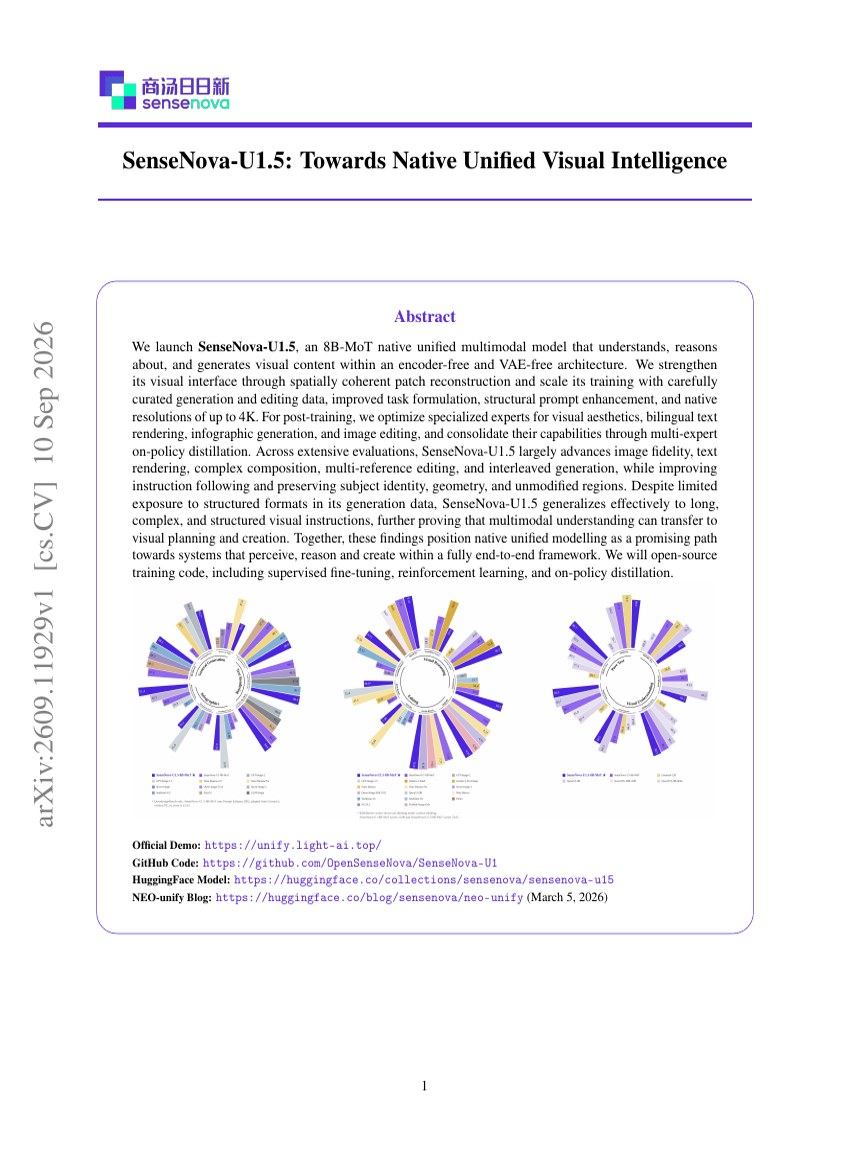
SenseNova-U1.5: Towards Native Unified Visual Intelligence
NCP-ArchPreview Technical Report: Moving towards Latent Space Language Models through Next Concept Prediction
SAESCIENTIST-BENCH: CAN AI AGENTS CONDUCT AUTONOMOUS SAE INTERPRETABILITY RESEARCH?
SWE-Bench Pro Verified: A Reliable Benchmark for Software Engineering Agents
WearableQA: A Benchmark for Health Reasoning over Real-World Wearable Data
AgentGrad: Intervention-guided Prompt Optimization for Multi Agent Systems
Programmable World Model
Show-Harness: Just a VLM Agent Can Play Robots
Last Translation Benchmark
Vero: An Open RL Recipe for General Visual Reasoning
Data Science and Technology Towards AGI Part I: Tiered Data Management
APEX–Agents
TERMINAL-BENCH: BENCHMARKING AGENTS ON HARD, REALISTIC TASKS IN COMMAND LINE INTERFACES